
tntorch
rballester
312Sterne
Tensor Network Learning with PyTorch
Finde Frameworks zum Trainieren, Bewerten und Ausführen von Modellen und vergleiche das Community-Interesse.
rballester
Tensor Network Learning with PyTorch

rbonghi
🔩 Automatically script to setup and configure your NVIDIA Jetson [Nano, Xavier, TX2i, TX2, TX1, TK1] . This script run different modules to update, fix and patch the kernel, install ROS and other...

rcmalli
SqueezeNet implementation with Keras Framework

rdcolema
CNN for multi-class image recognition in tensorflow

re-search

Medical Q&A with Deep Language Models

reczoo
A configurable, tunable, and reproducible library for CTR prediction https://fuxictr.github.io

redis-developer
✨ A curated list of awesome community resources, integrations, and examples of Redis in the AI ecosystem.

RedisAI
A Redis module for serving tensors and executing deep learning graphs

regel
Loud ML is the first open-source AI solution for ICT and IoT automation

reiniscimurs

Deep Reinforcement Learning for mobile robot navigation in ROS Gazebo simulator. Using Twin Delayed Deep Deterministic Policy Gradient (TD3) neural network, a robot learns to navigate to a random goal point in a simulated environment while avoiding obstacles.

Relph1119
周志华-机器学习

remicnrd

A 5-pages only Machine Learning cheatsheet focusing on the most popular algorithms under the hood

remsky
Dockerized OpenAI-compatible wrapper for Kokoro-82M text-to-speech w/multiplatform CPU, AMD, NVIDIA GPU PyTorch; multi-speaker, clone-tuning, caption timestamps, SSML, websockets, optional readalong web UI

rentainhe
a collection of visualization function

Replicable-MARL
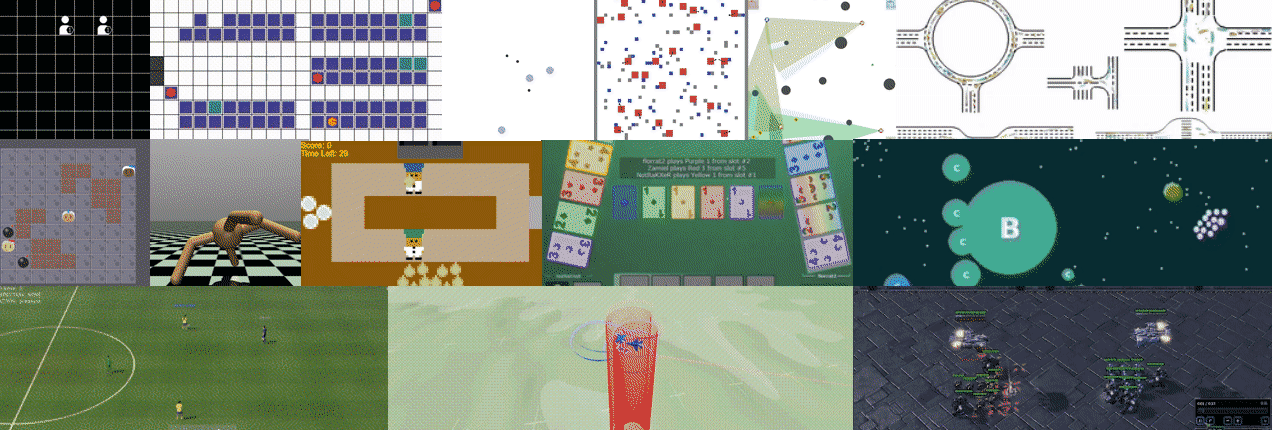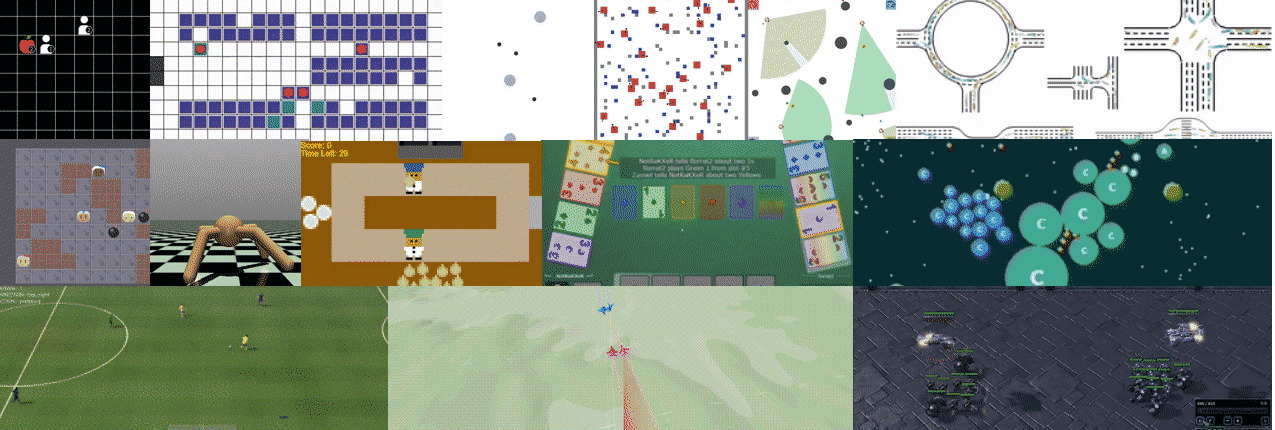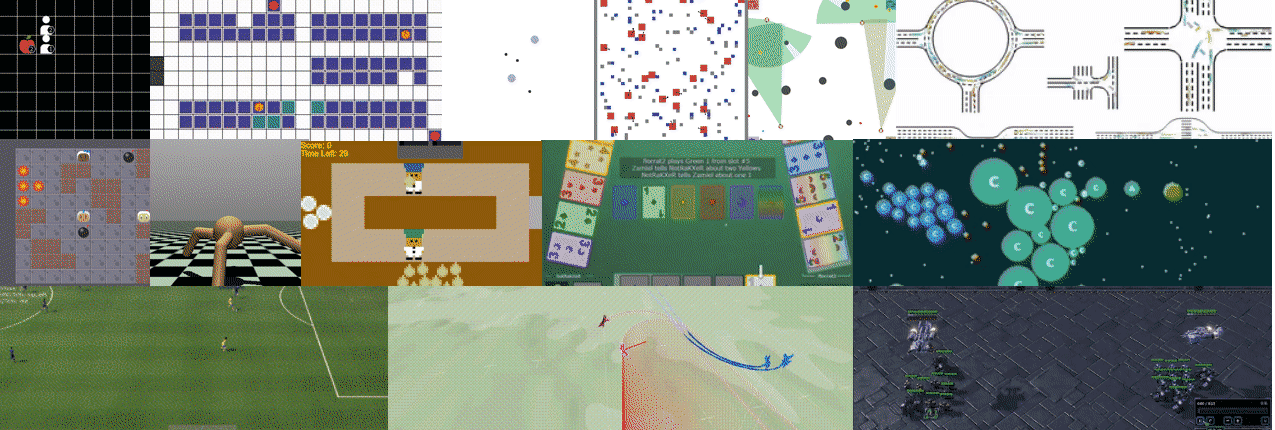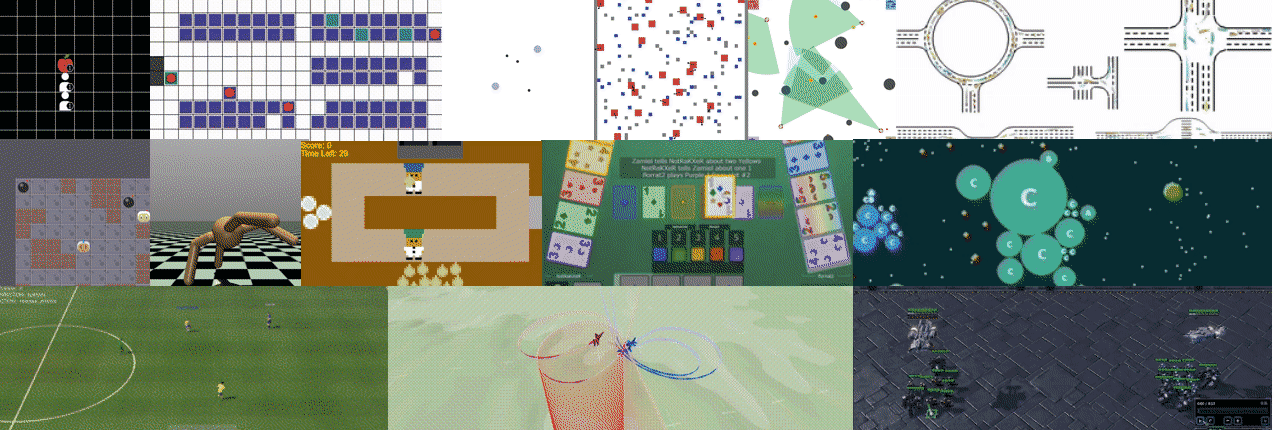
One repository is all that is necessary for Multi-agent Reinforcement Learning (MARL)

replicate

Version control for machine learning

resemble-ai

A python package to analyze and compare voices with deep learning

reservoirpy
A simple and flexible code for Reservoir Computing architectures like Echo State Networks

ReversecLabs
CAPTCHA22 is a toolset for building, and training, CAPTCHA cracking models using neural networks.

rewonc
Simple, realtime visualization of neural network training performance.

rgeirhos
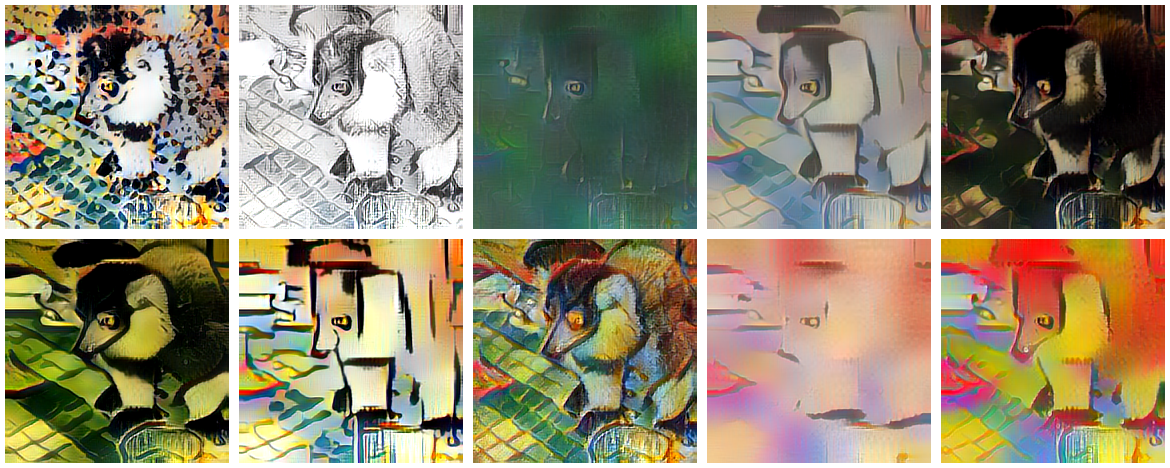
Code to create Stylized-ImageNet, a stylized version of standard ImageNet (ICLR 2019 Oral)
rgeirhos
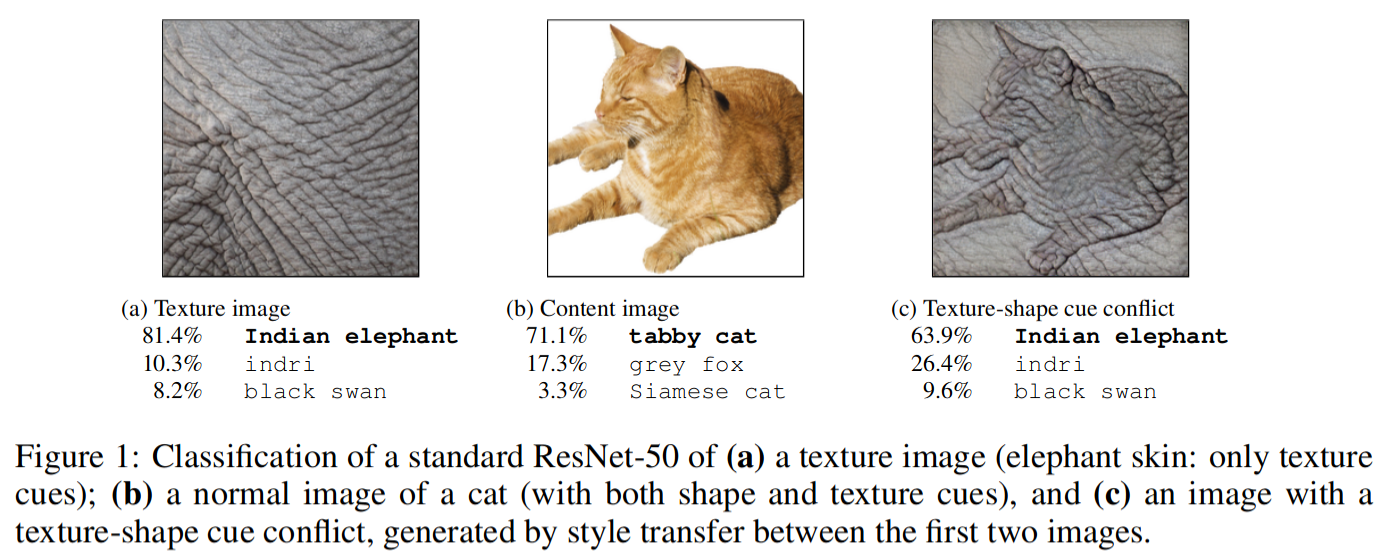
Pre-trained models, data, code & materials from the paper "ImageNet-trained CNNs are biased towards texture; increasing shape bias improves accuracy and robustness" (ICLR 2019 Oral)

RGF-team
Home repository for the Regularized Greedy Forest (RGF) library. It includes original implementation from the paper and multithreaded one written in C++, along with various language-specific wrappers.
Repository of teaching materials, code, and data for my data analysis and machine learning projects.
