
blaze-persistence
Blazebit
865Sterne
Rich Criteria API for JPA providers
- Use CTEs and recursive CTEs
- Use modification CTEs aka DML in CTEs
Vergleiche Datenbanken, Analysen, SQL- und Data-Engineering-Projekte.
Blazebit
Rich Criteria API for JPA providers

blazer82
Official repository for Analytodon

BlazingDB

BlazingSQL is a lightweight, GPU accelerated, SQL engine for Python. Built on RAPIDS cuDF.

blike
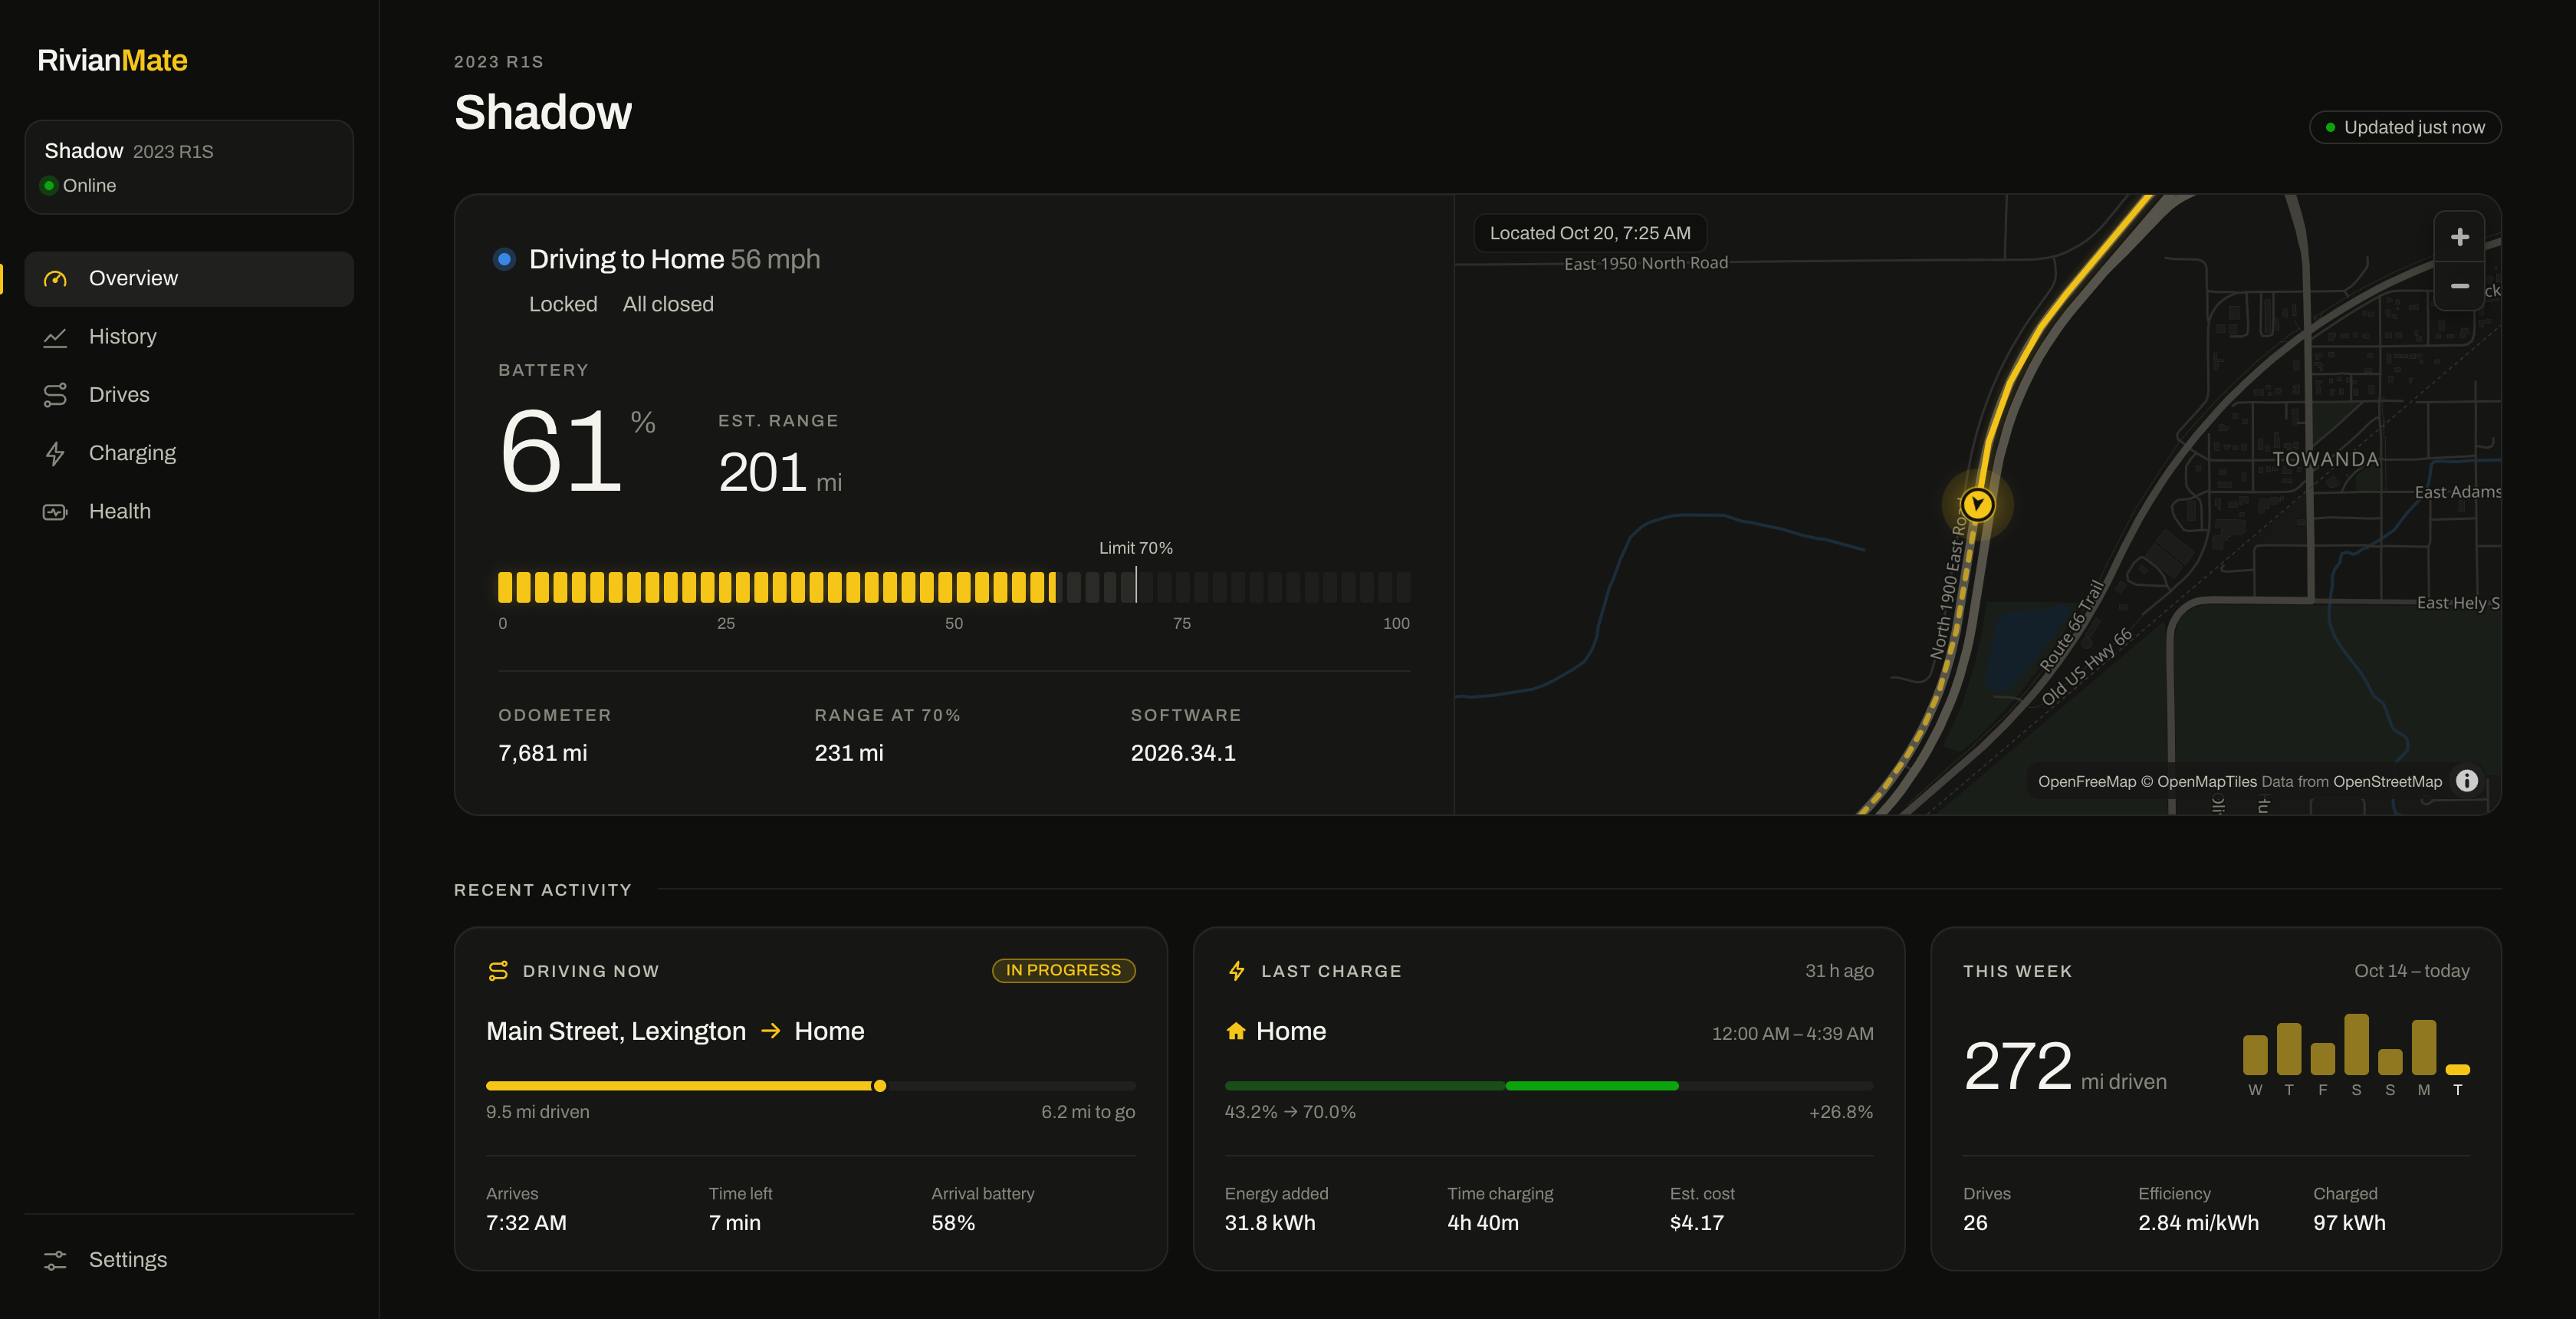
Self-hosted data logger and dashboard for Rivian vehicles: drives, charging sessions, vehicle health, and more stored in your own database

BlinkTagInc
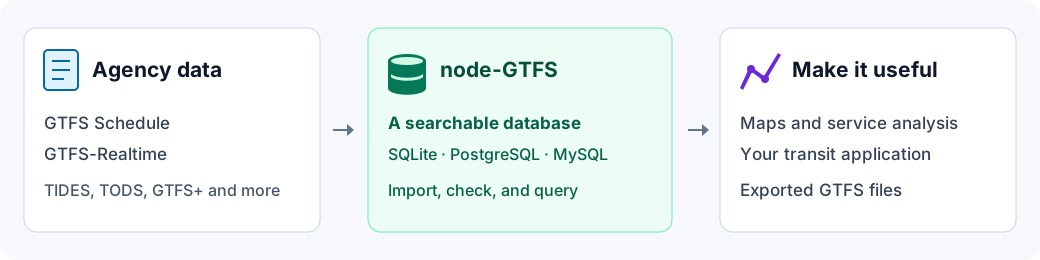
Import, validate, query, and export GTFS Schedule and Realtime data with SQLite, PostgreSQL, and MySQL.

blockchain-etl
Useful SQL queries for Blockchain ETL datasets in BigQuery.
blockchain-etl
ETL scripts for Bitcoin, Litecoin, Dash, Zcash, Doge, Bitcoin Cash. Available in Google BigQuery https://goo.gl/oY5BCQ
blockchain-etl
Airflow DAGs for https://github.com/blockchain-etl/bitcoin-etl
blockchain-etl

Blockchain ETL Architecture
blockchain-etl
Streaming Ethereum and Bitcoin blockchain data to Google Pub/Sub or Postgres in Kubernetes
blockchain-etl
Python scripts for ETL (extract, transform and load) jobs for Ethereum blocks, transactions, ERC20 / ERC721 tokens, transfers, receipts, logs, contracts, internal transactions. Data is available in Google BigQuery https://goo.gl/oY5BCQ
blockchain-etl
Airflow DAGs for exporting, loading, and parsing the Ethereum blockchain data. How to get any Ethereum smart contract into BigQuery https://towardsdatascience.com/how-to-get-any-ethereum-smart-contract-into-bigquery-in-8-mins-bab5db1fdeee
blockchain-etl
ethers.js library, compiled for use in Google BigQuery
blockchain-etl

ETL (extract, transform and load) tools for ingesting Polygon blockchain data to Google BigQuery and Pub/Sub
blockchain-etl
The list of public blockchain datasets in BigQuery

blockloop
Tiny lib to scan SQL rows directly to structs, slices, and primitive types

bloomberg
Python API to Bloomberg's comdb2 database.

blue-yonder

Automatic extraction of relevant features from time series:
blue-yonder
Turbodbc is a Python module to access relational databases via the Open Database Connectivity (ODBC) interface. The module complies with the Python Database API Specification 2.0.

bluenimble

BlueNimble is a Hybrid Serverless Platform focusing on developer productivity and application portability. Create and run scalable APIs and applications without coding or by coding less. Focus on application business logic without any knowledge of the underlying microservices architecture.

BMDan
MySQL Tuning-Primer.sh, updated and improved

bmeares
Create and manage data pipes with Meerschaum.

bobbyiliev

Materialize is a streaming database for real-time analytics. This is a collection of Materialize demos and tutorials.

bodo-ai

High Performance Scalable Data Processing in Python and SQL