Skip to content
Projektkategorien

Daten · GitHub

Vergleiche Datenbanken, Analysen, SQL- und Data-Engineering-Projekte.

Nützliche GitHub-Projekte

4,889 Projekte
717Sterne
Java-JavaFx-Swing-Projects-Desktop-Application-GUI-Software preview

All projects are based on ☕ Java(Swing.All projects are database(MySql) connected📂 and compatible to run is🖥️ Desktop(with .exe)🖱️.All projects have a Graphical User Interface(GUI)👨🏻‍💻 that user can communicate and understand the application easily).

30Sterne
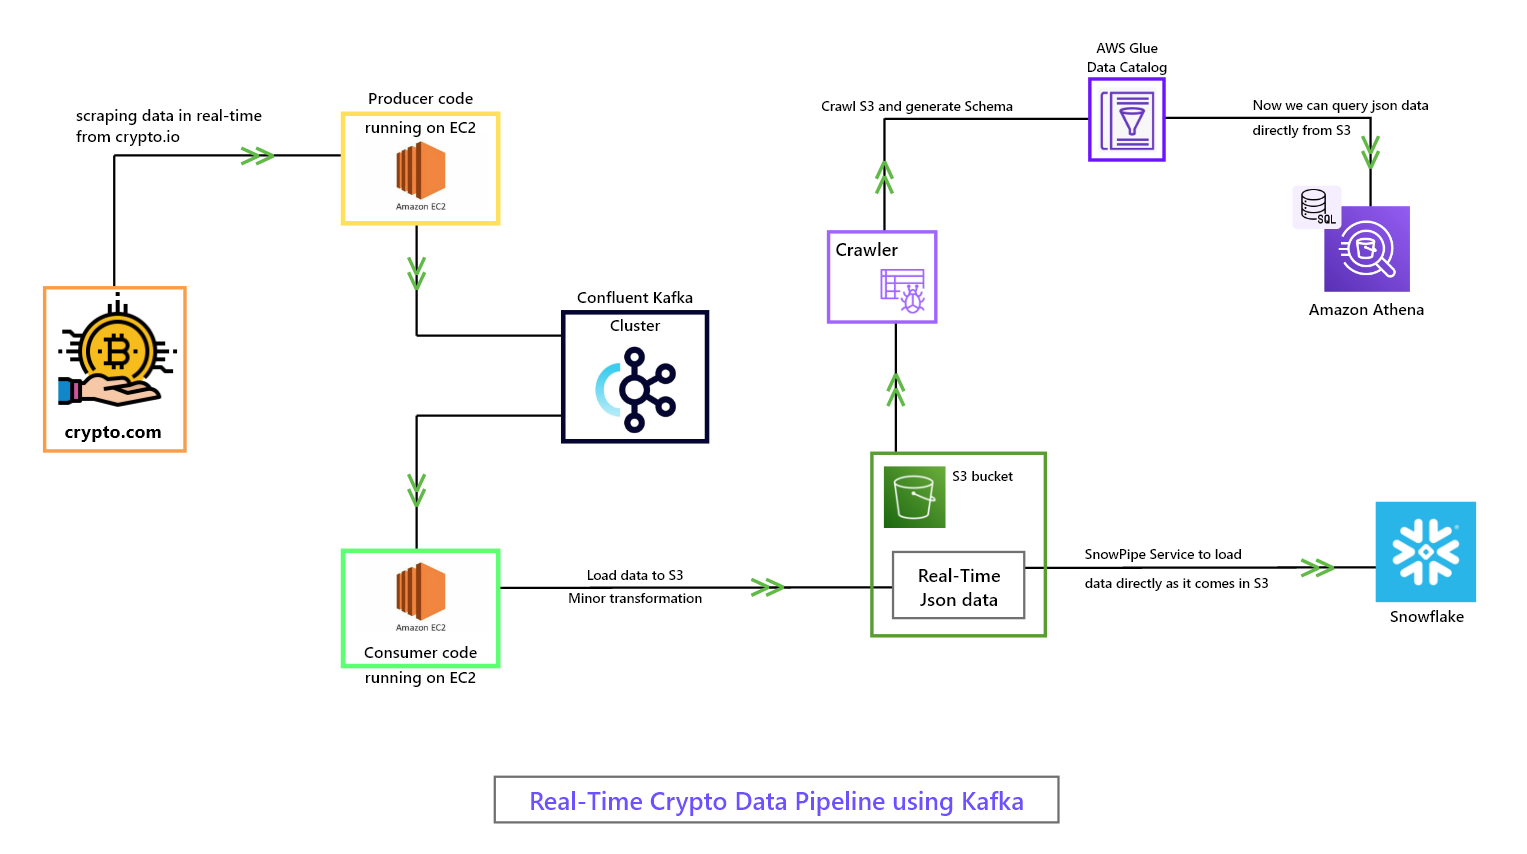
real-time_crypto_data_pipeline_using_kafka preview

I am using confluent Kafka cluster to produce and consume scraped data. In this project, I've created a real-time data pipeline that utilizes Kafka to scrape, process, and load data onto S3 in JSON format. With a producer-consumer architecture, I ensure that the data is in the right format for loading onto S3 by performing minor transformations

DatenPythonCC0-1.0GitHub

slothdb

SouravRoy-ETL

412Sterne
slothdb preview

An experimental embedded SQL engine in C++20. Query Parquet, CSV, JSON, Arrow, Avro, SQLite, and Excel files directly with SQL, in-process. Early-stage.

  • SQL - 130+ features - JOINs, CTEs (recursive), window functions, QUALIFY, MERGE, subqueries, set operations
  • Live file views - CREATE LIVE VIEW caches the result and auto-refreshes on file change. Incremental CSV append path parses only new bytes on log-tail workloads

defradb

sourcenetwork

897Sterne
defradb preview

DefraDB is a Peer-to-Peer Edge-First Database. It's the core data storage system for the Source Ecosystem.

minarrow

SpaceCell

103Sterne

Fast, minimal, and ergonomic zero-copy Apache Arrow tabular data implementation in Rust, with PyO3, Python bindings, NdArray, XArray, shared-memory and low-latency SIMD for data-engineering and columnar workloads. Bridge to Polars and Arrow-rs over FFI effortlessly.

DatenRustApache-2.0GitHub

Wired

SpaceCell

44Sterne
Wired preview

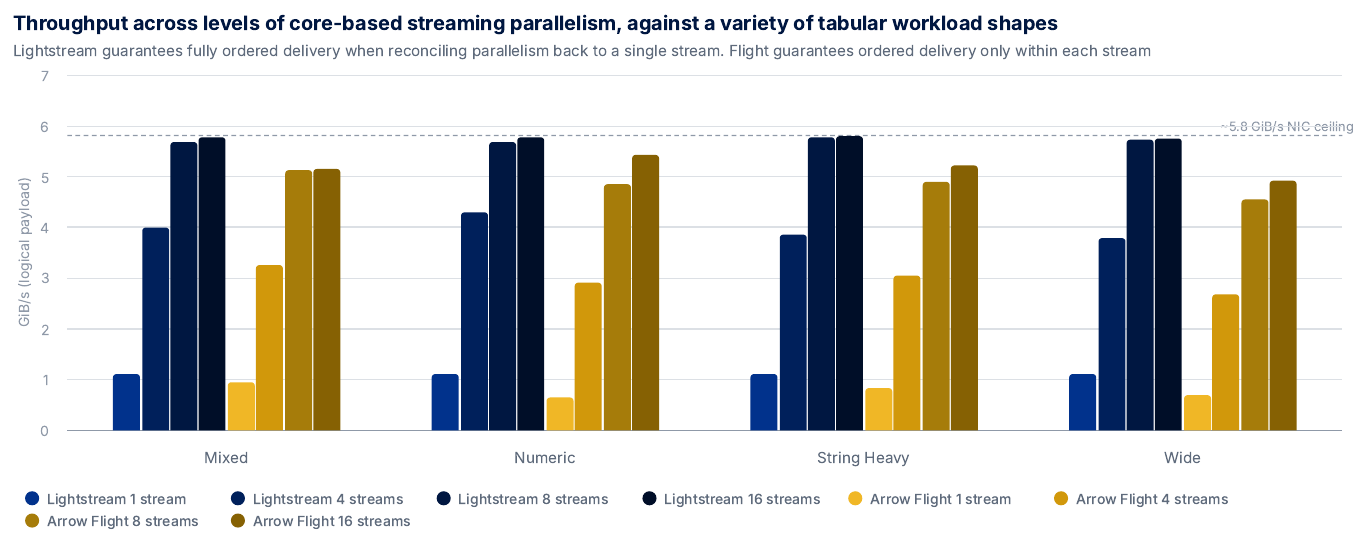
Fast data transport : Apache Arrow, Protobuf and Message Pack data on the one stream. Measured faster than Arrow Flight on all open benchmarks. HTTP, TCP, QUIC, Websocket, Webtransport, Stdio, UDS, all interchangeable, with 64-byte SIMD compatibilty maintained over the network and to/from disk via custom Arrow Mmap and Parquet Readers and Writers

space-cloud

spacecloud-io

4,000Sterne
space-cloud preview

Open source Firebase + Heroku to develop, scale and secure serverless apps on Kubernetes

  • Powerful CRUD: Flexible queries, transactions, aggregations and cross-database joins
  • Realtime: Make live queries to your database
DatenGoApache-2.0GitHub

sled

spacejam

9,112Sterne
sled preview

Der Champagner unter den Beta-Embedded-Datenbanken

  • API similar to a threadsafe BTreeMap<[u8], [u8]>
  • serializable (ACID) transactions for atomically reading and writing to multiple keys in multiple keyspaces.
DatenRustApache-2.0GitHub

learndb-py

spandanb

1,319Sterne

Learn database internals by implementing it from scratch.

  • it has a rich sql (learndb-sql) with support for select, from, where, group by, having, limit, order by
  • custom lexer and parser built using lark

jackcess

spannm

28Sterne

A pure Java library for reading / writing Microsoft Access databases

  • Pure Java: 100% Java implementation. No native dependencies, no DLLs, no MS Access installation required.
  • Wide Version Support: Supports Access versions 2000, 2003, 2007, 2010, 2013, 2016, and 2019.
DatenJavaApache-2.0GitHub
107Sterne

Open-source pure Java JDBC driver for Microsoft Access databases (*.accdb, *.mdb). Enables client programs (e.g. OpenOffice, LibreOffice, Matlab, SQuirreL) to read and write Access databases.

  • Pure Java Power: Zero native dependencies. Runs anywhere Java 11+ is supported.
  • Drop-in Replacement: Fully compatible with previous UCanAccess versions.
DatenJavaApache-2.0GitHub

spark-notebook

spark-notebook

3,136Sterne
spark-notebook preview

Interactive and Reactive Data Science using Scala and Spark.

DatenJavaScriptApache-2.0GitHub

sparkdq

sparkdq-community

77Sterne

A lightweight, declarative PySpark framework for data quality validation — check columns, rows, and entire datasets directly in your Spark pipelines

DatenPythonApache-2.0GitHub

sparklabx

sparklabx

32Sterne
sparklabx preview

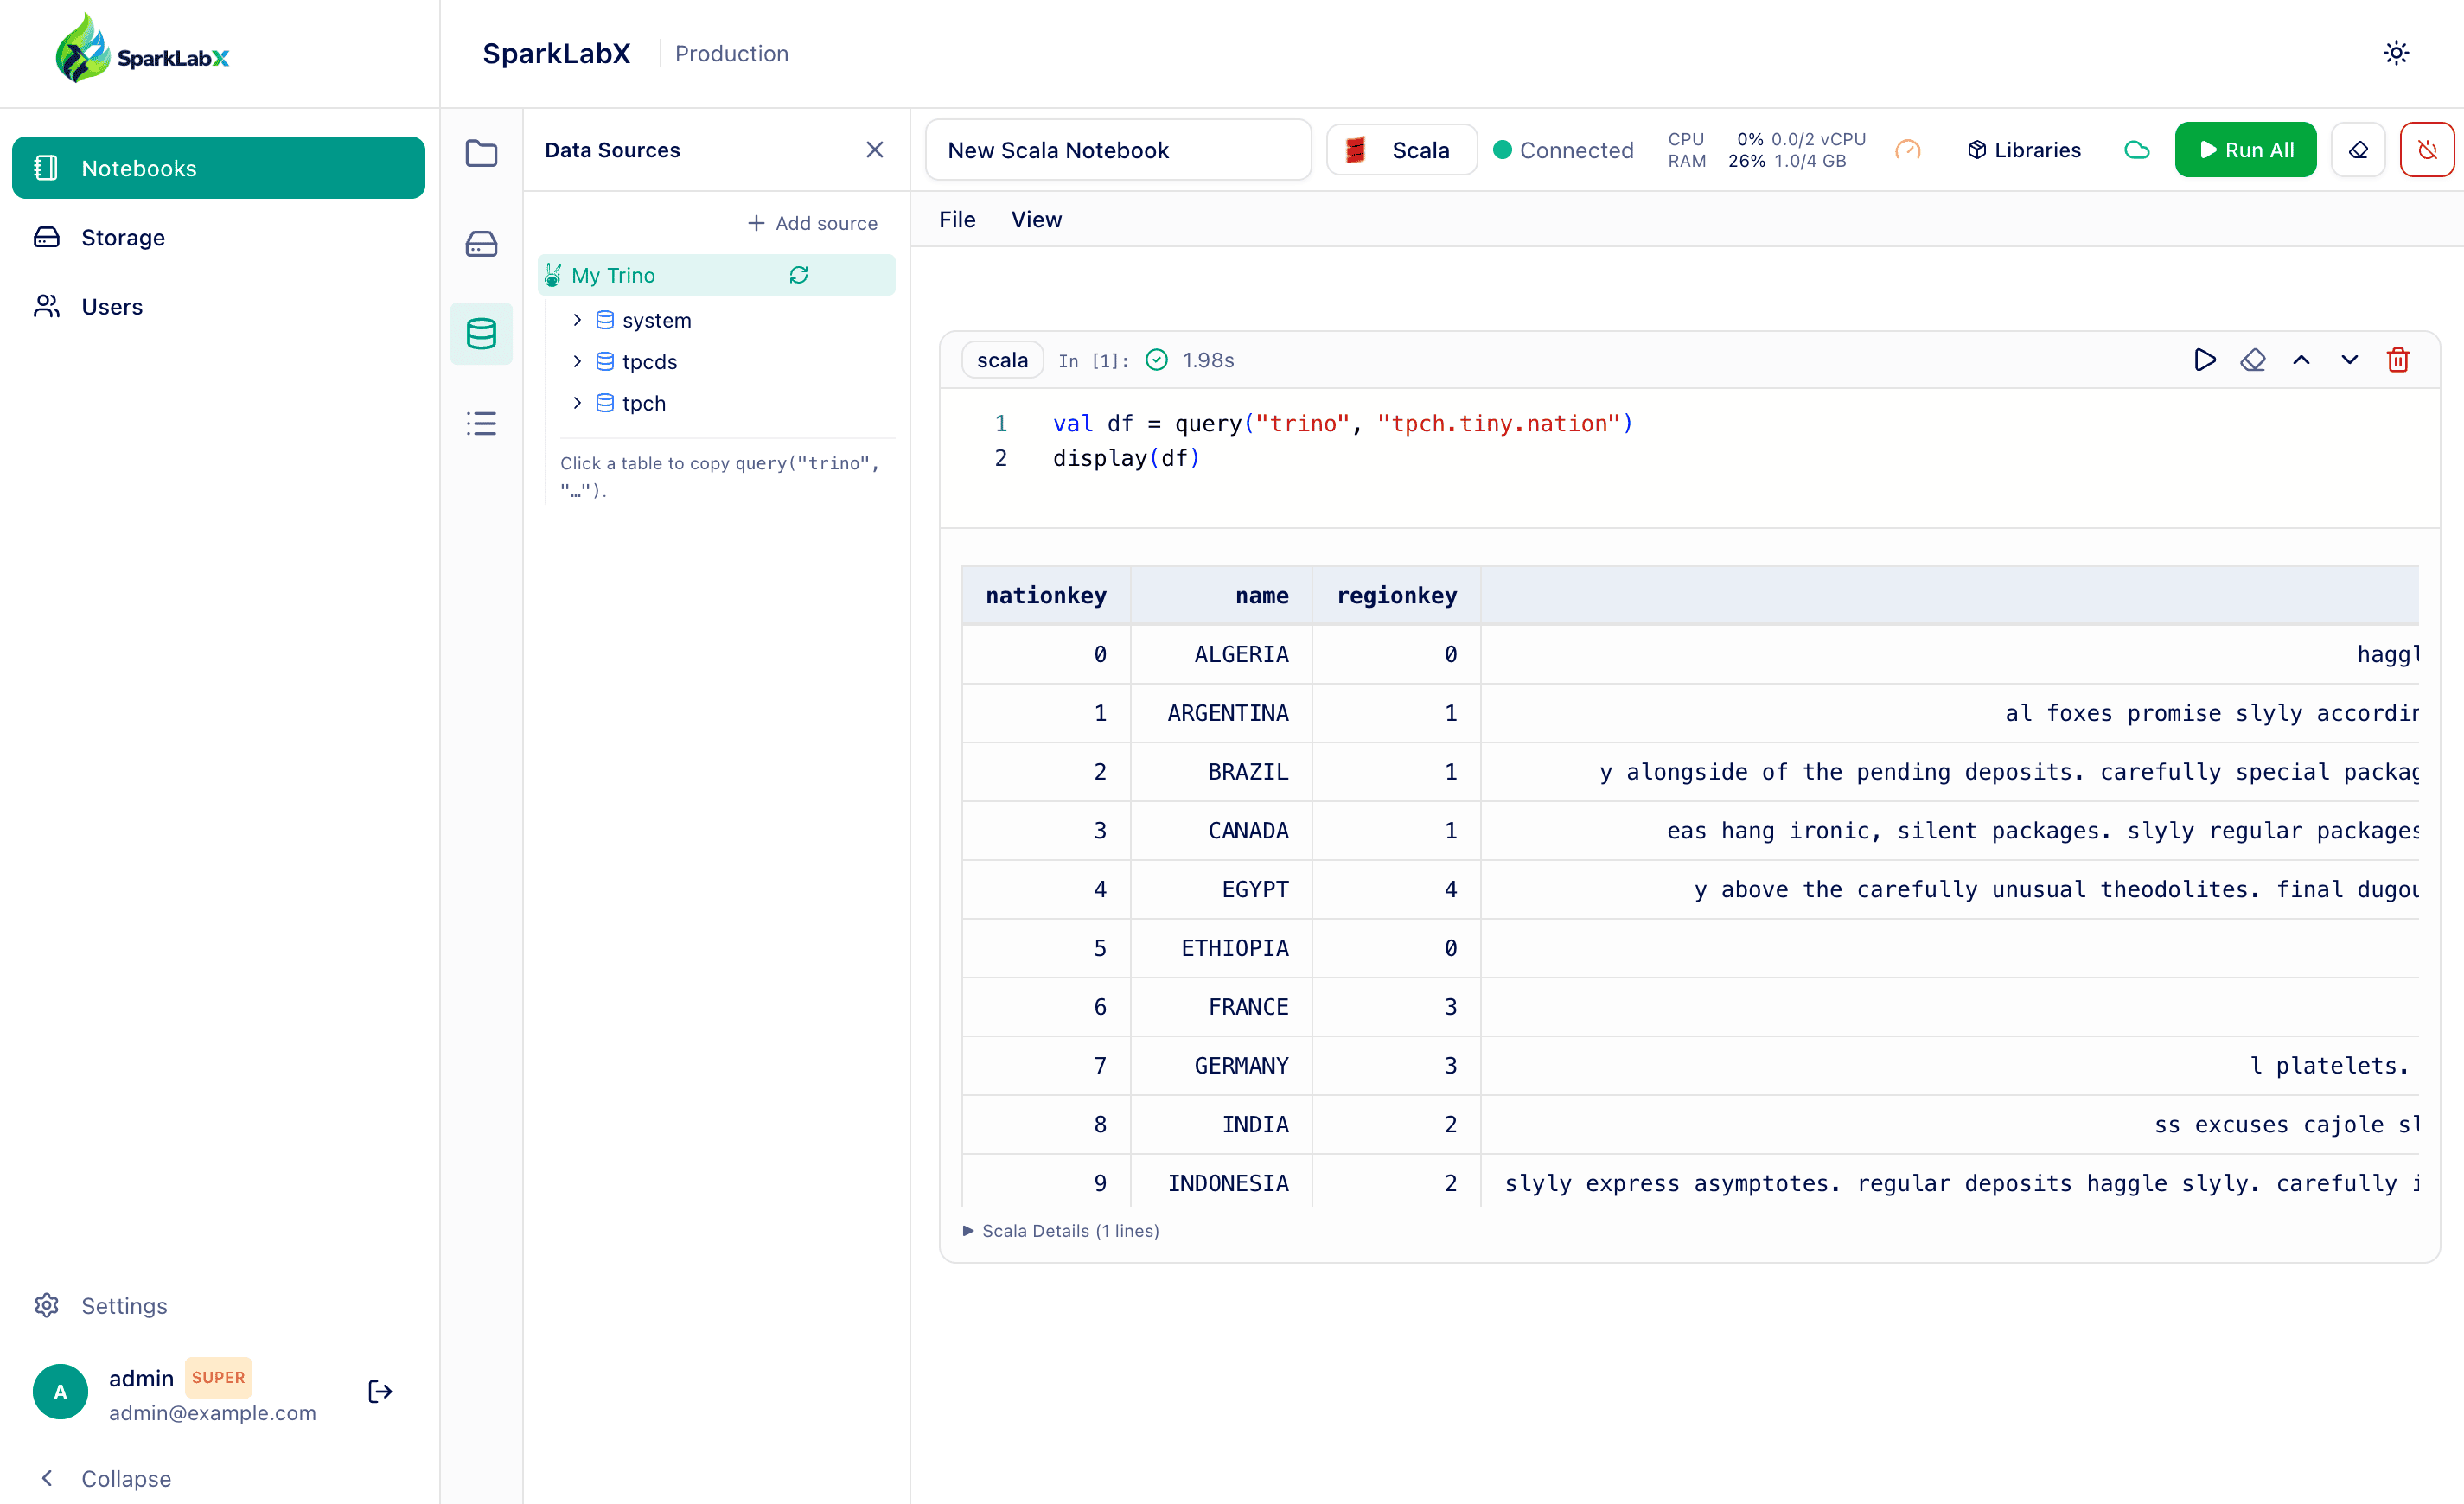
Self-hosted multi-user Apache Spark notebooks — PySpark + Scala, per-user kernel pods, MinIO IAM storage, OAuth. One Helm install. Apache-2.0.

  • Spark notebooks in the browser — PySpark, Scala (Almond), with Monaco editor, Markdown cells, kernel restart, and a Libraries dialog that wraps spark.jars.packages / import $ivy so users add Maven coordinates without editing code.
  • Embedded Spark UI + DataFlint — open the kernel's Spark Web UI (DAGs, stages, SQL plans, metrics) in-app, no port-forward. DataFlint (a Spark performance plugin) is on by default for PySpark and Scala, adding a performance tab that flags slow stages, skew, and oversized scans.
DatenTypeScriptApache-2.0GitHub

gsocanalyzer

Sparsh1212

76Sterne
gsocanalyzer preview

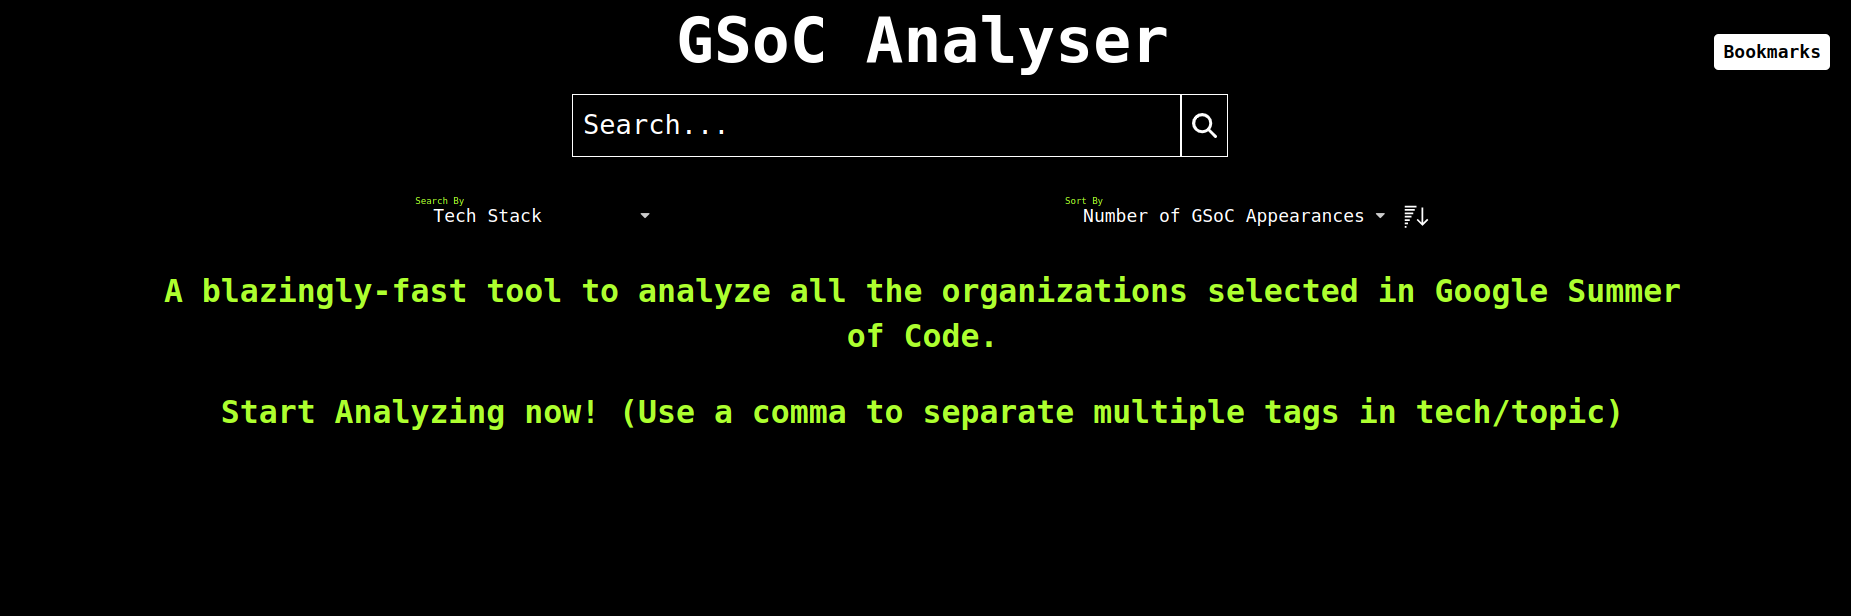
A blazingly fast tool to analyze all the selected organizations in Google Summer of Code in the form of graphical analytics.

DatenJavaScriptMITGitHub