Skip to content
Projektkategorien

Kreativität und Medien · GitHub

Entdecke Werkzeuge für Bilder, Video, Audio, Zeichnungen und 3D.

Nützliche GitHub-Projekte

16,898 Projekte

MediaEditor

opencodewin

505Sterne
MediaEditor preview

A non-linear editing software that helps you to make nice video.

  • Support Media Preview from Media Bank and Embedded File-Browser Support Media Management, including Searching, Sorting, and Classification Support Loading Media from Embedded File-Browser to Timeline
  • Support Media Preview from Media Bank and Embedded File-Browser

OpenGeometry

OpenGeometry-io

550Sterne

Geometry CAD Kernel for Humans and AI Agents

  • Primitives - Wires: rectangle, circle, polyline (open or closed), line-and-arc profile, arc. Solids: cuboid, cylinder, cylinder sector, sphere, cone or frustum, ring torus, planar polyhedron. Each can be placed on any plane.
  • Parametric edits - rebuild gives an existing body new parameters in place. mirror rebuilds a body as its reflection across a plane.

mapwidget

opengeos

255Sterne

Custom Jupyter widgets for creating interactive 2D/3D maps using popular JavaScript libraries with bidirectional communication, such as Cesium, Mapbox, MapLibre, Leaflet, and OpenLayers

Ask-Anything

OpenGVLab

3,362Sterne
Ask-Anything preview

[CVPR2024 Highlight][VideoChatGPT] ChatGPT mit Videoverständnis! Unterstützt außerdem viele weitere Sprachmodelle wie miniGPT4, StableLM und MOSS.

DragGAN

OpenGVLab

4,924Sterne
DragGAN preview

Inoffizielle Implementierung von DragGAN – „Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold“ (vollständige DragGAN-Implementierung mit Online-Demo und Möglichkeit zum Testen per lokaler Bereitstellung; Code und Modelle sind vollständig Open Source und werden unter Windows, macOS und Linux unterstützt)

Future-L1

OpenGVLab

39Sterne
Future-L1 preview

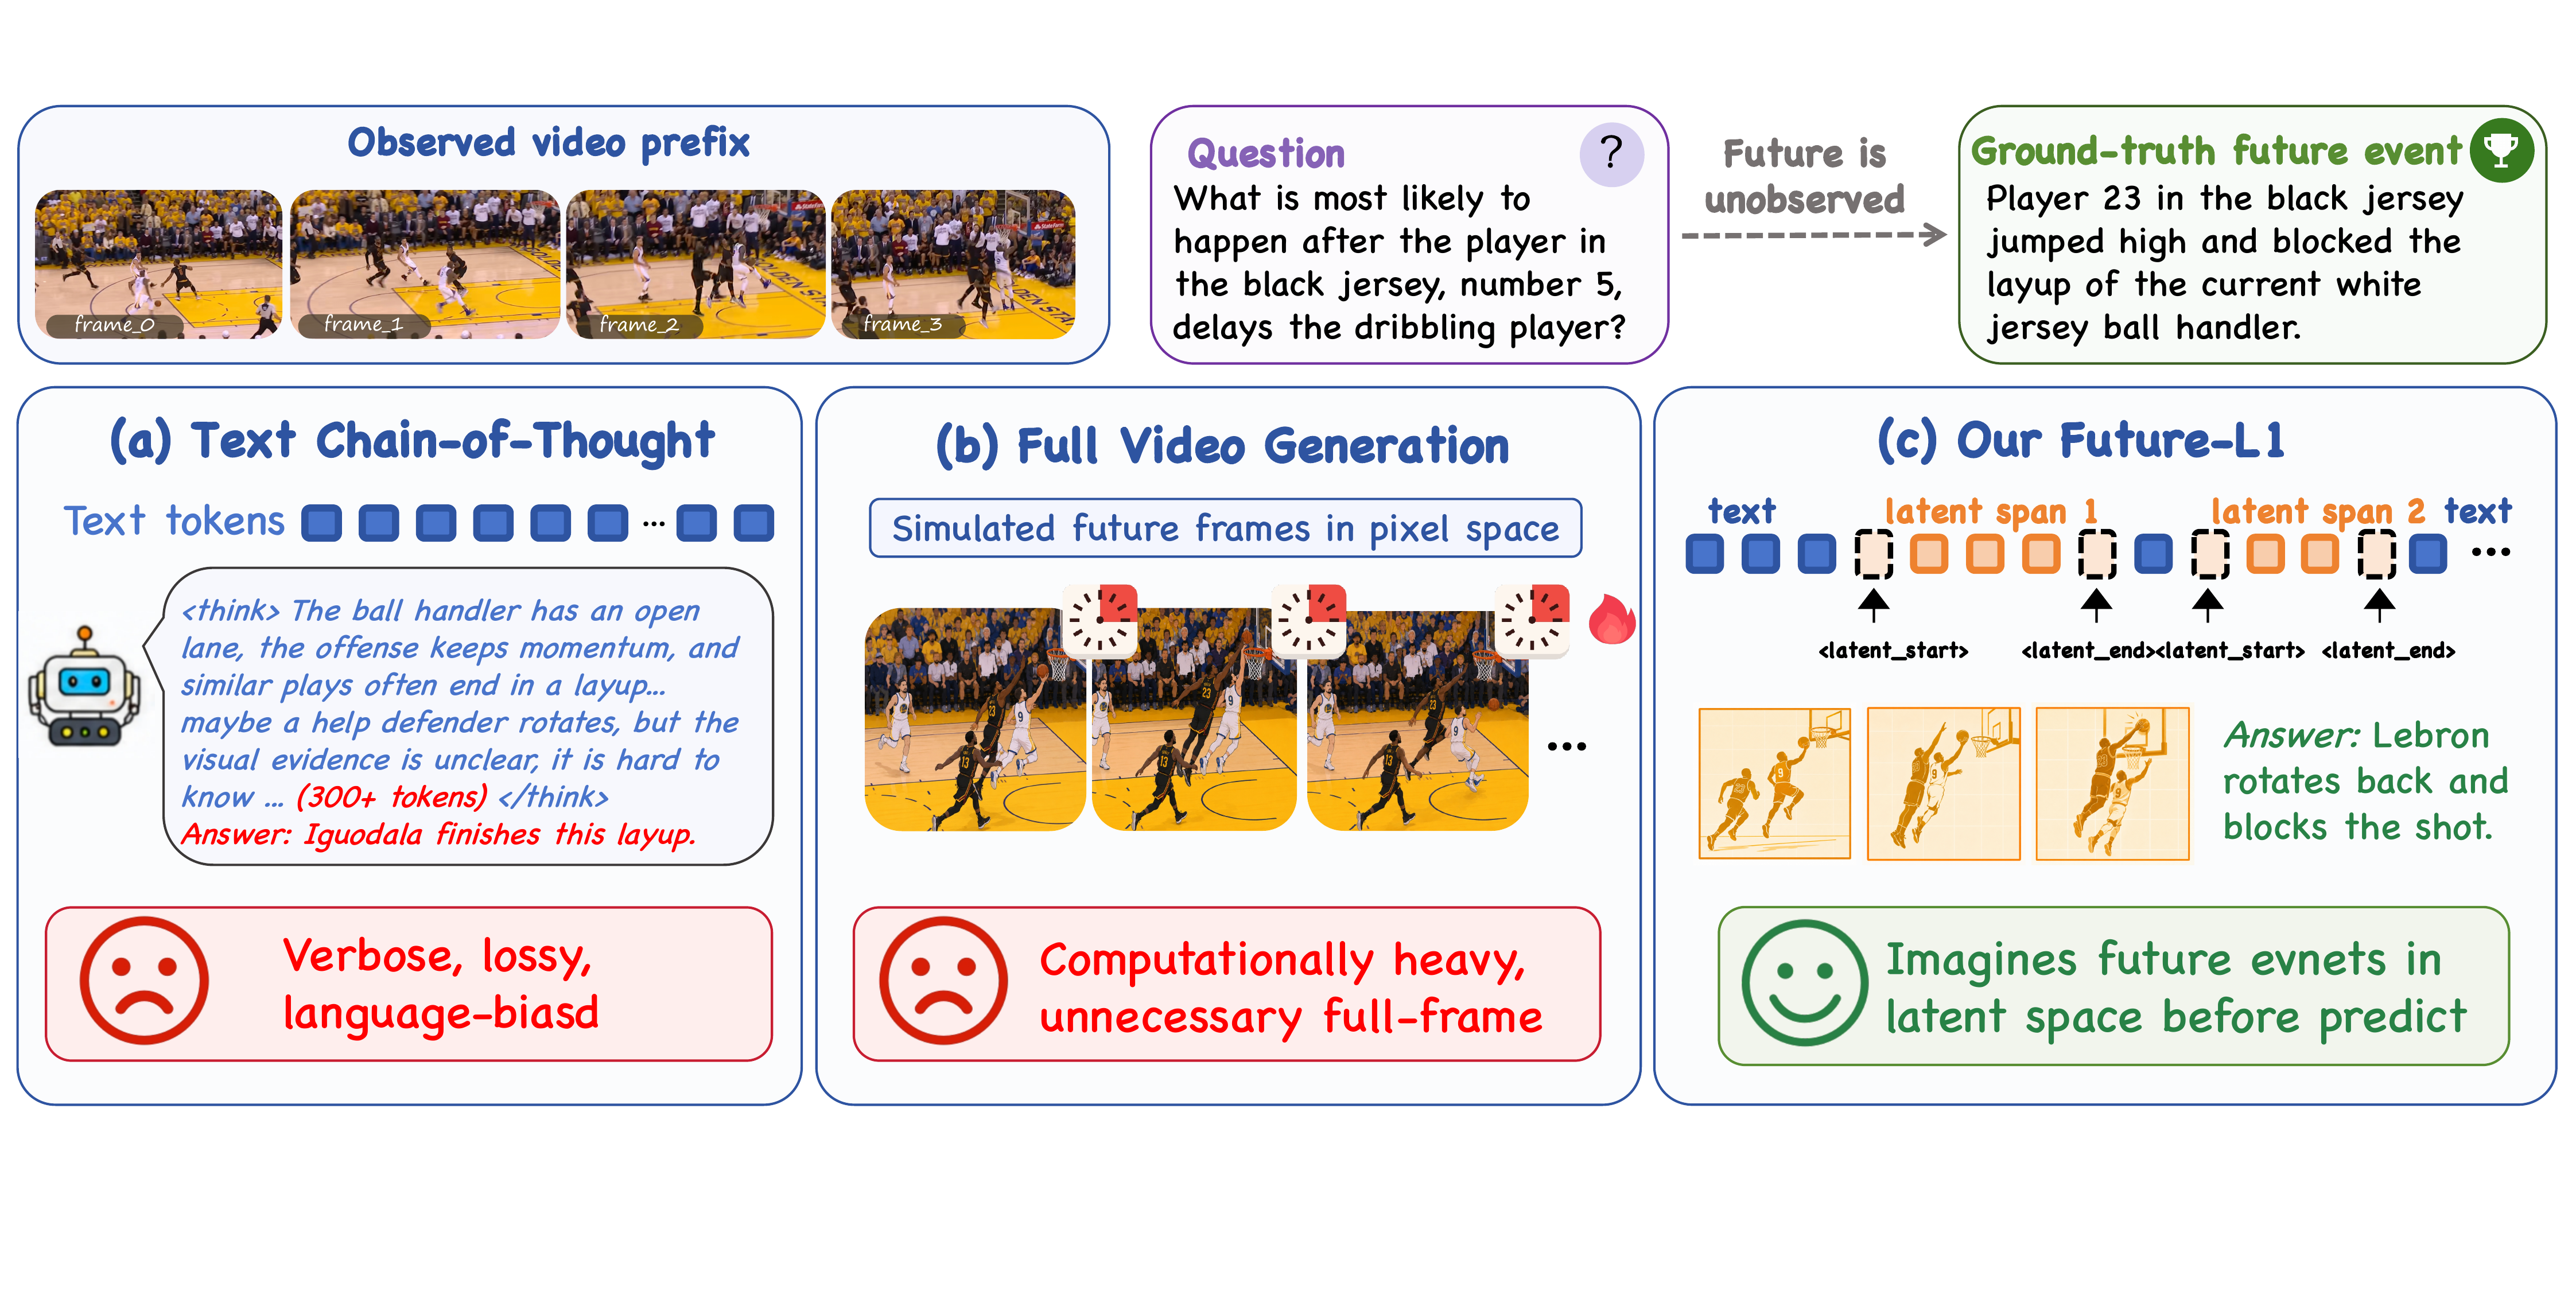
[EMNLP 2026 Main] Imagine Before You Predict: Interleaved Latent Visual Reasoning for Video Event Prediction

  • Interleaved latent visual reasoning. Future-L1 alternates between <reason> text and bounded <|latent_start|>…<|latent_end|> spans during autoregressive decoding, keeping dynamic visual structure in a continuous channel instead of verbalizing every intermediate hypothesis.
  • 🤗 Future-L1-50K. We curate 50K high-utility examples from TwiFF-style trajectories by visual-gain selection: retain samples where intermediate future visual hints measurably improve prediction over a text-only baseline.

InternVL-U

OpenGVLab

299Sterne

InternVL-U is a 4B-parameter unified multimodal model (UMM) that brings multimodal understanding, reasoning, image generation, image editing into a single framework.