
zsyOAOA/InvSR has 1,457 GitHub stars and 93 forks. GitHot measured +1 in 7 days. Last checked 2026-11-10 04:13 UTC. Last push 2026-02-07.
So werden diese Zahlen gemessen
Arbitrary-steps Image Super-resolution via Diffusion Inversion (CVPR 2025)
Gemessener Sternzuwachs
- in 24h
- Aktualisierung verzögert
- in 7 days
- +1
- in 15 days
- Aktualisierung verzögert
- in 1 month
- Aktualisierung verzögert
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
README.md
OriginalArbitrary-steps Image Super-resolution via Diffusion Inversion (CVPR 2025)
Zongsheng Yue, Kang Liao, Chen Change Loy


:star: If you've found InvSR useful for your research or projects, please show your support by starring this repo. Thanks! :hugs:
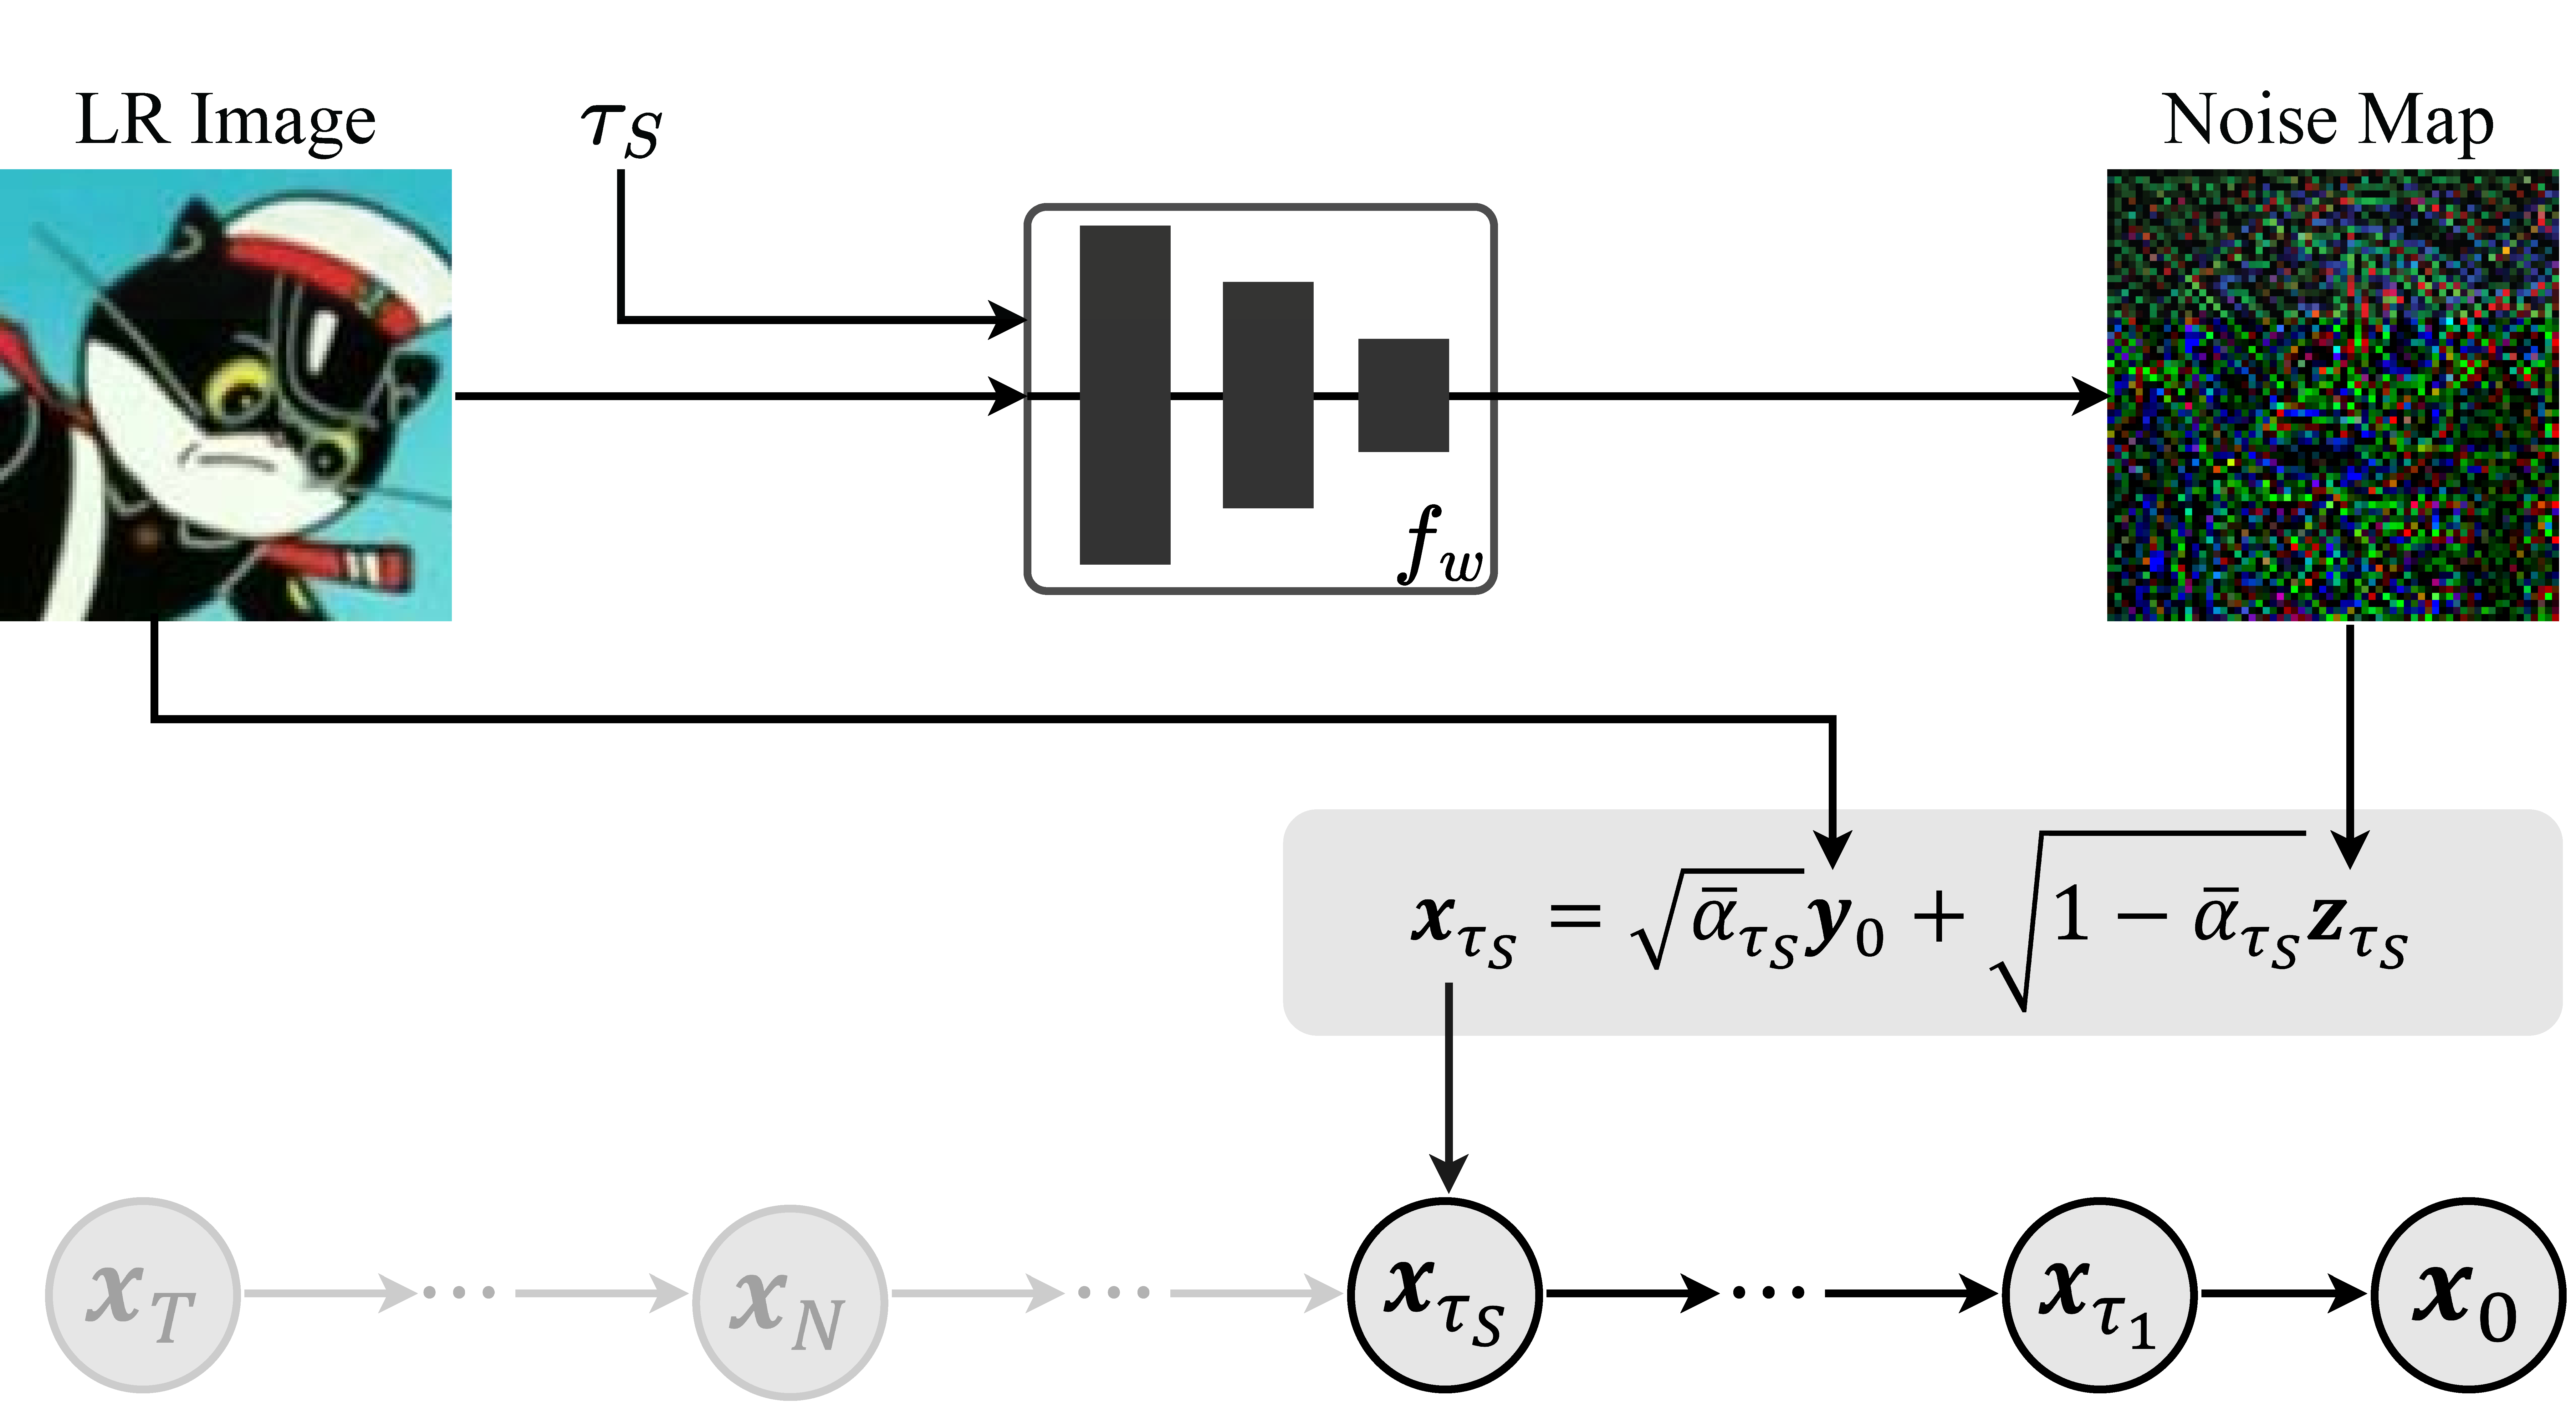
This study presents a new image super-resolution (SR) technique based on diffusion inversion, aiming at harnessing the rich image priors encapsulated in large pre-trained diffusion models to improve SR performance. We design a \textit{Partial noise Prediction} strategy to construct an intermediate state of the diffusion model, which serves as the starting sampling point. Central to our approach is a deep noise predictor to estimate the optimal noise maps for the forward diffusion process. Once trained, this noise predictor can be used to initialize the sampling process partially along the diffusion trajectory, generating the desirable high-resolution result. Compared to existing approaches, our method offers a flexible and efficient sampling mechanism that supports an arbitrary number of sampling steps, ranging from one to five. Even with a single sampling step, our method demonstrates superior or comparable performance to recent state-of-the-art approaches.
Update
- 2025.03.01: InvSR has been accepted by CVPR 2025.
- 2025.01.08: Update gradio demo for batch processing.
- 2024.12.14: Add
- 2024.12.13: Add
and
. - 2024.12.11: Create this repo.
Requirements
- Python 3.10, Pytorch 2.4.0, xformers 0.0.27.post2
- More detail (See environment.yaml)
- A suitable conda environment named
invsrcan be created and activated with:
conda create -n invsr python=3.10
conda activate invsr
pip install torch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 --index-url https://download.pytorch.org/whl/cu121
pip install -U xformers==0.0.27.post2 --index-url https://download.pytorch.org/whl/cu121
pip install -e ".[torch]"
pip install -r requirements.txt
Applications
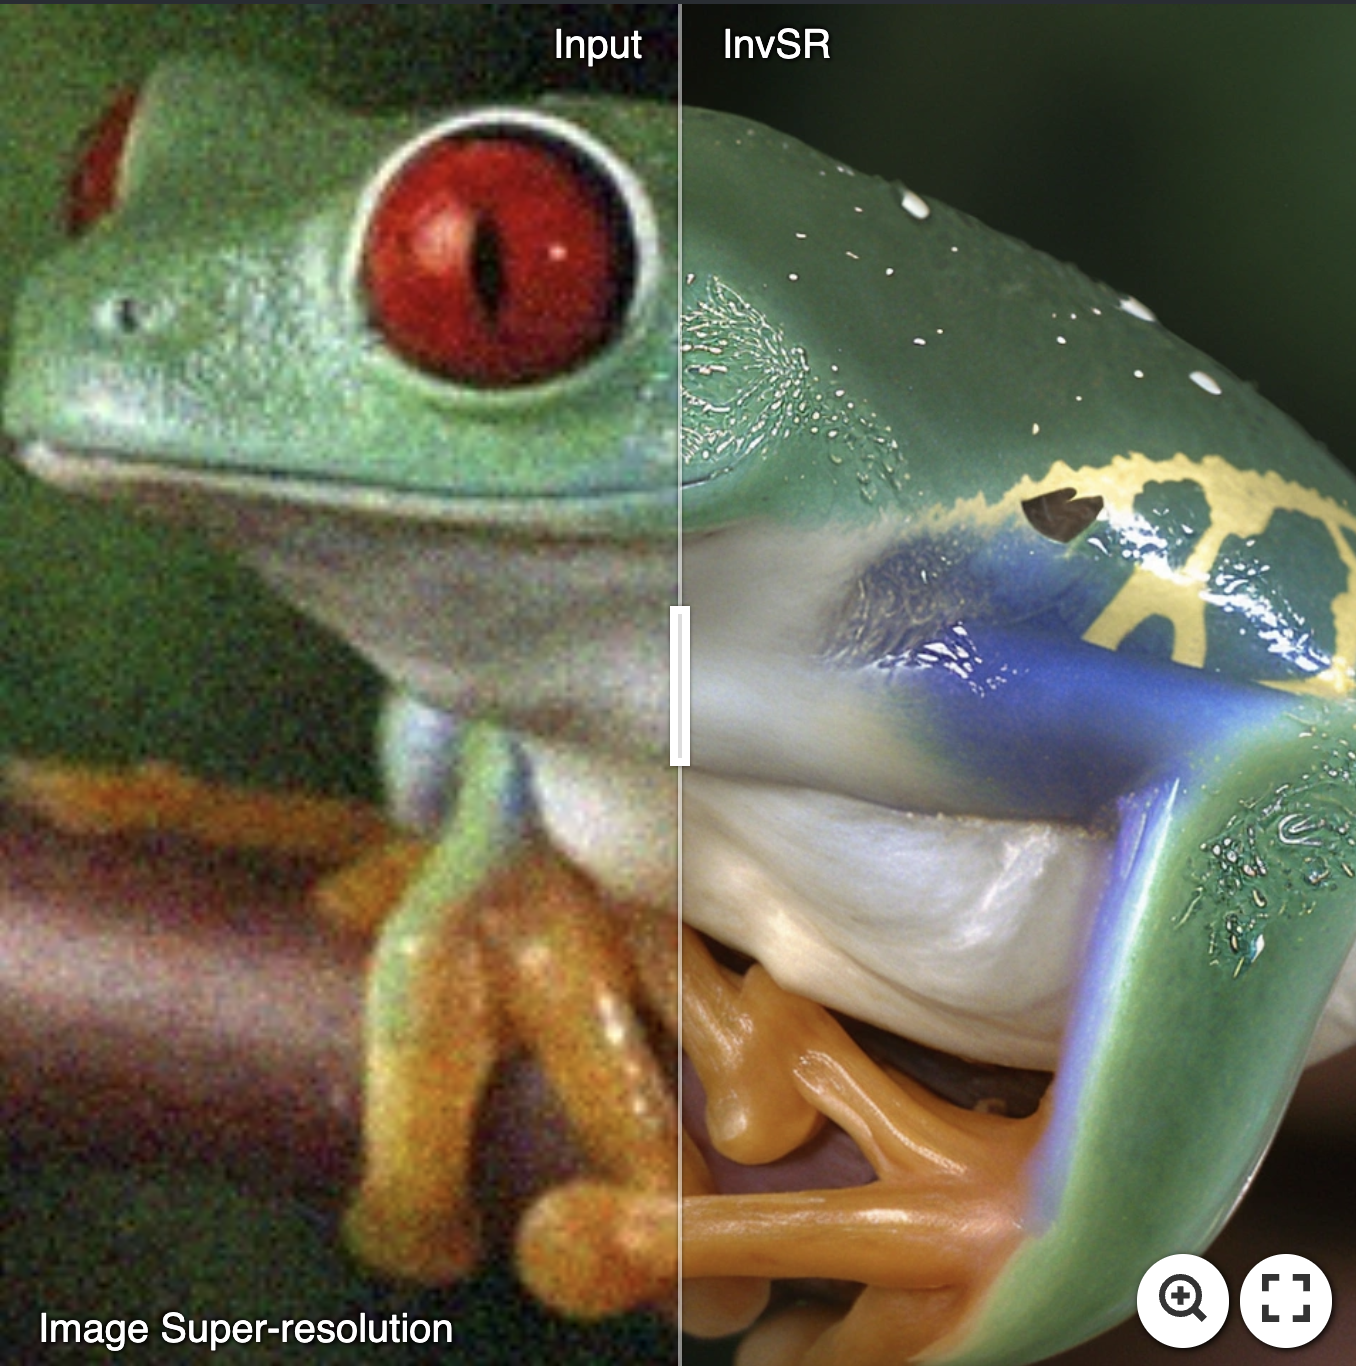
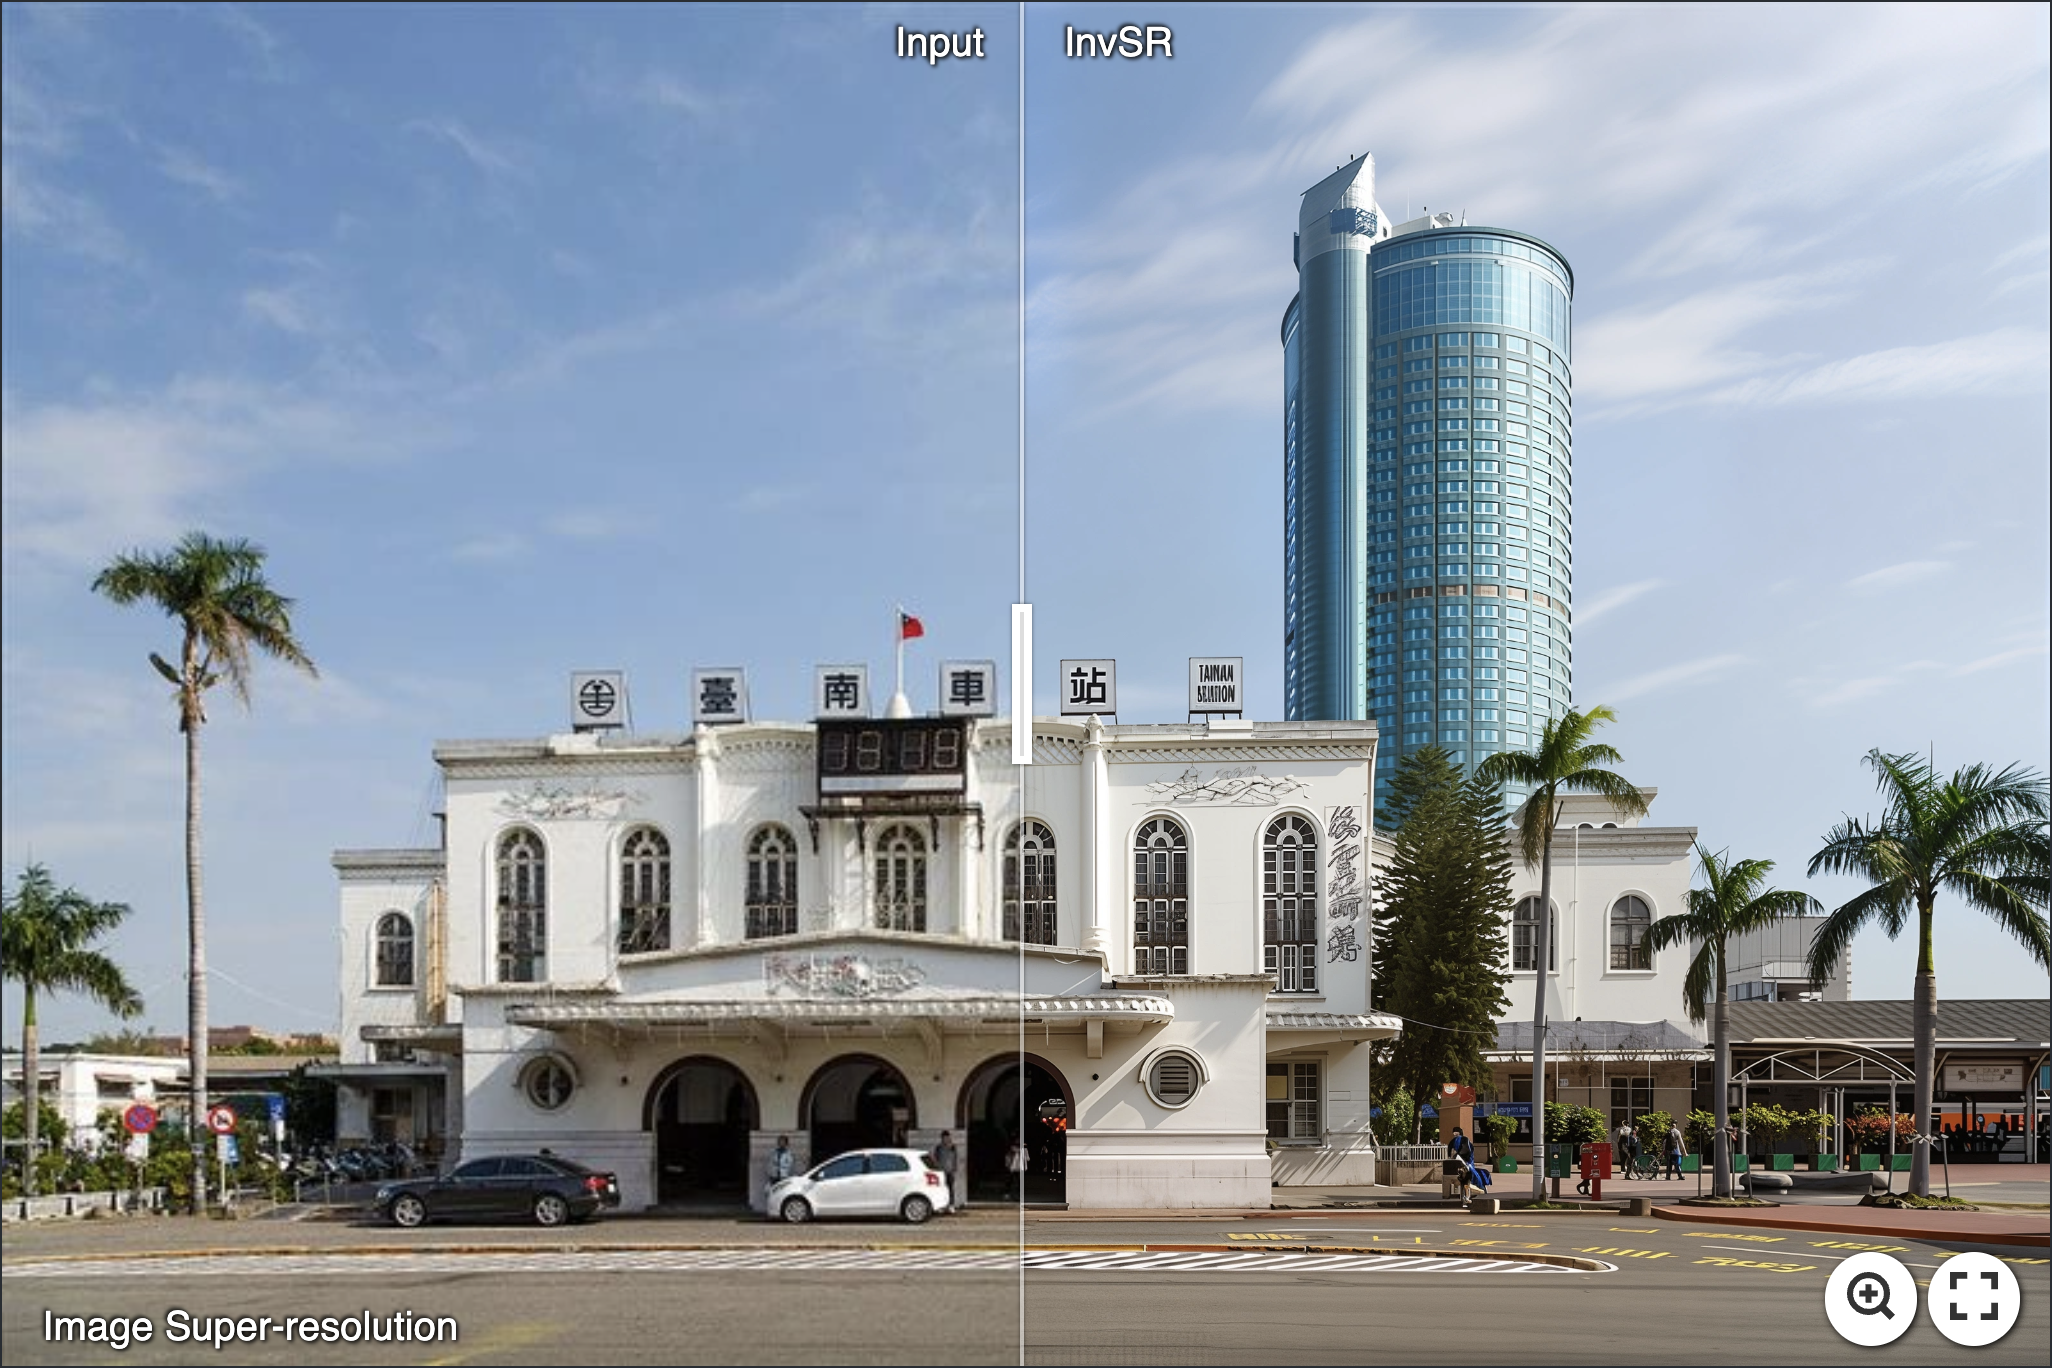
:point_right: Real-world Image Super-resolution
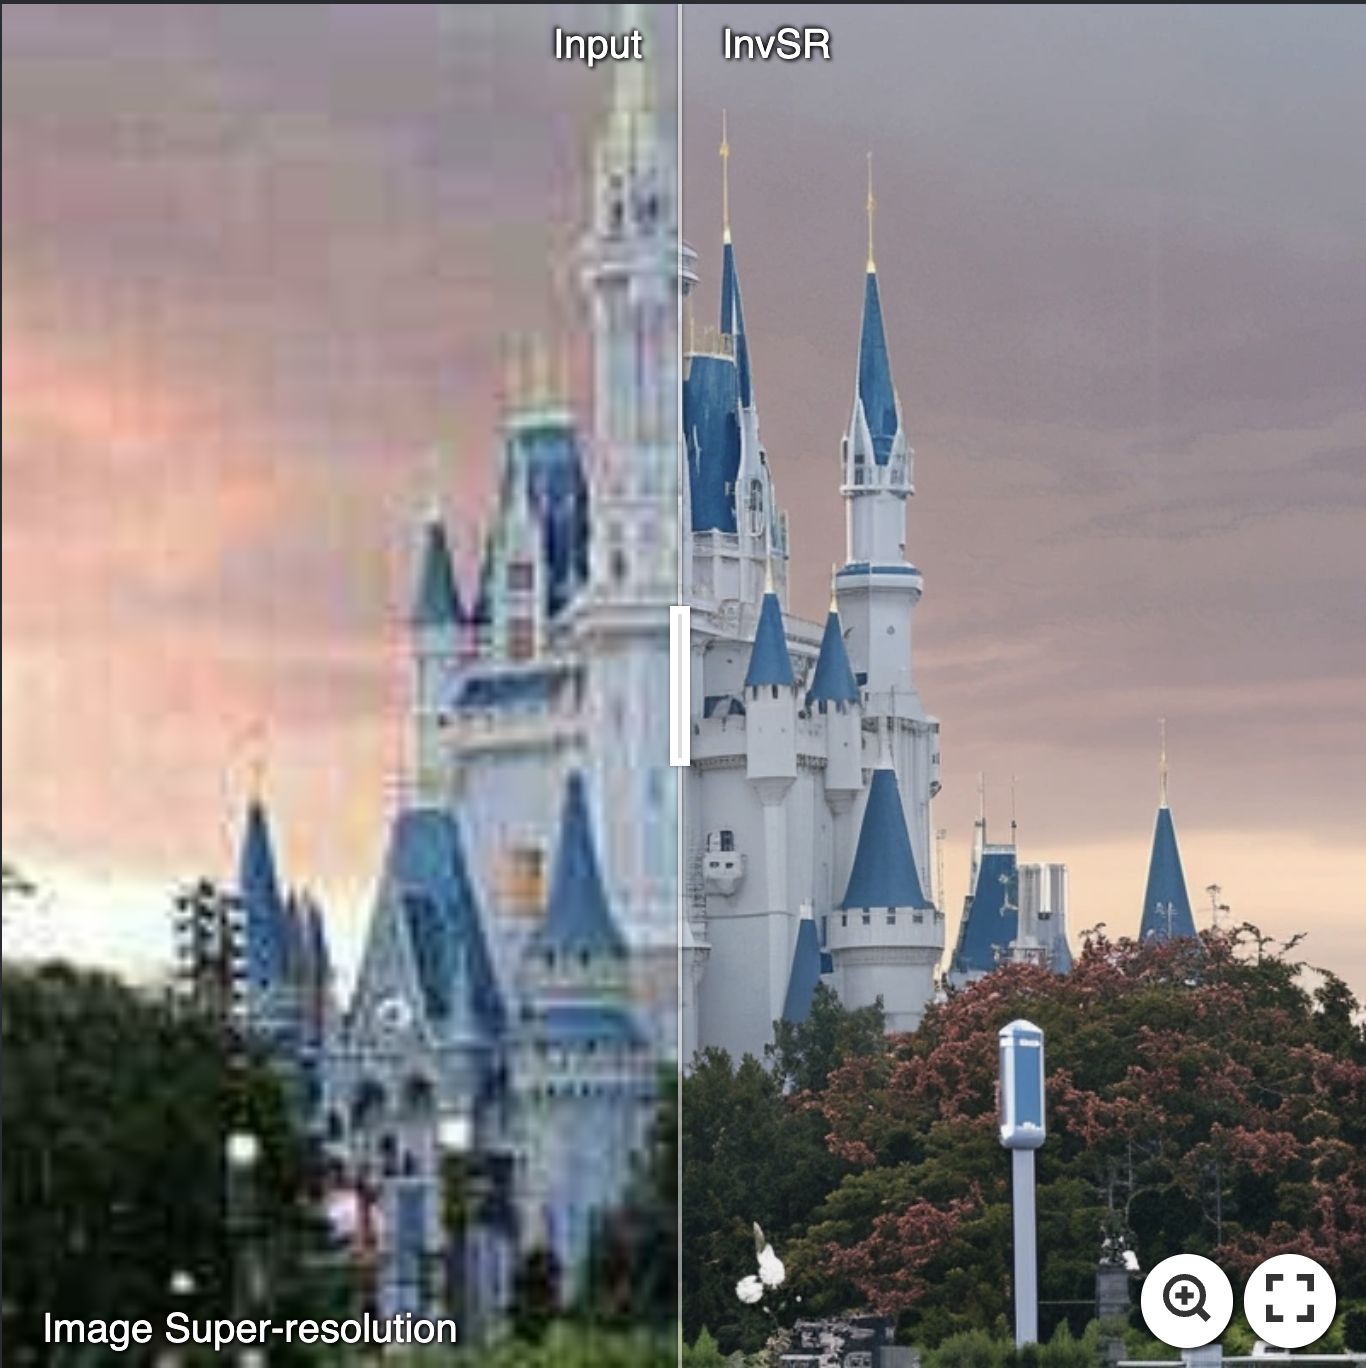
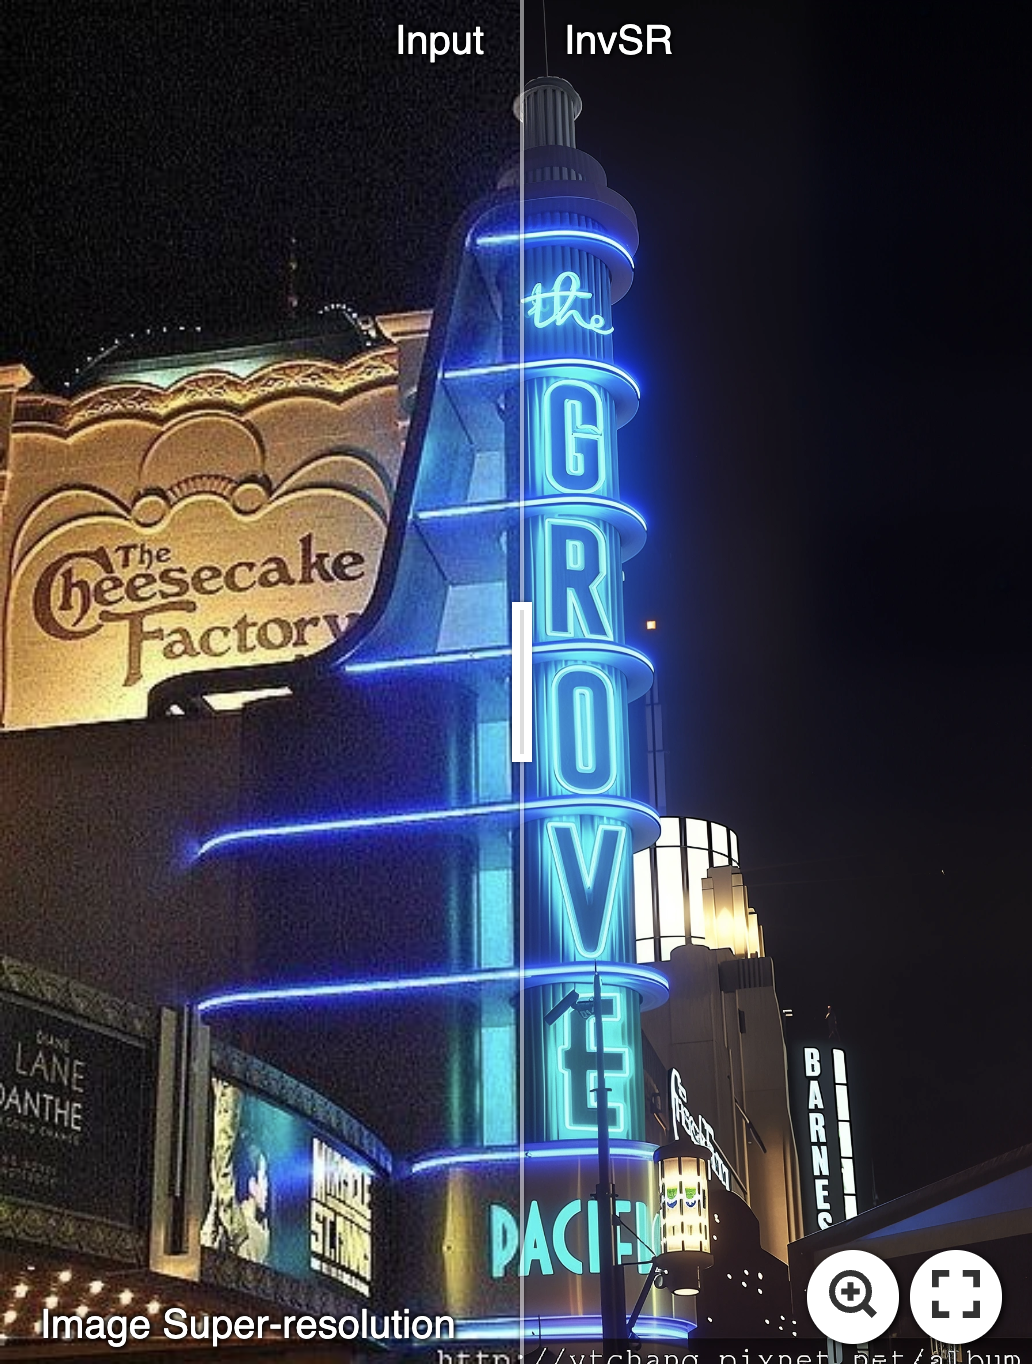
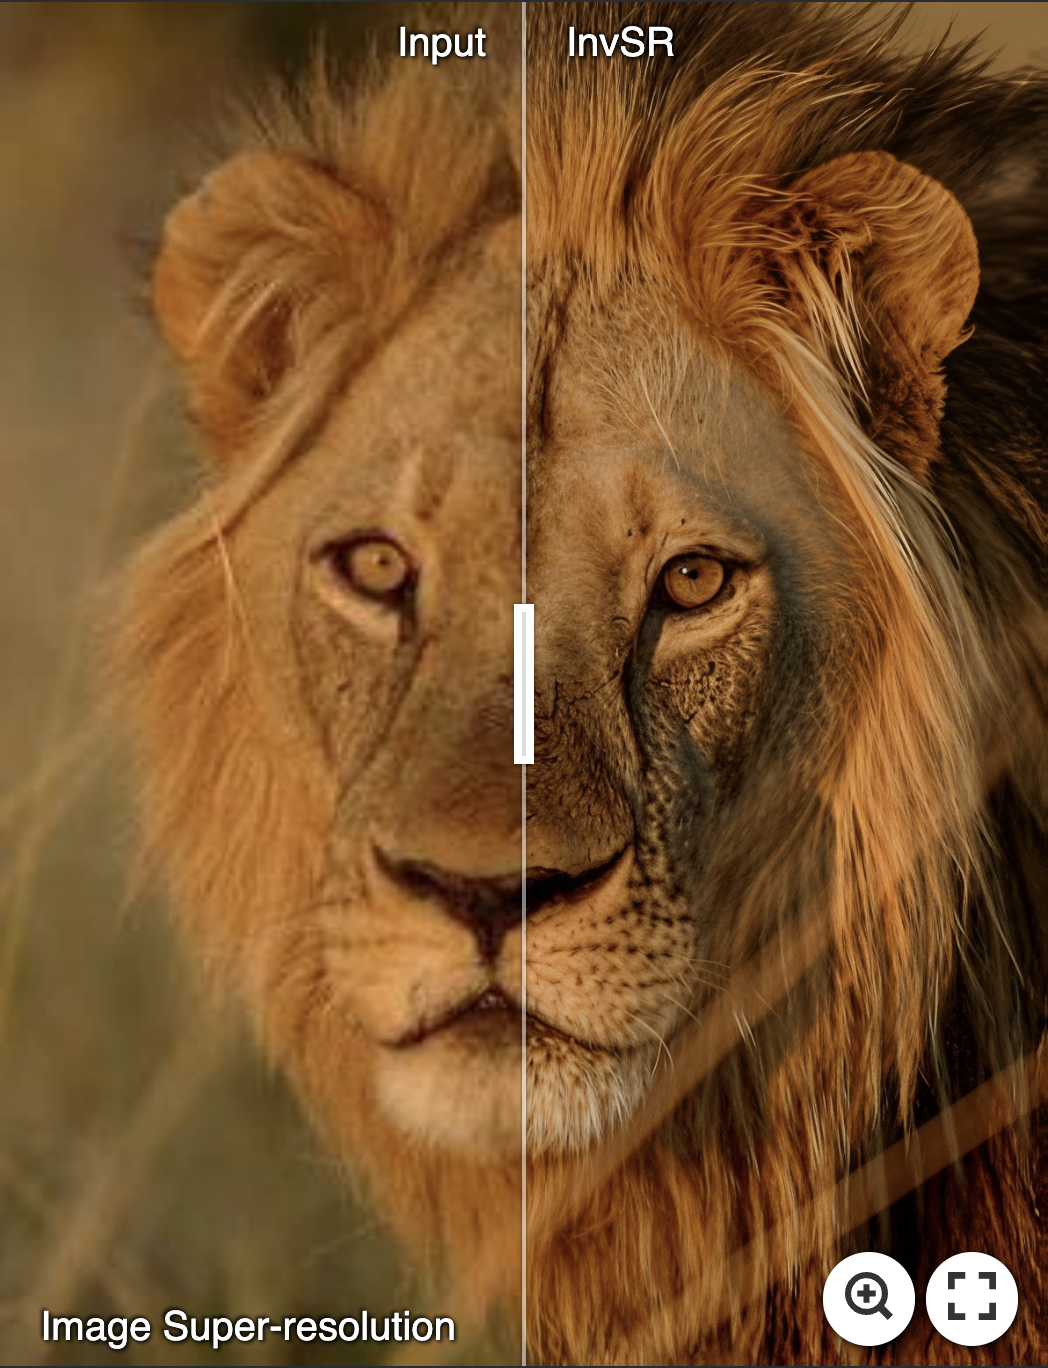
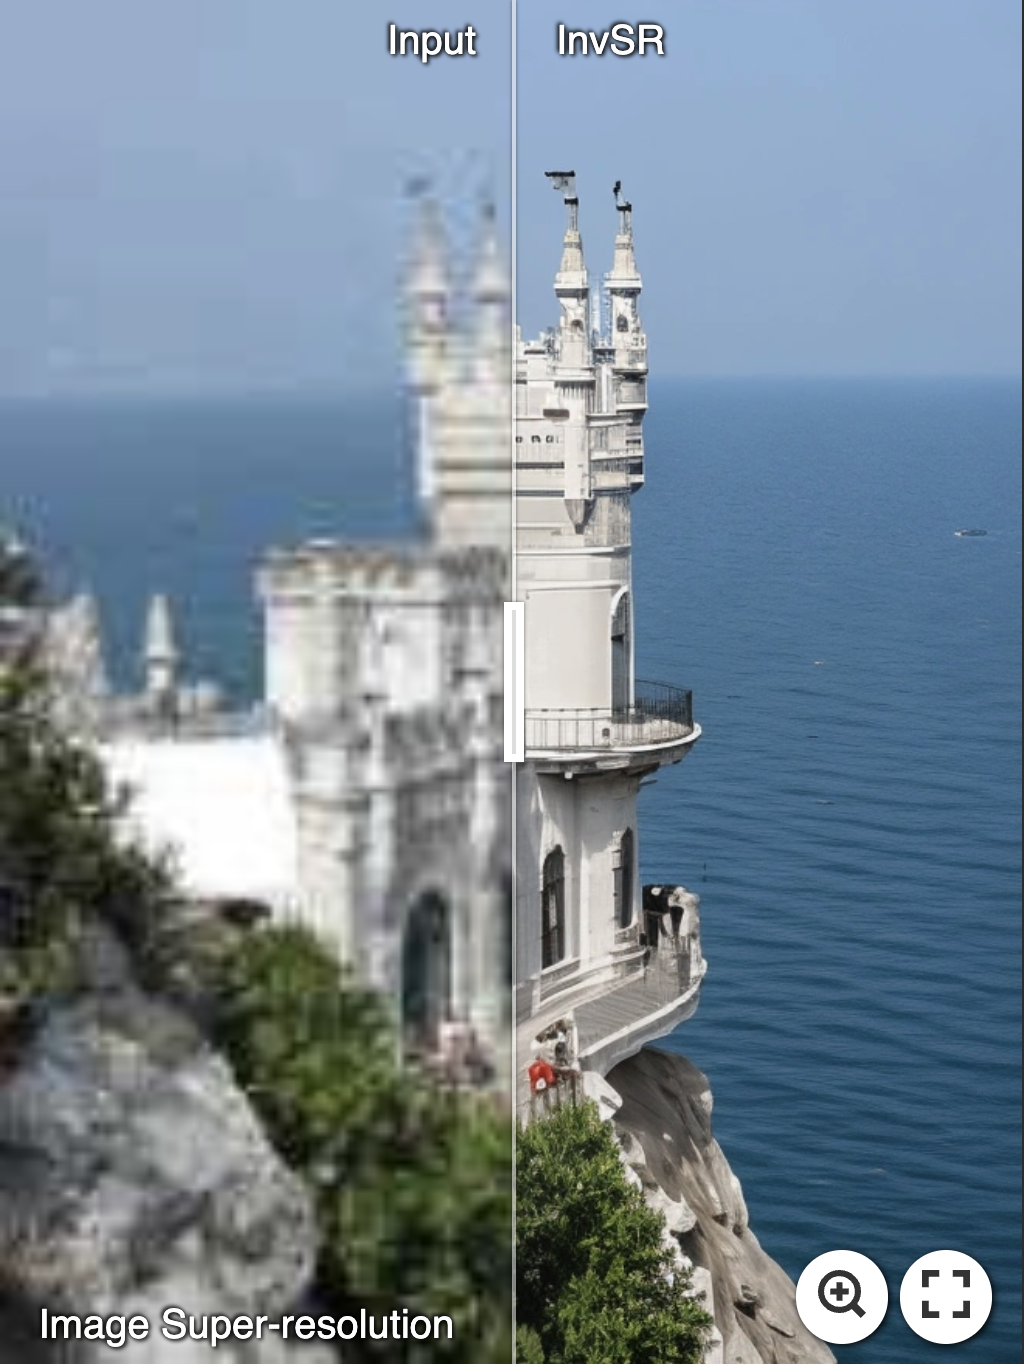
:point_right: AIGC Image Enhancement
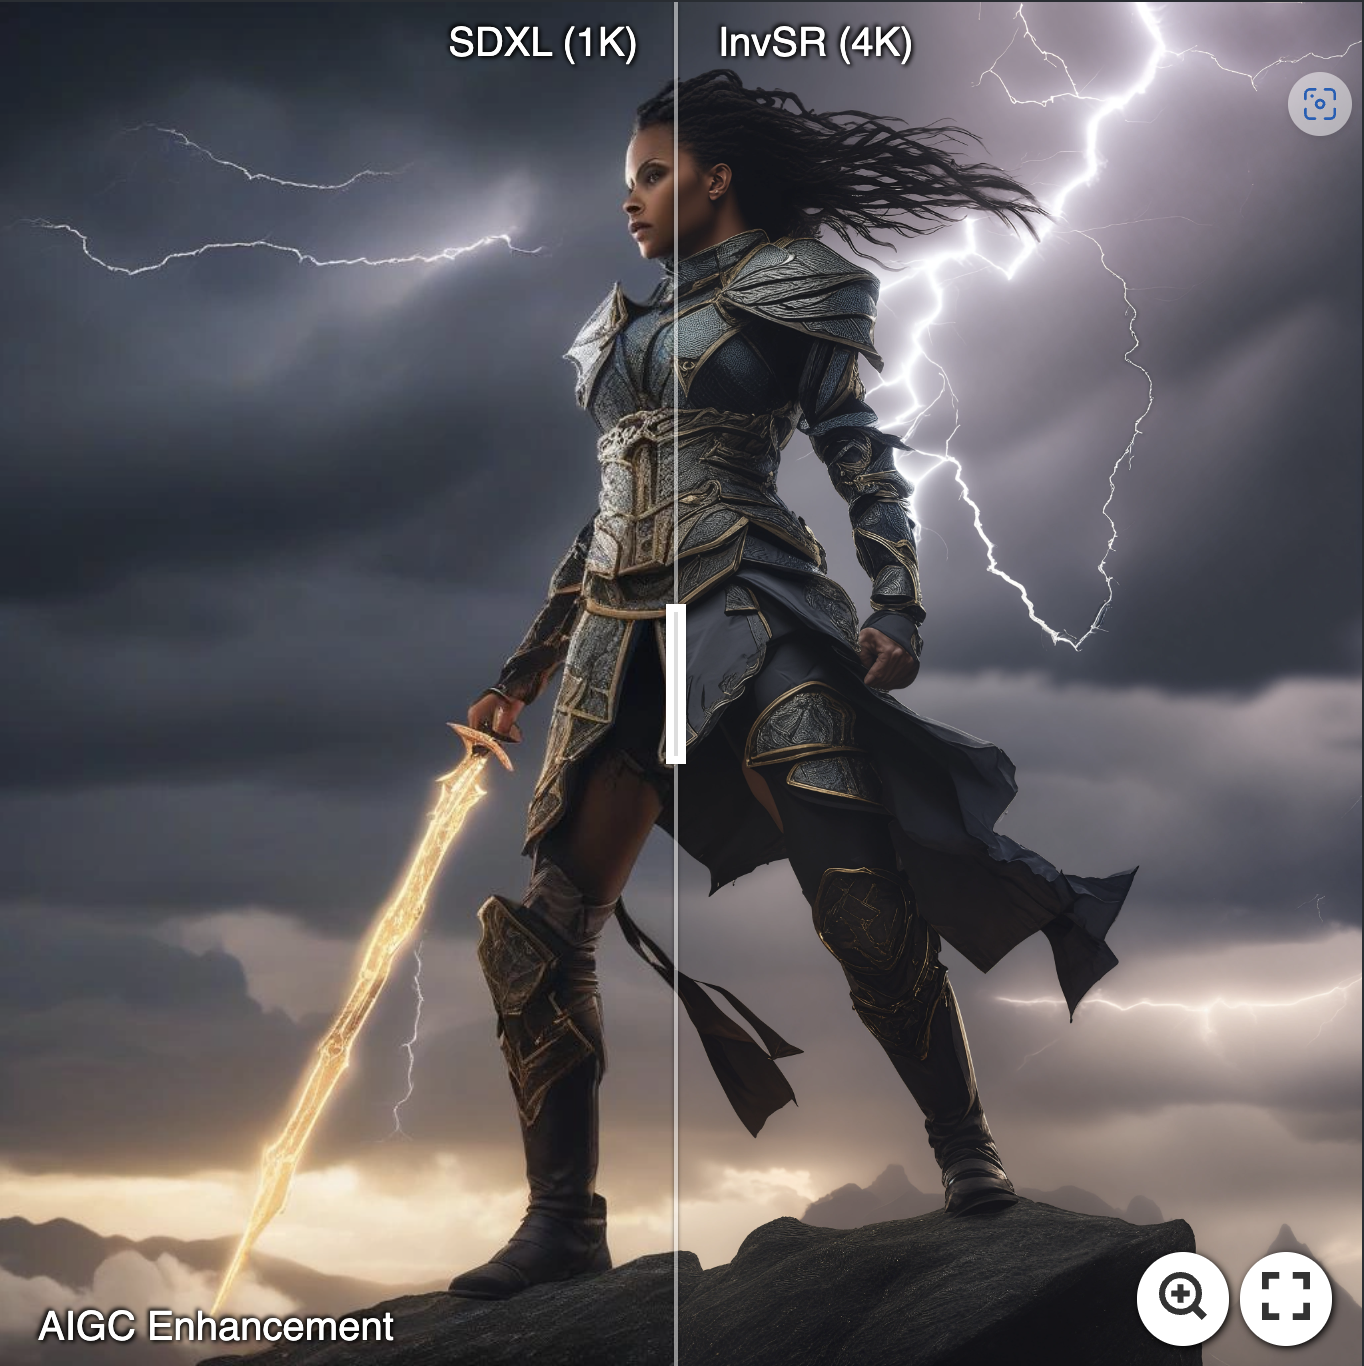
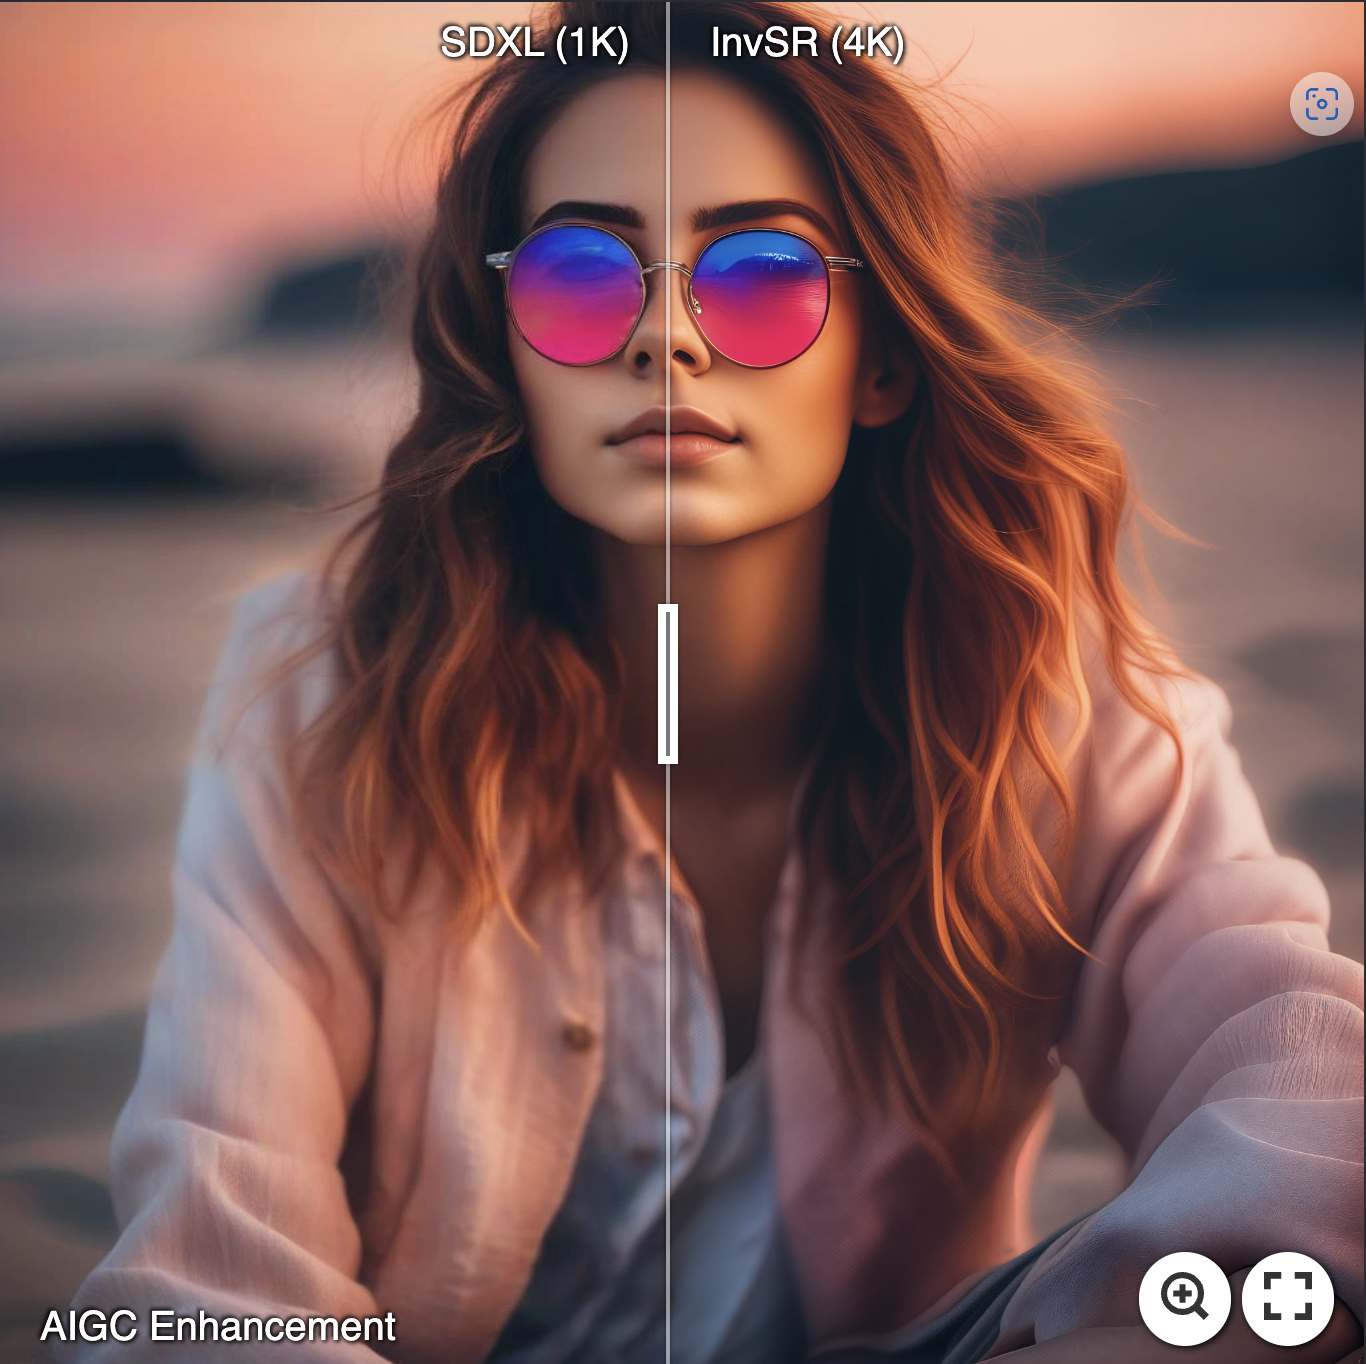
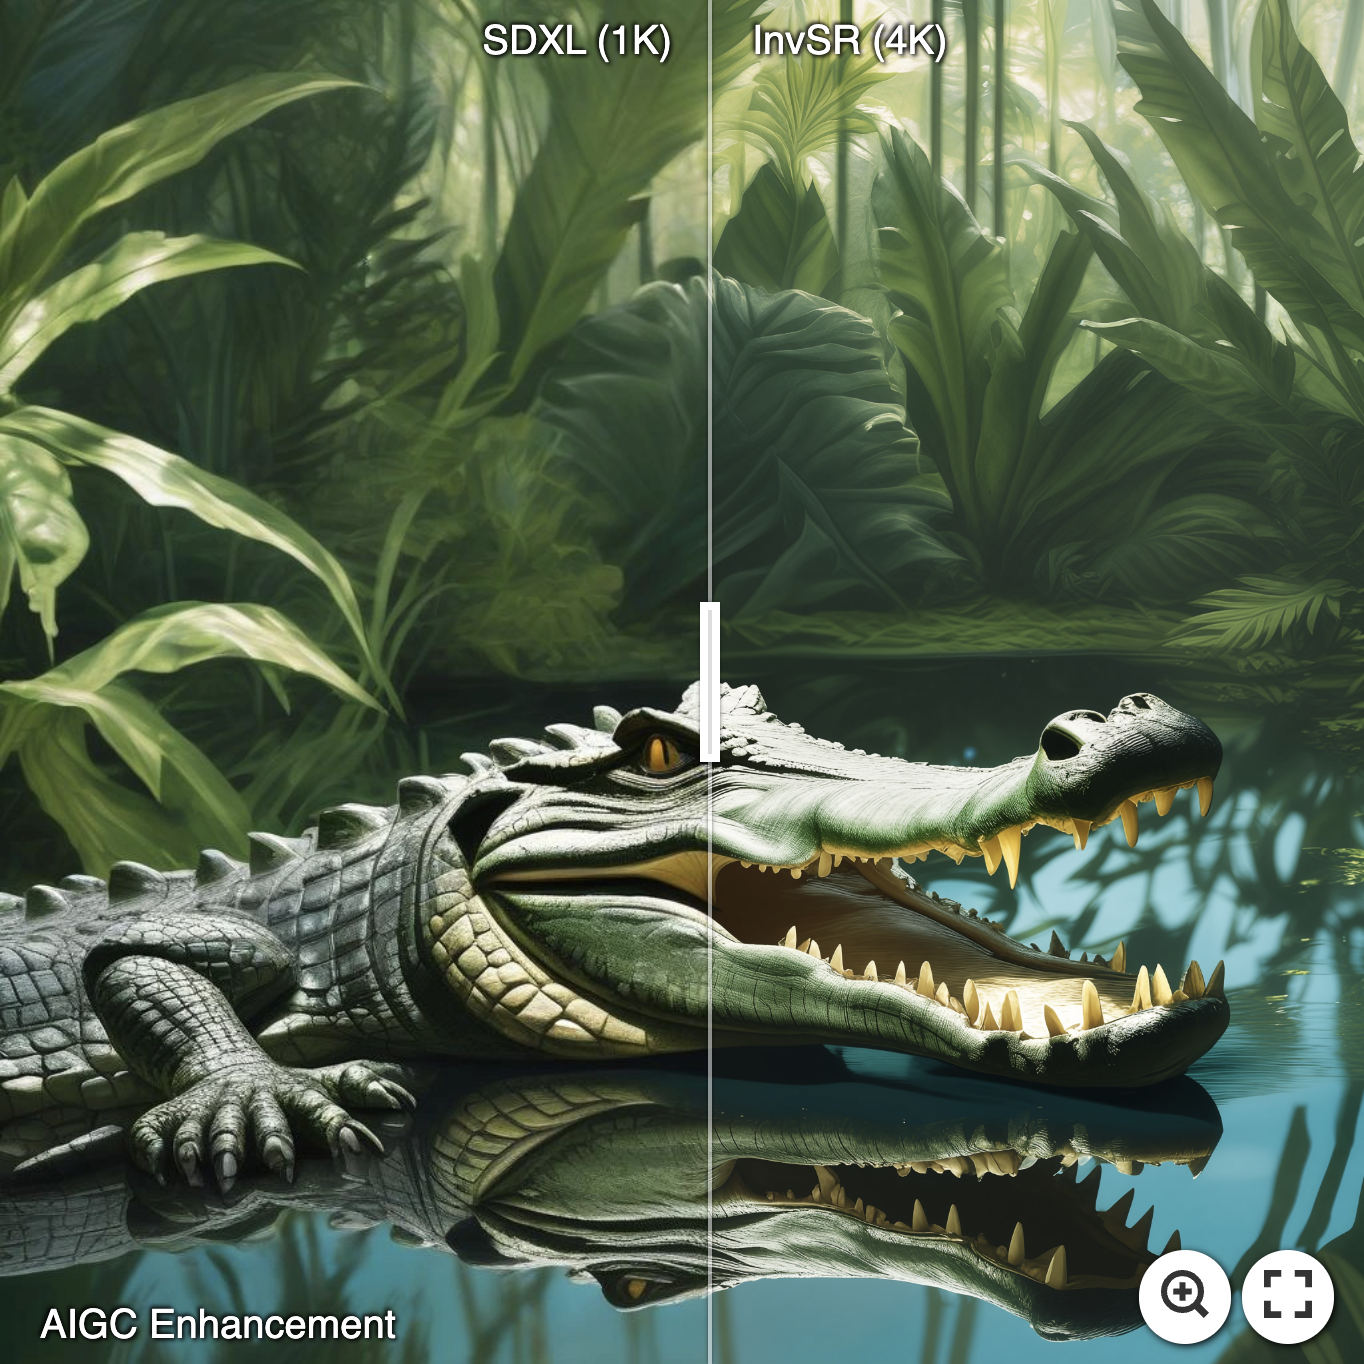
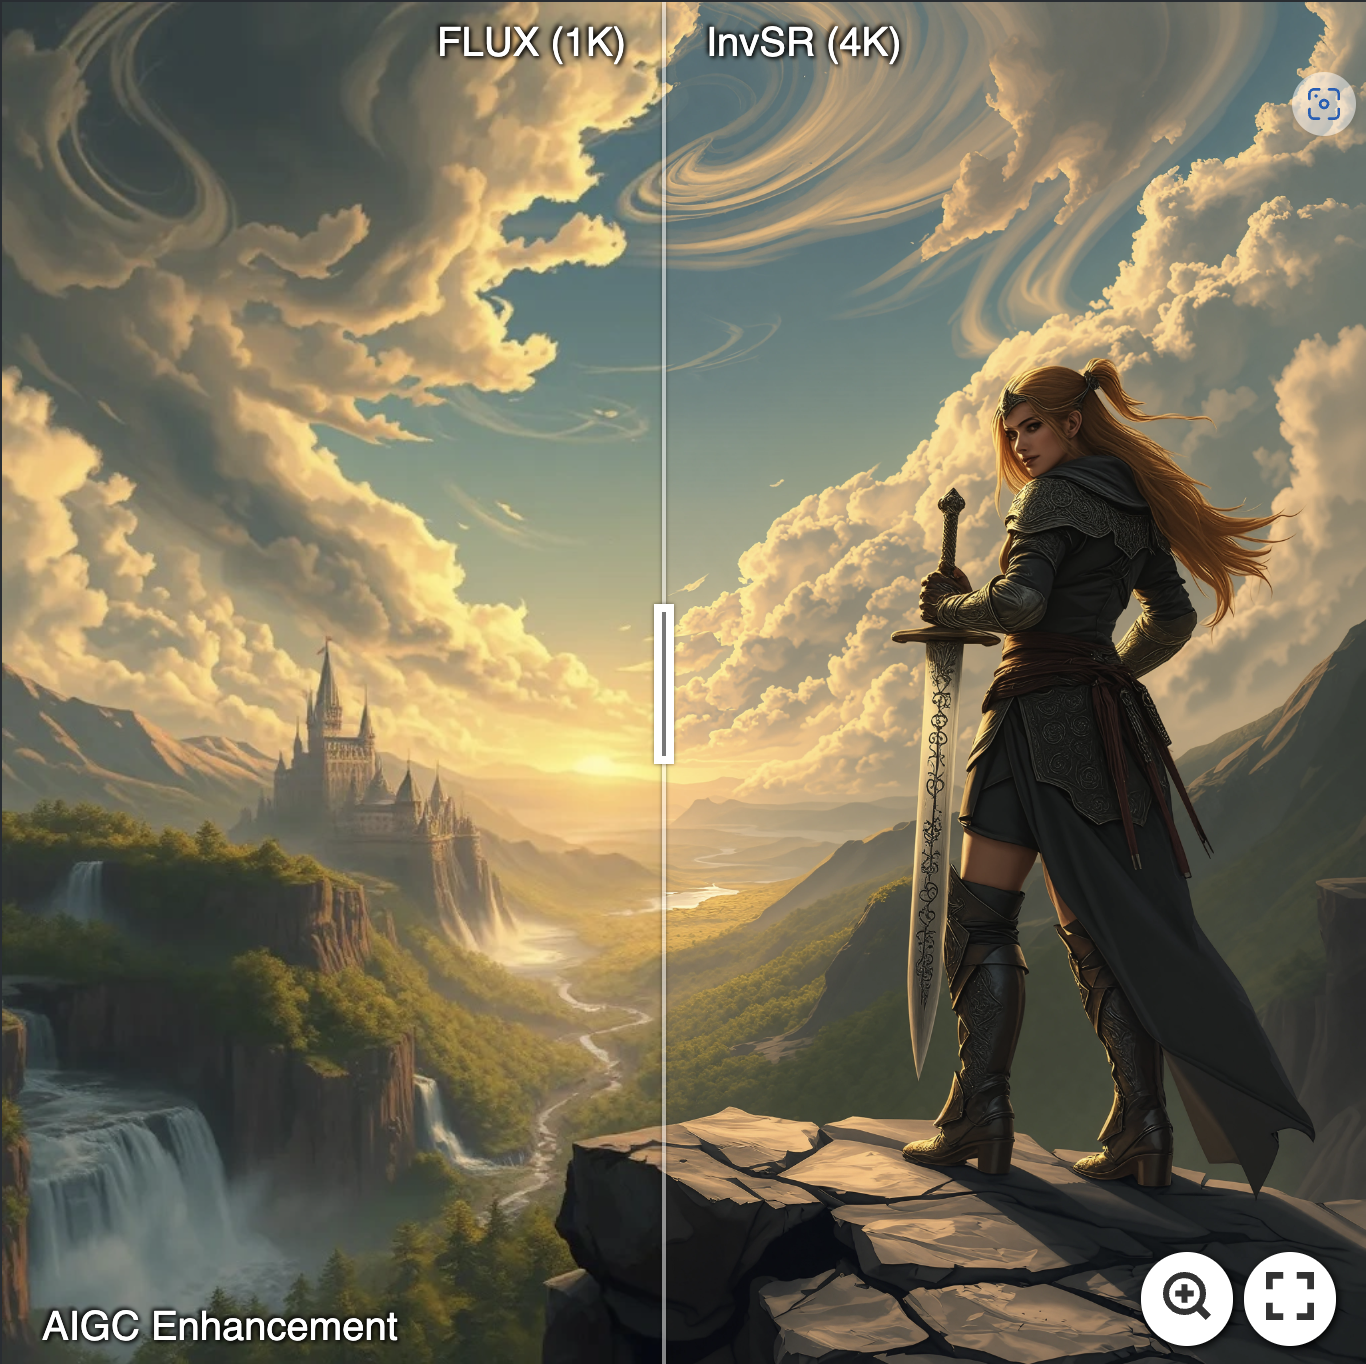
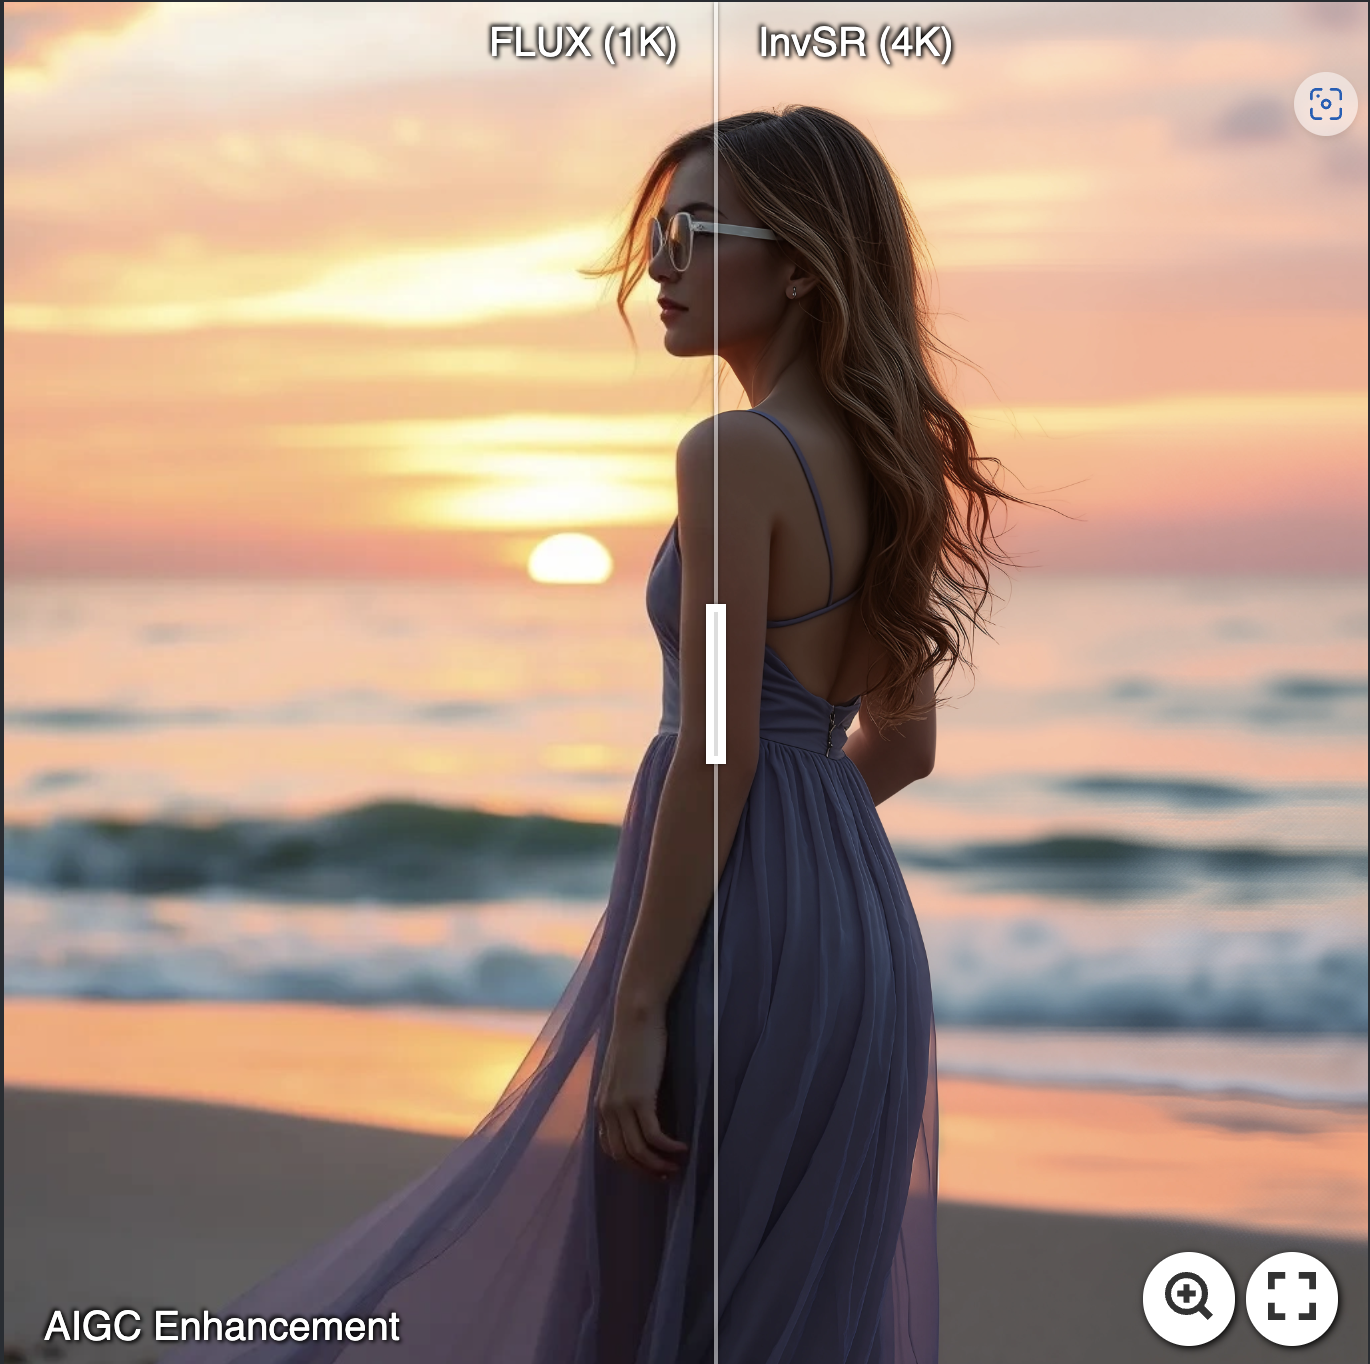
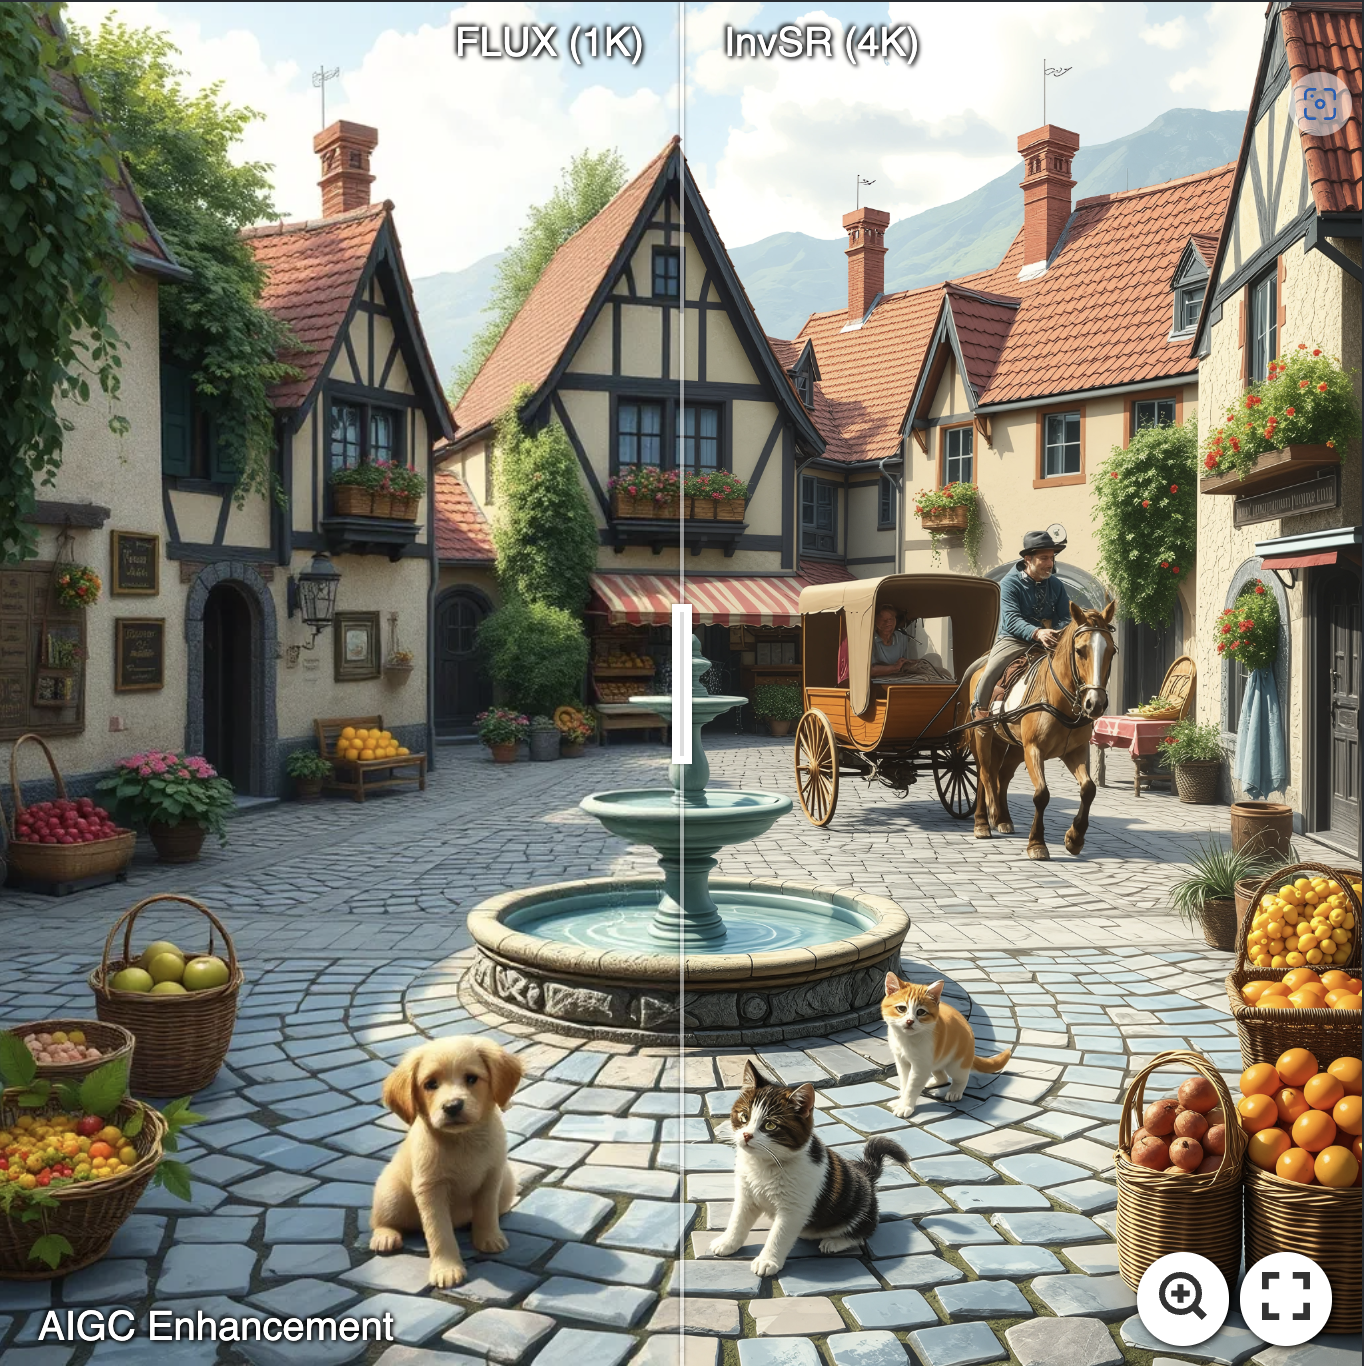
Inference
:rocket: Fast testing
python inference_invsr.py -i [image folder/image path] -o [result folder] --num_steps 1
- To deal with large images, e.g., 1k---->4k, we recommend adding the option
--chopping_size 256. - Other options:
- Specify the pre-downloaded SD Turbo Model:
--sd_path. - Specify the pre-downloaded noise predictor:
--started_ckpt_path. - The number of sampling steps:
--num_steps. - If your GPU memory is limited, please add the option
--chopping_bs 1.
- Specify the pre-downloaded SD Turbo Model:
:railway_car: Online Demo
You can try our method through an online demo:
python app.py
:whale: Now also available in Docker
docker compose up -d # Go to http://127.0.0.1:7860/
:airplane: Reproducing our paper results
Synthetic dataset of ImageNet-Test: Google Drive.
To reproduce the quantitative results on Imagenet-Test and RealSRV3, please add the color fixing options by
--color_fix wavelet.
Training
:turtle: Preparing stage
- Download the finetuned LPIPS model from this link and put it in the folder of "weights".
- Prepare the config file:
- SD-Turbo path: configs.sd_pipe.params.cache_dir.
- Training data path: data.train.params.data_source.
- Validation data path: data.val.params.dir_path (low-quality image) and data.val.params.extra_dir_path (high-quality image).
- Batchsize: configs.train.batch and configs.train.microbatch (total batchsize = microbatch * #GPUS * num_grad_accumulation)
:dolphin: Begin training
CUDA_VISIBLE_DEVICES=0,1,2,3 torchrun --standalone --nproc_per_node=4 --nnodes=1 main.py --save_dir [Logging Folder]
:whale: Resume from interruption
CUDA_VISIBLE_DEVICES=0,1,2,3 torchrun --standalone --nproc_per_node=4 --nnodes=1 main.py --save_dir [Logging Folder] --resume save_dir/ckpts/model_xx.pth
License
This project is licensed under NTU S-Lab License 1.0. Redistribution and use should follow this license.
Acknowledgement
This project is based on BasicSR and diffusers. Thanks for their awesome works.
Contact
If you have any questions, please feel free to contact me via [email protected].
Ähnliche Projekte entdecken
codecrafters-io/build-your-own-x
Meistere das Programmieren, indem du deine Lieblingstechnologien von Grund auf neu erschaffst.
561,775 Sternepublic-apis/public-apis
Eine gemeinschaftliche Liste kostenloser APIs
498,126 Sternemorluto/rea
Mit Agenten alles per Reverse Engineering untersuchen, vom Verhalten der Anwendung bis hin zu nativen Binärdateien.
451,963 Sterneopenclaw/openclaw
Die KI, die wirklich Dinge erledigt. Jedes Betriebssystem, jede Plattform. Auf die Hummer-Art. 🦞
394,340 Sterne