
omriav/blended-latent-diffusion
omriav/blended-latent-diffusion has 632 GitHub stars and 37 forks. GitHot measured +1 in 7 days and +1 in 15 days. Last checked 2026-11-13 17:23 UTC. Last push 2024-06-04.
Gemessener Sternzuwachs
- in 24h
- Aktualisierung verzögert
- in 7 days
- +1
- in 15 days
- +1
- in 1 month
- Verlauf wird gesammelt
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
Über uns
Official implementation for "Blended Latent Diffusion" [SIGGRAPH 2023]
Maschinelles LernenREADME.md
OriginalBlended Latent Diffusion [SIGGRAPH 2023]


Omri Avrahami, Ohad Fried, Dani Lischinski
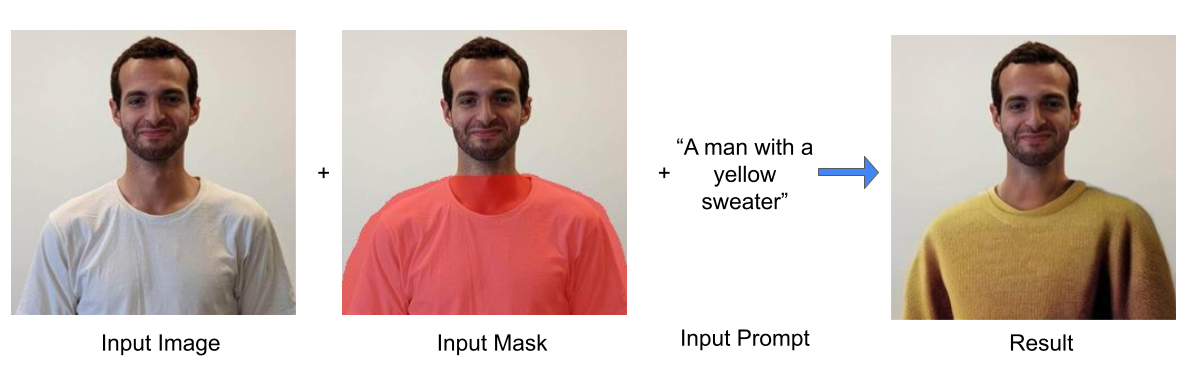
Abstract: The tremendous progress in neural image generation, coupled with the emergence of seemingly omnipotent vision-language models has finally enabled text-based interfaces for creating and editing images. Handling generic images requires a diverse underlying generative model, hence the latest works utilize diffusion models, which were shown to surpass GANs in terms of diversity. One major drawback of diffusion models, however, is their relatively slow inference time. In this paper, we present an accelerated solution to the task of local text-driven editing of generic images, where the desired edits are confined to a user-provided mask. Our solution leverages a recent text-to-image Latent Diffusion Model (LDM), which speeds up diffusion by operating in a lower-dimensional latent space. We first convert the LDM into a local image editor by incorporating Blended Diffusion into it. Next we propose an optimization-based solution for the inherent inability of this LDM to accurately reconstruct images. Finally, we address the scenario of performing local edits using thin masks. We evaluate our method against the available baselines both qualitatively and quantitatively and demonstrate that in addition to being faster, our method achieves better precision than the baselines while mitigating some of their artifacts


Applications
Background Editing

Text Generation

Multiple Predictions

Alter an Existing Object

Add a New Object

Scribble Editing

Installation
Install the conda virtual environment:
$ conda env create -f environment.yaml
$ conda activate ldm
Usage
New :fire: - Stable Diffusion Implementation
You can use the newer Stable Diffusion implementation based on Diffusers library. For that, you need to install PyTorch 2.1 and Diffusers via the following commands:
$ conda install pytorch==2.1.0 torchvision==0.16.0  pytorch-cuda=11.8 -c pytorch -c nvidia
$ pip install -U diffusers==0.19.3
- For using Stable Diffusion XL (requires a stronger GPU), use the following script:
$ python scripts/text_editing_SDXL.py --prompt "a stone" --init_image "inputs/img.png" --mask "inputs/mask.png"
You can use smaller --batch_size in order to save GPU memory.
- For using Stable Diffusion v2.1, use the following script:
$ python scripts/text_editing_SD2.py --prompt "a stone" --init_image "inputs/img.png" --mask "inputs/mask.png"
Old - Latent Diffusion Model Implementation
For using the old implementation, based on the Latent Diffusion Model (LDM), you need first to download the pre-trained weights (5.7GB):
$ mkdir -p models/ldm/text2img-large/
$ wget -O models/ldm/text2img-large/model.ckpt https://ommer-lab.com/files/latent-diffusion/nitro/txt2img-f8-large/model.ckpt
If the above link is broken, you can use this mirror link.
Then, editing the image may require two steps:
Step 1 - Generate initial predictions
$ python scripts/text_editing_LDM.py --prompt "a pink yarn ball" --init_image "inputs/img.png" --mask "inputs/mask.png"
The predictions will be saved in outputs/edit_results/samples.
You can use a larger batch size by specifying --n_samples to the maximum number that saturates your GPU.
Step 2 (optional) - Reconstruct the original background
If you want to reconstruct the original image background, you can run the following:
$ python scripts/reconstruct.py --init_image "inputs/img.png" --mask "inputs/mask.png" --selected_indices 0 1
You can choose the specific image indices that you want to reconstruct. The results will be saved in outputs/edit_results/samples/reconstructed_optimization.
Citation
If you find this project useful for your research, please cite the following:
@article{avrahami2023blendedlatent,
        author = {Avrahami, Omri and Fried, Ohad and Lischinski, Dani},
        title = {Blended Latent Diffusion},
        year = {2023},
        issue_date = {August 2023},
        publisher = {Association for Computing Machinery},
        address = {New York, NY, USA},
        volume = {42},
        number = {4},
        issn = {0730-0301},
        url = {https://doi.org/10.1145/3592450},
        doi = {10.1145/3592450},
        journal = {ACM Trans. Graph.},
        month = {jul},
        articleno = {149},
        numpages = {11},
        keywords = {zero-shot text-driven local image editing}
}

@InProceedings{Avrahami_2022_CVPR,
        author    = {Avrahami, Omri and Lischinski, Dani and Fried, Ohad},
        title     = {Blended Diffusion for Text-Driven Editing of Natural Images},
        booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
        month     = {June},
        year      = {2022},
        pages     = {18208-18218}
}
Acknowledgements
This code is based on Latent Diffusion Models.
Ähnliche Projekte entdecken
tensorflow/tensorflow
Ein Open-Source-Framework für maschinelles Lernen für alle
201,583 Sternehuggingface/transformers
🤗 Transformers: das Framework zur Modelldefinition für State-of-the-Art-Modelle des maschinellen Lernens in Text, Vision, Audio und multimodal, für Inferenz und Training.
168,948 SterneAUTOMATIC1111/stable-diffusion-webui
Web-UI für Stable Diffusion
165,301 SterneComfy-Org/ComfyUI
Die leistungsstärkste und modularste GUI, API und das Backend für Diffusionsmodelle mit einer Oberfläche aus Graphen und Knoten. Die schnellste lokale Inferenz-Engine der Welt.
146,661 Sterne