
lnx-search/lnx has 1,460 GitHub stars and 52 forks. GitHot measured +2 in 7 days. Last checked 2026-11-10 04:13 UTC. Last push 2025-10-14.
So werden diese Zahlen gemessen
A flexible, performant and reliable search database without the AI bullshit.
What you can do
- 🤓 Complex Query Parser.
- ❤️ Typo tolerant fuzzy queries.
- ⚡️ Typo tolerant fast-fuzzy queries. (pre-computed spell correction)
- 🔥 More-Like-This queries.
Gemessener Sternzuwachs
- in 24h
- Aktualisierung verzögert
- in 7 days
- +2
- in 15 days
- Aktualisierung verzögert
- in 1 month
- Aktualisierung verzögert
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
README.md
OriginalWARNING! This is the active dev branch, checkout the latest stable release: https://github.com/lnx-search/lnx/tree/refs/tags/0.9.0


✨ Feature Rich | ⚡ Insanely Fast
An ultra-fast, adaptable deployment of the tantivy search engine via REST.
🌟 Standing On The Shoulders of Giants
lnx is built to not re-invent the wheel, it stands on top of the tokio-rs work-stealing runtime, hyper web framework combined with the raw compute power of the tantivy search engine.
Together this allows lnx to offer millisecond indexing on tens of thousands of document inserts at once (No more waiting around for things to get indexed!), Per index transactions and the ability to process searches like it's just another lookup on the hashtable 😲
✨ Features
lnx although very new offers a wide range of features thanks to the ecosystem it stands on.
- 🤓 Complex Query Parser.
- ❤️ Typo tolerant fuzzy queries.
- ⚡️ Typo tolerant fast-fuzzy queries. (pre-computed spell correction)
- 🔥 More-Like-This queries.
- Order by fields.
- Fast indexing.
- Fast Searching.
- Several Options for fine grain performance tuning.
- Multiple storage backends available for testing and developing.
- Permissions based authorization access tokens.
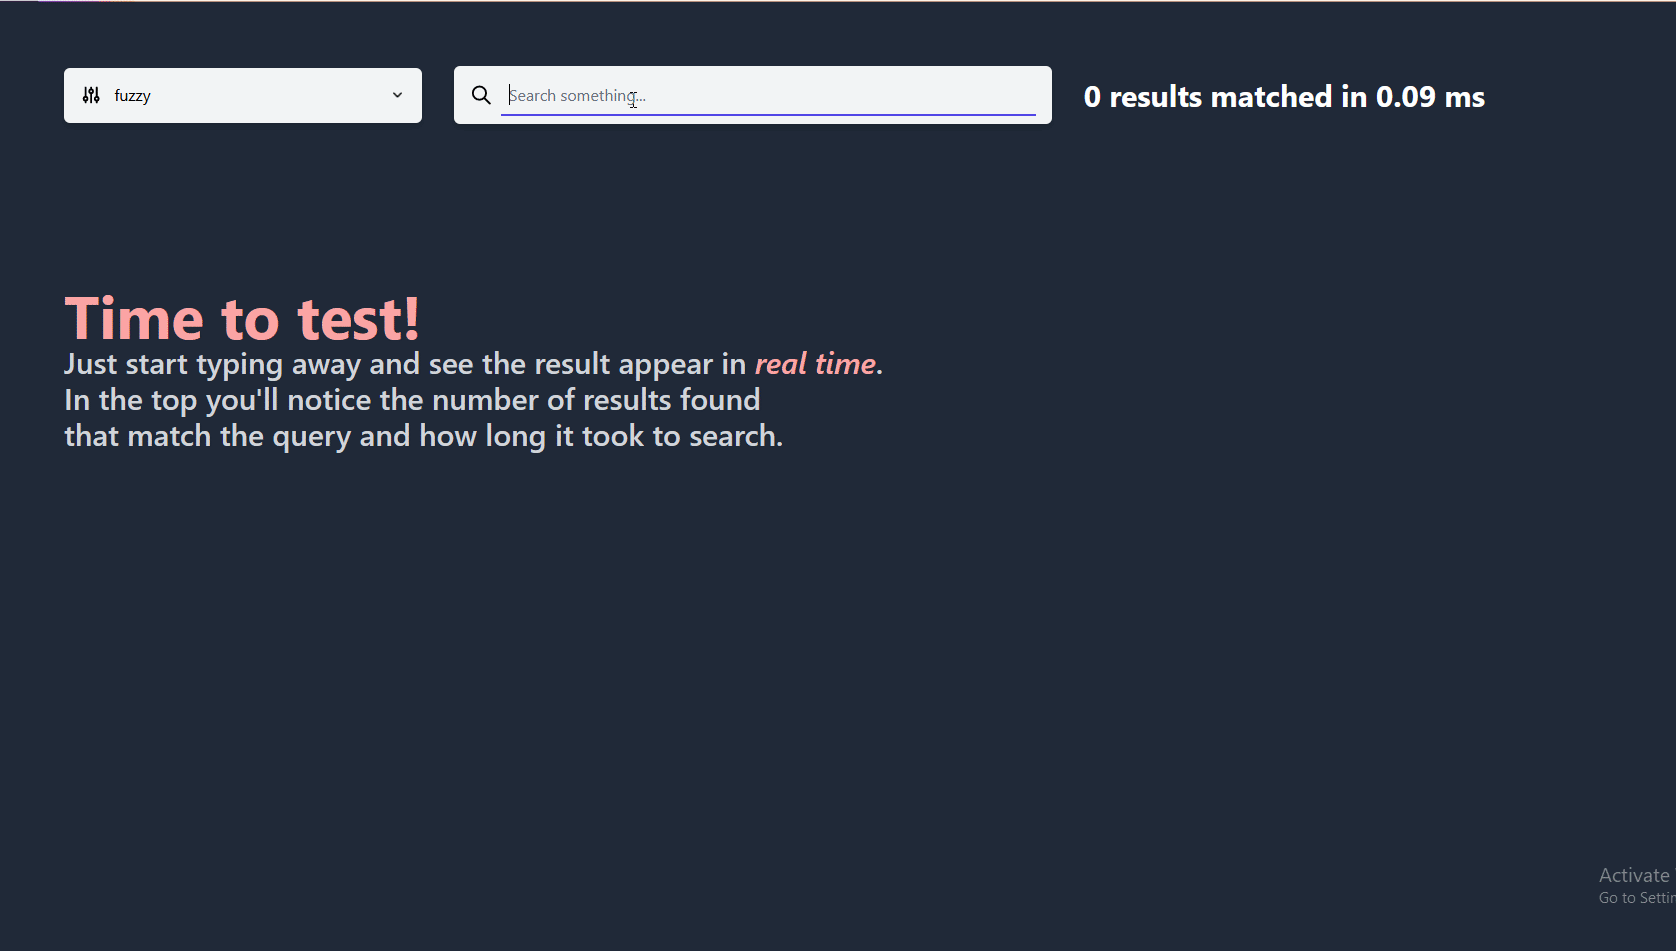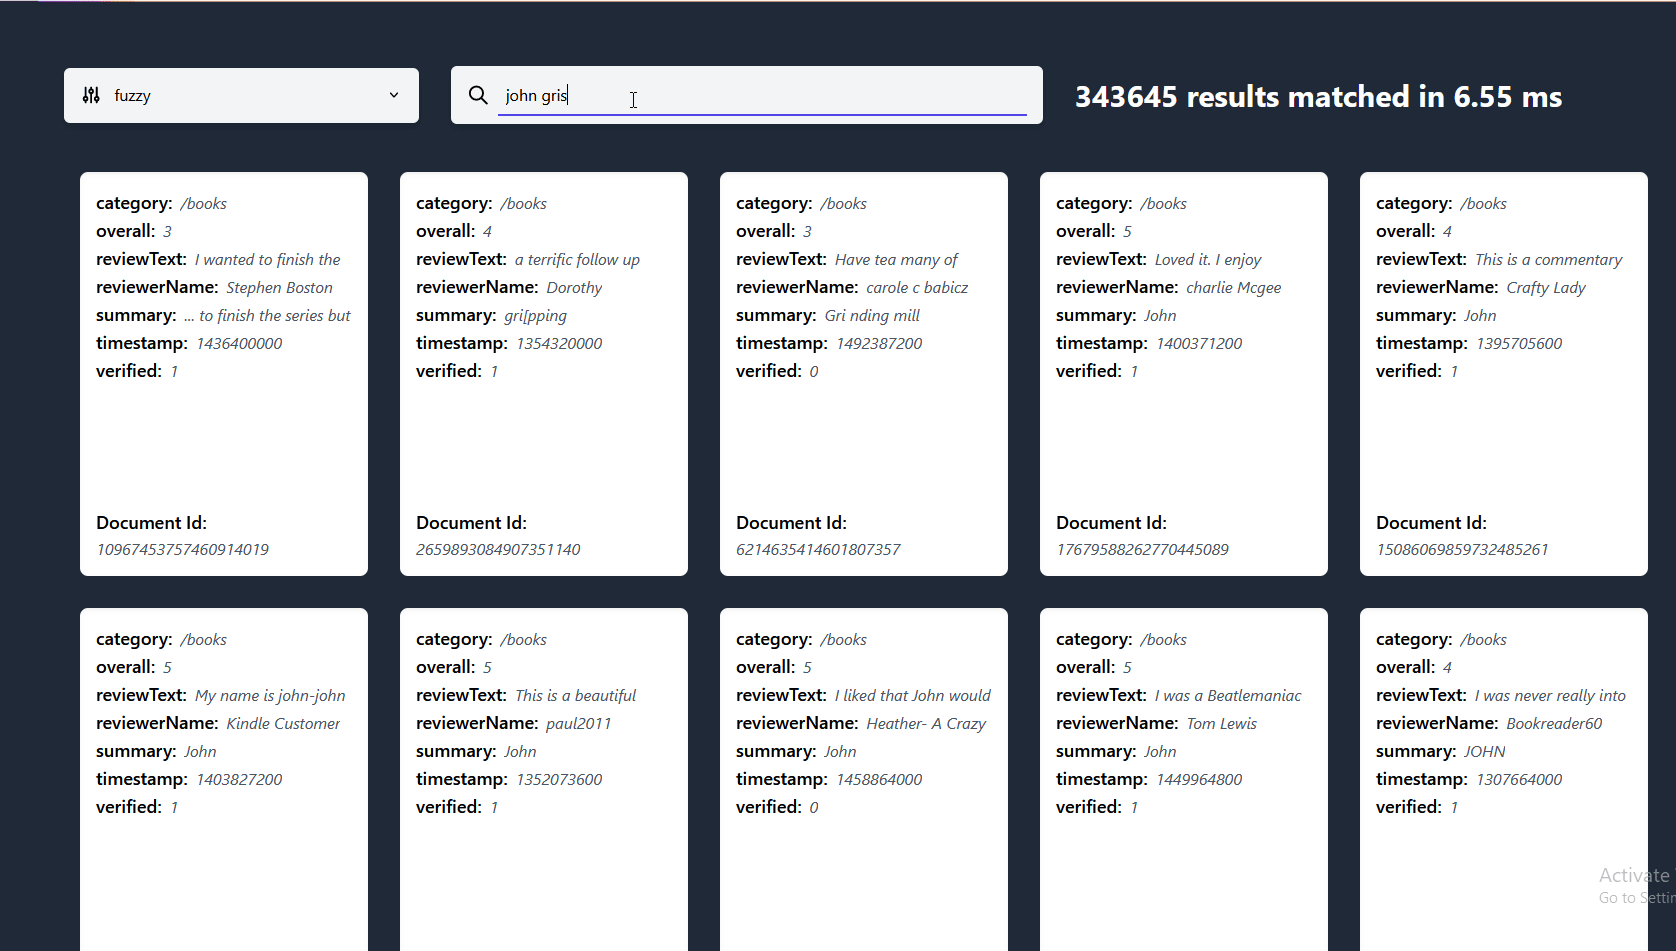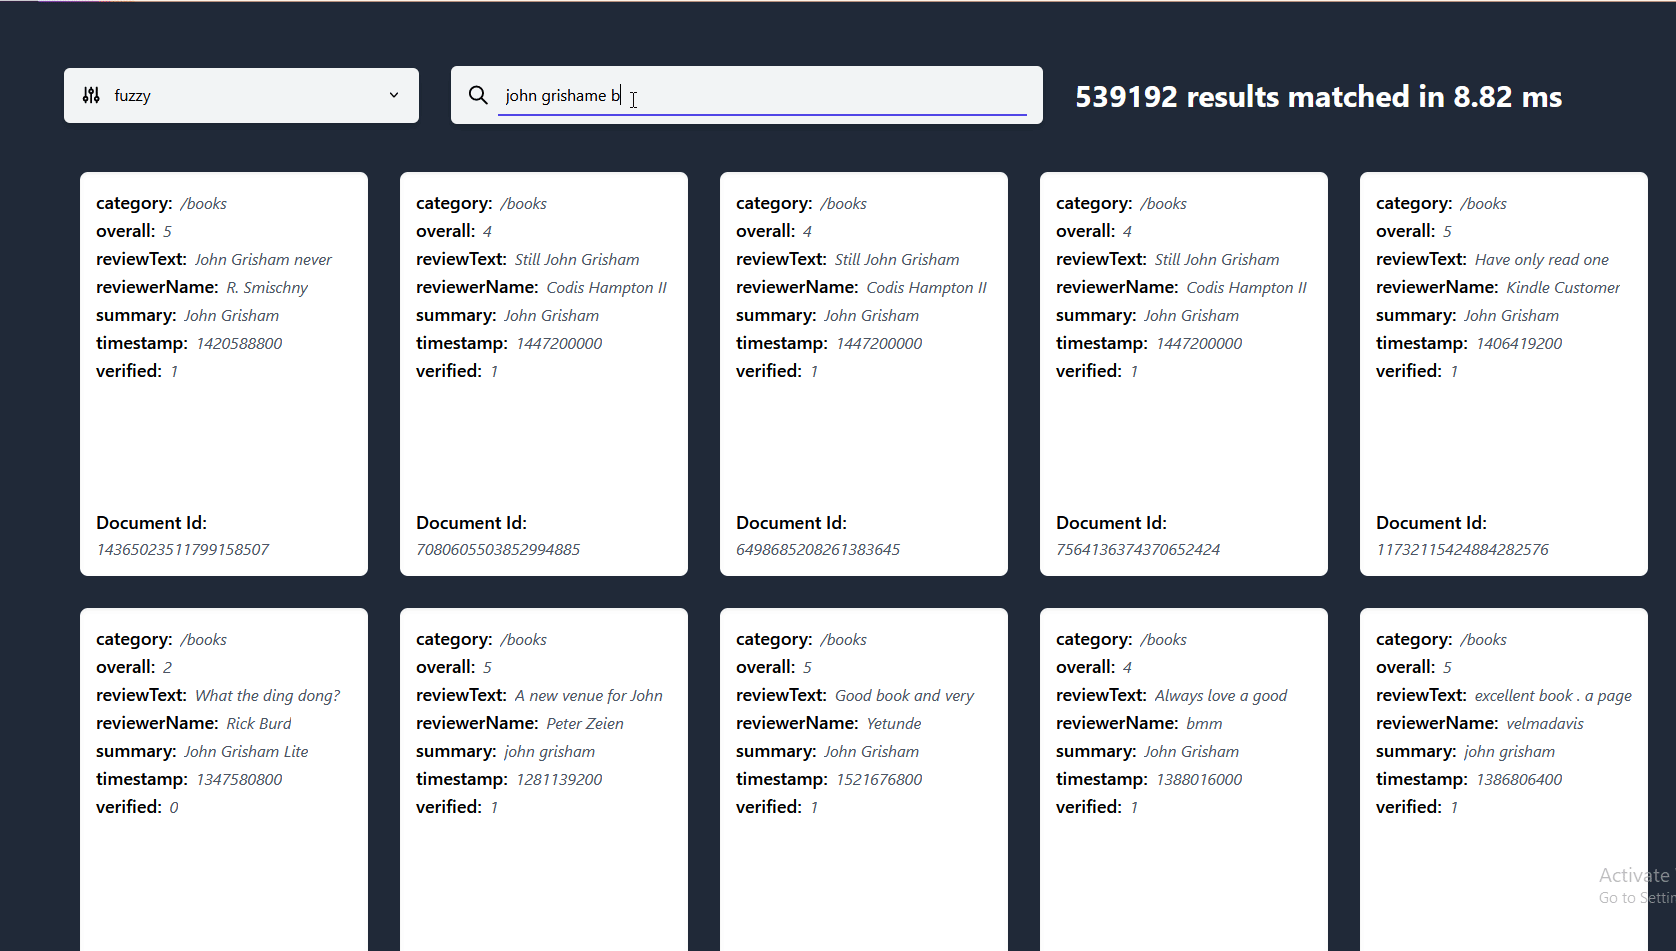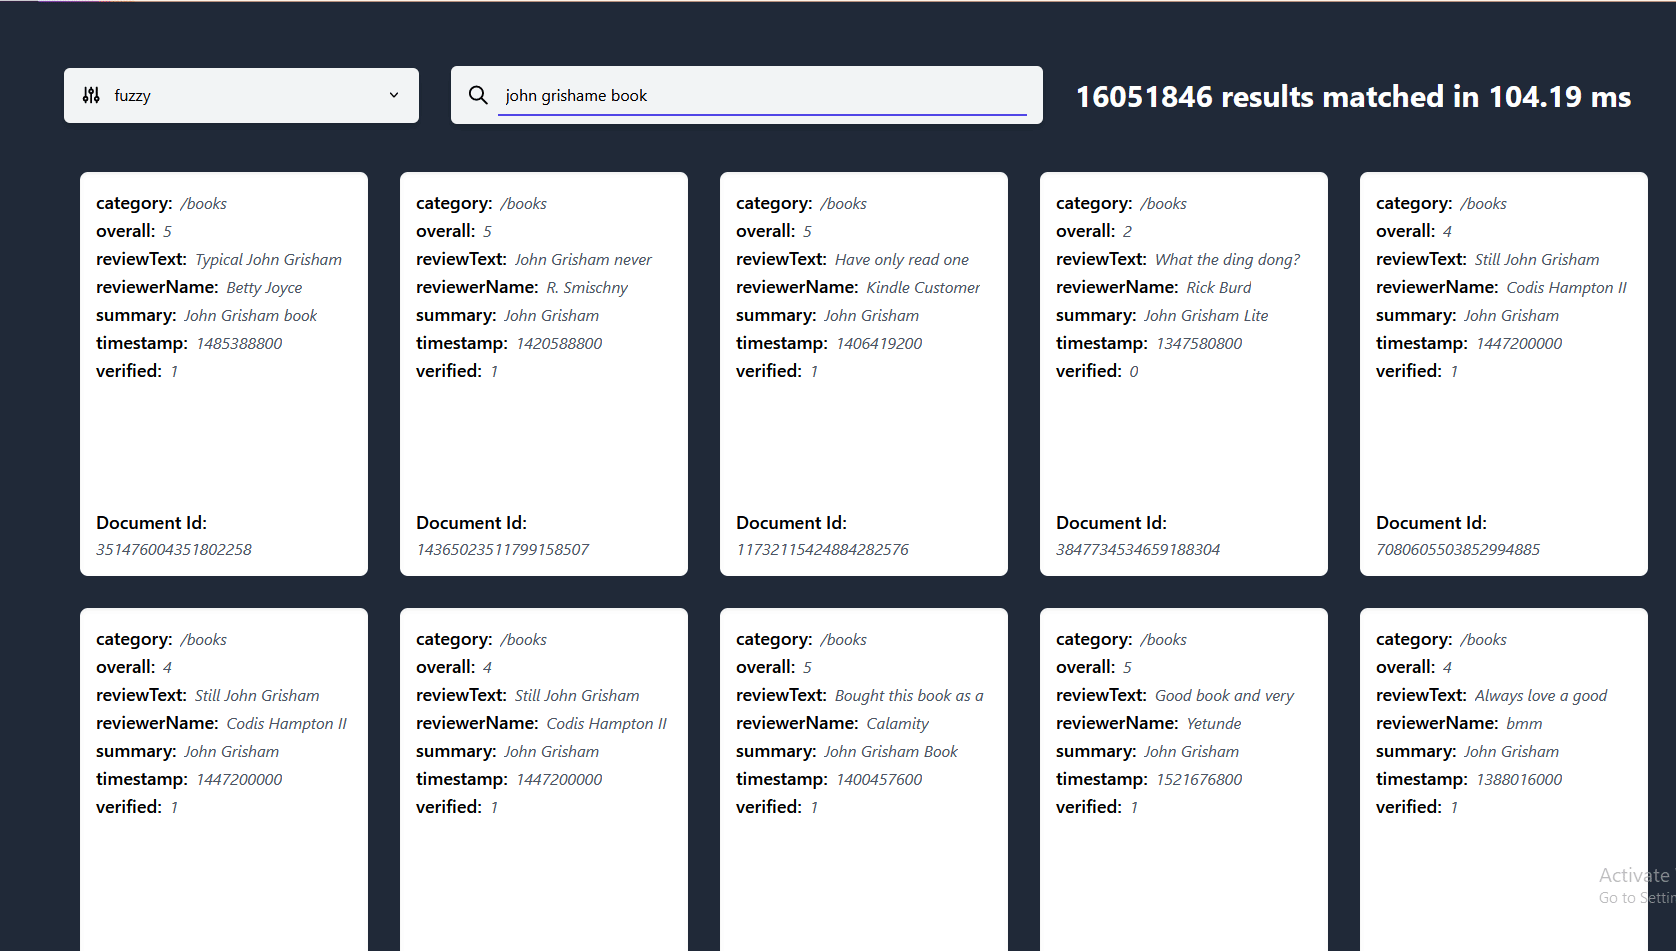
Here you can see lnx doing search as you type on a 27 million document dataset coming in at reasonable 18GB once indexed, ran on my i7-8700k using ~3GB of RAM with our fast-fuzzy system Got a bigger dataset for us to try? Open an issue!
Performance
lnx can provide the ability to fine tune the system to your particular use case. You can customise the async runtime threads. The concurrency thread pool, threads per reader and writer threads, all per index.
This gives you the ability to control in detail where your computing resources are going. Got a large dataset but lower amount of concurrent reads? Bump the reader threads in exchange for lower max concurrency.
The bellow figures were taken by our lnx-cli on the small movies.json dataset, we didn't try any higher as Meilisearch takes an incredibly long time to index millions of docs although the new Meilisearch engine has improved this somewhat.


💔 Limitations
As much as lnx provides a wide range of features, it can not do it all being such a young system. Naturally, it has some limitations:
- lnx is not distributed (yet) so this really does just scale vertically.
- Simple but not too simple, lnx can't offer the same level of ease of use compared to MeiliSearch due to its schema-full nature and wide range of tuning options. With more tuning comes more settings, unfortunately.
- Metrics (yet)
Building from scratch
Requirements
- rustc v1.81+
- sccache
- linux os
Ähnliche Projekte entdecken
Asabeneh/30-Days-Of-Python
Die Programmier-Challenge 30 Days of Python ist eine Schritt-für-Schritt-Anleitung, um die Programmiersprache Python in 30 Tagen zu lernen. Diese Challenge kann mehr als 100 Tage dauern. Gehe in deinem eigenen Tempo vor. Diese Videos können ebenfalls helfen: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 Sternegrafana/grafana
Offene und kombinierbare Plattform für Observability und Datenvisualisierung. Visualisiert Metriken, Logs und Traces aus mehreren Quellen wie Prometheus, Loki, Elasticsearch, InfluxDB, Postgres und vielen weiteren.
77,830 Sterneredis/redis
Für Entwickler, die echtzeitfähige, datengesteuerte Anwendungen erstellen, ist Redis der bevorzugte, schnellste und funktionsreichste Cache, Datenstrukturserver und die entsprechende Abfrageengine für Dokumente und Vektoren.
77,395 Sterneapache/superset
Apache Superset ist eine Plattform für Datenvisualisierung und Datenexploration.
75,473 Sterne