
irajisamurai/2D-Motion-Interface
irajisamurai/2D-Motion-Interface has 26 GitHub stars and 1 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 15:17 UTC. Last push 2026-08-21.
What you can do
- 🔌 Plug-and-play, at very low training cost. The interface is an external module: no modification and no fine-tuning of the pretrained MoLM. E_2D has 9.6M parameters (~22 h) and the real-video adapter A_real only 0.3M (~1 h), both on a single A100 40GB.
- 📈 Comparable to 3D motion inputs. On HumanML3D motion captioning, Avg Drop vs 3D Input is −0.2% (TM2T), +0.4% (MotionGPT), and −2.8% (MG-MotionLLM).
- 🥊 Better than training MoLMs from scratch on 2D. 2D Scratch drops −25.8% (TM2T) and −12.8% (MG-MotionLLM) versus 3D Input — our interface substantially reduces that gap at a fraction of the compute.
- 🔬 2D and 3D motions align in both latent and token space. Discrete token agreement with 3D-derived tokens reaches 44.8% / 59.6% / 67.1% (Top-1/2/3), against a 0.20% random baseline for a codebook of size 512.
Gemessener Sternzuwachs
- in 24h
- 0
- in 7 days
- Aktualisierung verzögert
- in 15 days
- Aktualisierung verzögert
- in 1 month
- Aktualisierung verzögert
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
Über uns
Plug-and-play 2D motion interface for real-world Motion Language Models
Maschinelles LernenREADME.md
Original🕺 A Plug-and-Play 2D Motion Interface
for Real-World Motion Language Models
Kaname Yokoyama1 · Norimichi Ukita1
1 Toyota Technological Institute
🏆 Accepted to HCMIW @ ECCV 2026 — Oral Presentation


🎬 Demo
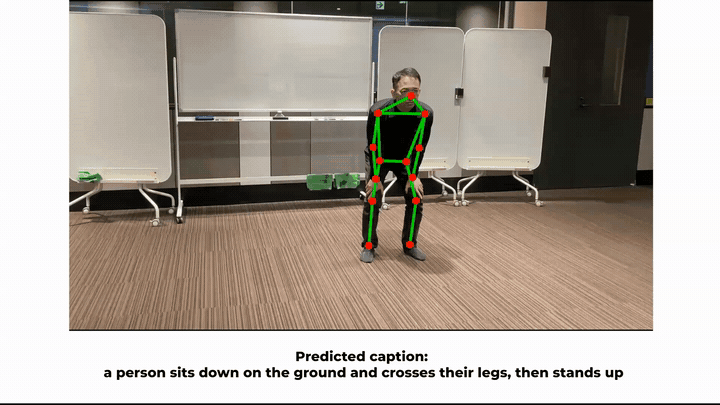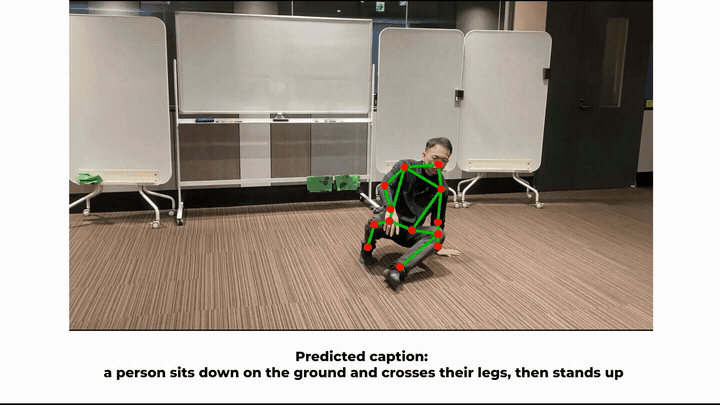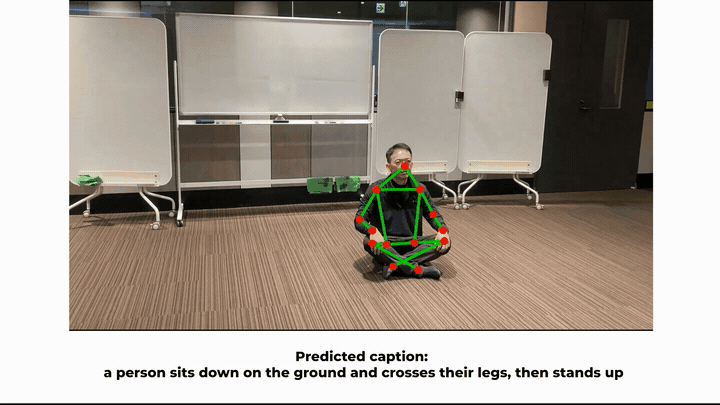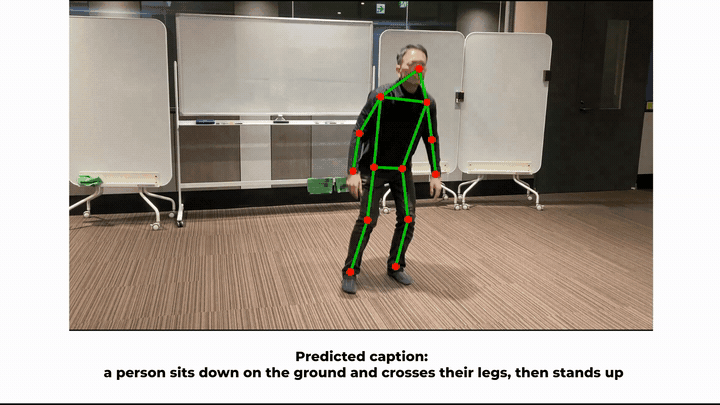
A monocular real video with the estimated ViTPose 2D keypoints overlaid. The caption underneath is generated by our 2D Motion Interface — no 3D pose estimation anywhere in the pipeline.
✨ Highlights
- 🔌 Plug-and-play, at very low training cost. The interface is an external module: no modification and no fine-tuning of the pretrained MoLM.
E_2Dhas 9.6M parameters (~22 h) and the real-video adapterA_realonly 0.3M (~1 h), both on a single A100 40GB. - 📈 Comparable to 3D motion inputs. On HumanML3D motion captioning, Avg Drop vs 3D Input is −0.2% (TM2T), +0.4% (MotionGPT), and −2.8% (MG-MotionLLM).
- 🥊 Better than training MoLMs from scratch on 2D. 2D Scratch drops −25.8% (TM2T) and −12.8% (MG-MotionLLM) versus 3D Input — our interface substantially reduces that gap at a fraction of the compute.
- 🔬 2D and 3D motions align in both latent and token space. Discrete token agreement with 3D-derived tokens reaches 44.8% / 59.6% / 67.1% (Top-1/2/3), against a 0.20% random baseline for a codebook of size 512.
- 🎥 On real monocular video, 2D beats estimated 3D. 2D Input w/
A_realoutperforms all 3D Input settings on almost all metrics across all three MoLMs — while being far cheaper: ViTPose (Base) needs 17.2 GFLOPs/frame versus 250.2 for WHAM. - 🗂 New monocular real-world video motion dataset. 132 videos from 10 participants (14,878 frames / 743.9 s), paired with estimated 2D (ViTPose) and 3D (TRACE, WHAM) motions and HumanML3D captions; 86.4% of video–caption pairs were human-verified as semantically consistent. Publicly released.
📑 Table of Contents
🔍 How It Works
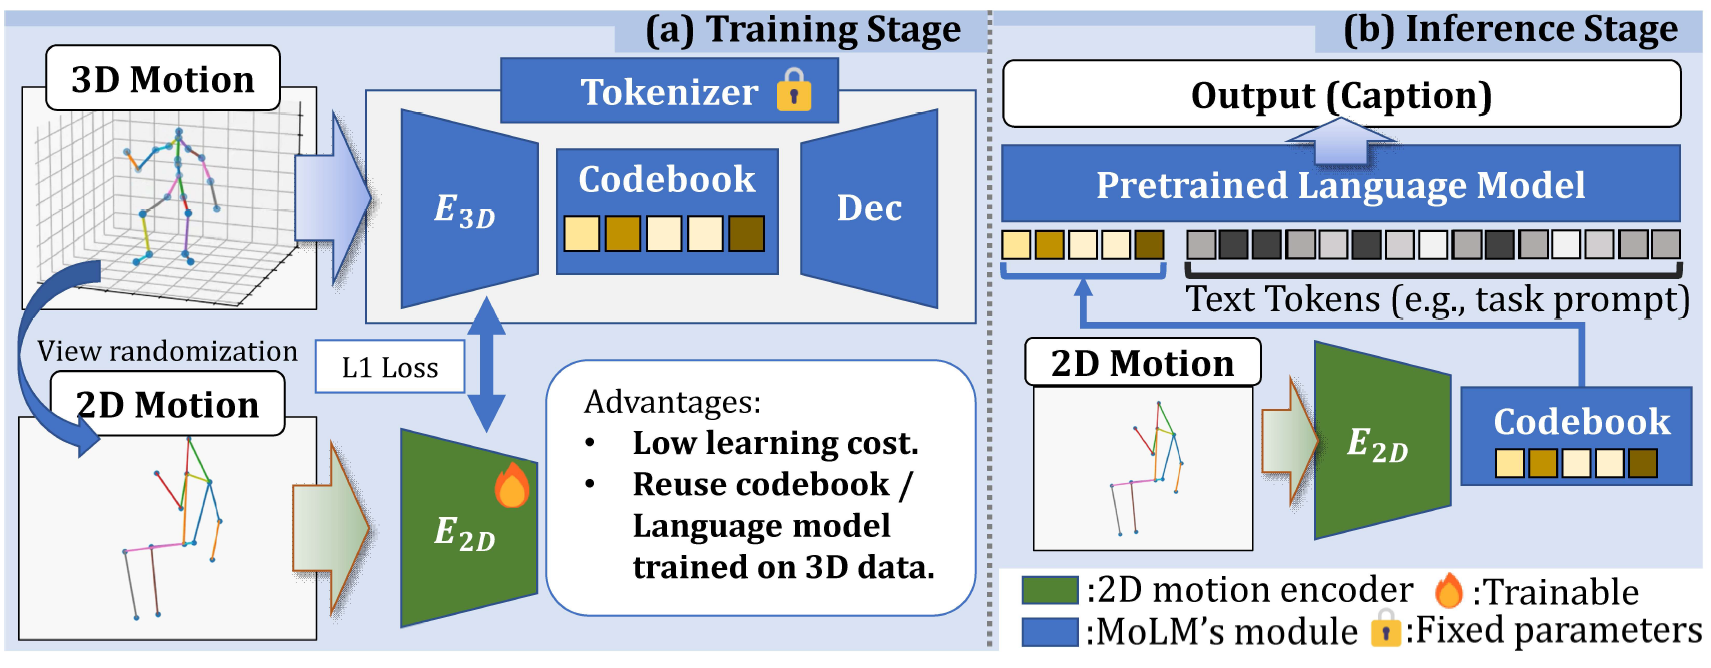
A new 2D motion encoder E_2D is trained to map 2D motion into the same latent space as the MoLM's own 3D encoder, with a simple L1 loss on the latents. The codebook, decoder, and language model stay frozen and are reused as-is, so 2D motion is tokenized by the original codebook and captioned by the pretrained language model — with no 3D pose estimation in the loop.
🎥 On real video: the adapter
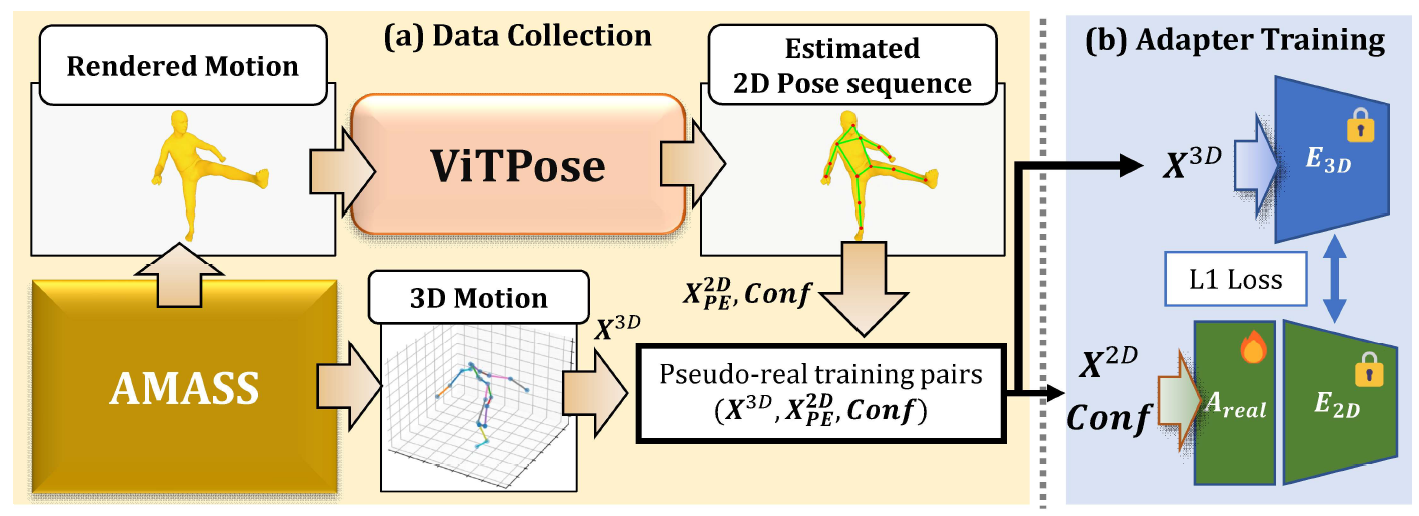
E_2D is trained on clean 2D projections of mocap, while real video adds perspective distortion and pose-estimation noise. A small real-video adapter A_real (0.3M params) inserted before E_2D absorbs that gap. Since real videos have no ground-truth 3D, it is trained on pseudo-real pairs: AMASS motions rendered from random viewpoints, run through ViTPose, and paired with their own 3D.
📊 Headline Results
Both tables report Avg Drop, the average percentage difference from the reference 3D setting across all metrics (higher is better, – is the reference row itself).
1 · Motion captioning on HumanML3D — Avg Drop vs 3D Input. Replacing 3D inputs with our 2D interface costs almost nothing, while training the MoLM from scratch on 2D costs a great deal.
| Base model | 2D Scratch | Ours (2D Motion Interface) |
|---|---|---|
| TM2T | −25.8% | −0.2% |
| MotionGPT | not reported † | +0.4% |
| MG-MotionLLM | −12.8% | −2.8% |
† The MotionGPT 2D-Scratch result is omitted because the official implementation could not be stably retrained; the same reproducibility issue is open in the official repository.
2 · Motion captioning on monocular real videos — Avg Drop vs Ref 3D Input. A_real is our real-video adapter; A_3D is the same adapter applied to WHAM's estimated 3D motion for a fair comparison.
| Base model | 3D (TRACE) | 3D (WHAM) | 2D | 3D (WHAM) w/ A_3D |
2D w/ A_real |
|---|---|---|---|---|---|
| TM2T | −37.7% | −35.9% | −18.5% | −10.8% | +4.3% |
| MotionGPT | −40.3% | −34.1% | −31.4% | −21.1% | −18.5% |
| MG-MotionLLM | −50.7% | −35.6% | −46.7% | −34.9% | −17.5% |
2D Input w/ A_real outperforms all 3D Input settings on almost all metrics across all models — and does so far more cheaply: excluding human detection, ViTPose (Base) requires 17.2 GFLOPs/frame against 250.2 for WHAM.
[!NOTE] Ref 3D Input is the original HumanML3D motion sampled when collecting each video. It is not the strict ground-truth 3D motion of what the participant actually performed, so it serves as a reference point rather than a hard upper bound.
Full per-metric tables are in Reproducing Key Results.
📁 Repository Layout
| Directory | Base Model | Tasks | Role in this work |
|---|---|---|---|
2DMotionGPT/ |
MotionGPT | M2T | Trains the 2D encoder and both adapters — the source of the shared weights |
2DTM2T/ |
TM2T | M2T | Reuses the 2D encoder and adapters above |
2DMG-MotionLLM/ |
MG-MotionLLM | M2T, M2DT | Trains its own 2D encoder and adapters independently |
M2T = motion-to-text · M2DT = motion-to-detailed-text
📦 Installation
Each sub-project uses its own conda environment — the PyTorch versions are mutually incompatible, so all three are needed to reproduce everything.
| Sub-project | Env name | Python | PyTorch | CUDA |
|---|---|---|---|---|
2DMotionGPT/ |
mgpt_2d |
3.10 | 2.9.0 | 11.8 |
2DTM2T/ |
tm2t |
3.7 | 1.13.1 | 10.1 |
2DMG-MotionLLM/ |
mg-motionllm |
3.9 | 2.8.0 | 11.8 |
cd <sub-project>                      # 2DMotionGPT | 2DTM2T | 2DMG-MotionLLM
conda env create -f environment.yml
conda activate <env-name>             # mgpt_2d | tm2t | mg-motionllm
One more environment is needed only to run ViTPose on your own videos (Caption your own video) — the released datasets already ship their 2D keypoints, so reproducing the paper does not need it:
| Purpose | Env name | Python | PyTorch | CUDA | Key packages |
|---|---|---|---|---|---|
| ViTPose 2D pose estimation | openmmlab |
3.8 | 1.9.1 | 11.1 | mmpose 1.1.0 · mmdet 3.1.0 · mmcv 2.0.1 |
cd 2DMotionGPT
conda env create -f environment_openmmlab.yml
📂 Dataset Preparation
All data lives under 2DMotionGPT/dataset/:
2DMotionGPT/dataset/
├── HumanML3D/                     # HumanML3D
│   ├── new_joint_vecs/  texts/  Mean.npy  Std.npy
│   ├── train.txt  val.txt  test.txt  all.txt
│   └── finemotion_texts/          # FineMotion — 2DMG-MotionLLM only
├── real_world_dataset_ver2/       # our real-world video dataset (2D / ViTPose)
├── gt_upper_bound_wham/           # WHAM 3D motions of the same real videos
├── humanml3d_for_render/          # pseudo-real ViTPose 2D pairs — A_real training
└── humanml3d_for_render_wham/     # WHAM 3D pairs — A_3D training
2DTM2T/ and 2DMG-MotionLLM/ need no copy of their own — symlink them to the same data:
# from the repository root
mkdir -p 2DTM2T/dataset 2DMG-MotionLLM/dataset
ln -s ../../2DMotionGPT/dataset/HumanML3D 2DTM2T/dataset/HumanML3D
ln -s ../../2DMotionGPT/dataset/HumanML3D 2DMG-MotionLLM/dataset/HumanML3D
HumanML3D (all three sub-projects)
Follow the HumanML3D repository to download and prepare the dataset. Expected structure:
HumanML3D/
├── new_joint_vecs/
├── texts/
├── Mean.npy
├── Std.npy
├── train.txt
├── val.txt
├── test.txt
└── all.txt
FineMotion (2DMG-MotionLLM only)
Needed for the Motion-to-Detailed-Text task. Download BPMSD_auto.zip and BPMSD_human.zip from the FineMotion repository and place them under dataset/HumanML3D/finemotion_texts/:
dataset/HumanML3D/
├── finemotion_texts/
│   ├── BPMSD_auto.zip
│   ├── BPMSD_auto.json
│   ├── BPMSD_human.zip
│   └── BPMSD_human.json
└── ...
Monocular real-world video motion dataset (ours)
Motion clips were randomly sampled from the HumanML3D test set and shown to participants, who imitated them while being recorded with a single RGB camera (iPhone SE 2nd generation), varying the relative viewpoint between subject and camera. Each video is paired with estimated 2D motion (ViTPose), estimated 3D motion (TRACE and WHAM), and the original HumanML3D caption of the sampled clip. All performers participated with informed consent.
| Videos | 132, from 10 participants (male and female, 20s–50s) |
| Frames / duration | 14,878 frames · 743.9 s |
| Captions | original HumanML3D captions of the sampled clips |
| Human verification | 3 annotators; 86.4% of video–caption pairs judged semantically consistent |
Expected structure:
dataset/
├── HumanML3D/
├── gt_upper_bound_wham/
├── humanml3d_for_render/
├── humanml3d_for_render_wham/
└── real_world_dataset_ver2/
🧠 Pre-trained Checkpoints
Base models and dependencies
GloVe embeddings, evaluators, and base checkpoints come from the original repositories:
# MotionGPT
cd 2DMotionGPT
bash prepare/prepare_t5.sh
bash prepare/download_t2m_evaluators.sh
bash prepare/download_pretrained_models.sh

# MG-MotionLLM
cd 2DMG-MotionLLM
bash prepare/prepare_t5.sh
bash prepare/download_glove.sh
bash prepare/download_vqvae.sh
For MG-MotionLLM, also download the baseline checkpoints and place them in 2DMG-MotionLLM/:
Our checkpoints
⚡ Quick Start
Once Installation, the real-world dataset, and our checkpoints are in place, this single command reproduces the headline real-world result:
cd 2DMotionGPT
conda activate mgpt_2d
python evaluate_with_realworld.py \
    --cfg configs/config_h3d_stage1.yaml --nodebug \
    --estimated_motion_dir ./dataset/real_world_dataset_ver2/pred \
    --vqvae_ckpt ./checkpoints/2d_vqvae_ver3/MotionGPT_2DEncoder/encoder_only-l1-bs64-lr0.0001/best_vqvae_epoch2960_valacc0.4471.tar \
    --adapter_ckpt ./checkpoints/adapter/MotionGPT_2DEncoder/adapter-residual-bs64-lr1e-3/best_adapter_epoch690_valloss1.2251.tar \
    --adapter_type residual \
    --mode both
--mode both evaluates with and without the adapter in one pass, so you get the comparison directly.
🎥 Caption your own video
demo/ runs the whole thing on an arbitrary monocular video — ViTPose 2D pose estimation, then captioning through A_real → E_2D → MotionGPT:
cd 2DMotionGPT
python demo/demo.py --video /path/to/your_video.mp4 --gpu_id 0
The driver only needs the standard library — it runs pose estimation in the openmmlab environment and captioning in mgpt_2d, since mmpose (torch 1.9) and MotionGPT (torch 2.9) cannot share one environment. Interpreters are found automatically; override with POSE_PYTHON / CAPTION_PYTHON if needed. Outputs land in demo/outputs/<video name>/: keypoints.json, overlay.mp4 (skeleton overlay), caption.json, pose_meta.json.
Only the weight bundle in space/bundle/ is required — no HumanML3D, no evaluators. The video is resampled to 20 fps automatically; use --start / --duration to pick a segment, since the model captions at most 196 frames (9.8 s). Best results come from a single person, full body in frame, roughly static camera.
Running the two stages separately
# stage 1 — openmmlab env
python demo/run_vitpose_single.py --video in.mp4 --out_json kp.json --out_video overlay.mp4
# stage 2 — mgpt_2d env
python demo/caption_from_json.py --json kp.json --mode both
📈 Reproducing Key Results
1. M2T Evaluation on HumanML3D (2D encoder vs 3D baseline)
2DMotionGPT — evaluate 2D encoder and 3D baseline side by side:
cd 2DMotionGPT
conda activate mgpt_2d
# 3D baseline
python evaluate_motionGPT.py --gpu_id 7 --eval_3d \
    --output results/eval_3d_bs1.json

# 2D encoder
python evaluate_motionGPT.py --gpu_id 7 \
    --vqvae_ckpt ./checkpoints/2d_vqvae_ver3/MotionGPT_2DEncoder/encoder_only-l1-bs64-lr0.0001/best_vqvae_epoch2960_valacc0.4471.tar \
    --output results/eval_2d_bs1.json
📊 Paper Results — Table 1, MotionGPT (HumanML3D test set)
| Method | R-Prec Top-1↑ | Top-2↑ | Top-3↑ | MM-Dist↓ | BLEU-1↑ | BLEU-4↑ | ROUGE-L↑ | CIDEr↑ | BERTScore↑ | Avg Drop vs 3D↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| 3D Input | 0.516 | 0.707 | 0.803 | 2.994 | 0.429 | 0.062 | 0.345 | 0.079 | 0.316 | – |
| Ours | 0.523 ±0.002 |
0.717 ±0.003 |
0.802 ±0.003 |
2.985 ±0.015 |
0.431 ±0.000 |
0.063 ±0.001 |
0.346 ±0.001 |
0.077 ±0.001 |
0.319 ±0.001 |
+0.4% |
Ours is the mean ± std over three runs. 2D Scratch is not reported for MotionGPT: the official implementation could not be stably retrained, an issue also open in the official repository.
2DMG-MotionLLM — evaluate 3D baseline and 2D encoder sequentially:
cd 2DMG-MotionLLM
# 3D baseline + 2D encoder (2D encoder is auto-detected from checkpoints/2d_vq_train/t2m/)
# M2T
python eval_m2t.py --model_name ./m2t-ft-from-GSPretrained-base
# M2DT
python eval_m2dt.py --model_name ./m2dt-ft-from-GSPretrained-base

# 2D scratch (full VQ-VAE trained from scratch on 2D data)
# M2T
python eval_m2t.py --model_name ./m2t-2drecon-100k/checkpoint-100000 \
    --vqvae_2drecon_ckpt ../2DMotionGPT/checkpoints/2d_vqvae_full/MotionGPT_2DEncoder/full_recon_2d-l1_smooth-bs64-lr0.0001/best_vqvae_epoch2990_valloss0.0354.tar
# M2DT
python eval_m2dt.py --model_name ./m2dt-2drecon/checkpoint-300000 \
    --vqvae_2drecon_ckpt ../2DMotionGPT/checkpoints/2d_vqvae_full/MotionGPT_2DEncoder/full_recon_2d-l1_smooth-bs64-lr0.0001/best_vqvae_epoch2990_valloss0.0354.tar
📊 Paper Results — Tables 1 & 2, MG-MotionLLM
M2T — motion captioning on the HumanML3D test set (Table 1):
| Method | R-Prec Top-1↑ | Top-2↑ | Top-3↑ | MM-Dist↓ | BLEU-1↑ | BLEU-4↑ | ROUGE-L↑ | CIDEr↑ | BERTScore↑ | Avg Drop vs 3D↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| 3D Input | 0.583 | 0.787 | 0.873 | 2.571 | 0.507 | 0.091 | 0.402 | 0.095 | 0.386 | – |
| 2D Scratch | 0.487 | 0.667 | 0.758 | 3.289 | 0.494 | 0.078 | 0.385 | 0.074 | 0.364 | −12.8% |
| Ours | 0.576 | 0.770 | 0.855 | 2.701 | 0.499 | 0.087 | 0.396 | 0.090 | 0.379 | −2.8% |
M2DT — motion-to-detailed-text on the FineMotion test set (Table 2):
| Level | Method | BLEU-1↑ | BLEU-4↑ | BLEU-7↑ | ROUGE-L↑ | BERTScore↑ | Avg Drop vs 3D↑ |
|---|---|---|---|---|---|---|---|
| Sequence | 3D Input | 0.828 | 0.667 | 0.536 | 0.651 | 0.523 | – |
| Sequence | 2D Scratch | 0.814 | 0.637 | 0.497 | 0.629 | 0.483 | −4.9% |
| Sequence | Ours | 0.828 | 0.665 | 0.533 | 0.648 | 0.517 | −0.5% |
| Snippet | 3D Input | 0.672 | 0.478 | 0.354 | 0.606 | 0.509 | – |
| Snippet | 2D Scratch | 0.653 | 0.456 | 0.329 | 0.588 | 0.487 | −4.4% |
| Snippet | Ours | 0.666 | 0.473 | 0.349 | 0.601 | 0.502 | −1.1% |
Ours rows are the mean over three runs (± ≤0.021 on every metric). The M2DT protocol follows MG-MotionLLM and reports BLEU-7 rather than CIDEr.
2. Real-world Evaluation
Requires the real-world video dataset (see Dataset Preparation).
2DMotionGPT:
cd 2DMotionGPT
# ViTPose 2D + 2D Adapter (main result)
python evaluate_with_realworld.py \
    --cfg configs/config_h3d_stage1.yaml --nodebug \
    --estimated_motion_dir ./dataset/real_world_dataset_ver2/pred \
    --vqvae_ckpt ./checkpoints/2d_vqvae_ver3/MotionGPT_2DEncoder/encoder_only-l1-bs64-lr0.0001/best_vqvae_epoch2960_valacc0.4471.tar \
    --adapter_ckpt ./checkpoints/adapter/MotionGPT_2DEncoder/adapter-residual-bs64-lr1e-3/best_adapter_epoch690_valloss1.2251.tar \
    --adapter_type residual \
    --mode both

# WHAM 3D + 3D Adapter
python evaluate_with_realworld_3d_adapter.py \
    --cfg configs/config_h3d_stage1.yaml --nodebug \
    --estimated_motion_dir ./dataset/gt_upper_bound_wham \
    --adapter_ckpt ./checkpoints/adapter3d/MotionGPT_2DEncoder/adapter3d-residual-bs64-lr1e-3/best_adapter3d_epoch880_valloss1.2810.tar \
    --split test \
    --mode both
📊 Paper Results — Table 4, MotionGPT (monocular real-world video motion dataset)
| Method | BLEU-1↑ | BLEU-4↑ | ROUGE-L↑ | CIDEr↑ | BERTScore↑ | Avg Drop vs Ref 3D↑ |
|---|---|---|---|---|---|---|
| Ref 3D Input | 0.461 | 0.069 | 0.405 | 0.149 | 0.352 | – |
| 3D Input (TRACE) | 0.369 | 0.034 | 0.315 | 0.044 | 0.218 | −40.3% |
| 3D Input (WHAM) | 0.380 | 0.035 | 0.339 | 0.056 | 0.264 | −34.1% |
| 2D Input | 0.361 | 0.047 | 0.321 | 0.075 | 0.236 | −31.4% |
3D Input (WHAM) w/ A_3D |
0.408 | 0.046 | 0.365 | 0.102 | 0.285 | −21.1% |
2D Input w/ A_real |
0.435 | 0.045 | 0.367 | 0.105 | 0.306 | −18.5% |
Bold marks the best value among the estimated-motion rows (Ref 3D Input is a reference, not a competitor).
2DMG-MotionLLM:
cd 2DMG-MotionLLM
# ViTPose 2D + 2D Adapter (main result)
python evaluate_with_realworld.py \
    --estimated_motion_dir ../2DMotionGPT/dataset/real_world_dataset_ver2/pred \
    --adapter_ckpt ./checkpoints/adapter/MG-MotionLLM/best_adapter_epoch2520_valloss1.1380.pt \
    --adapter_type residual \
    --meta_dir ../2DMotionGPT/deps/t2m/t2m/VQVAEV3_CB1024_CMT_H1024_NRES3/meta \
    --data_root ./dataset/HumanML3D \
    --split test \
    --mode both \
    --gpu_id 0

# WHAM 3D + 3D Adapter
python evaluate_with_realworld_3d_adapter.py \
    --estimated_motion_dir ../2DMotionGPT/dataset/gt_upper_bound_wham \
    --adapter_ckpt ./checkpoints/adapter3d/MG-MotionLLM/best_adapter3d_epoch610_valloss1.1204.pt \
    --meta_dir ../2DMotionGPT/deps/t2m/t2m/VQVAEV3_CB1024_CMT_H1024_NRES3/meta \
    --data_root ./dataset/HumanML3D \
    --split test \
    --gpu_id 0 \
    --mode both
📊 Paper Results — Table 4, MG-MotionLLM (monocular real-world video motion dataset)
| Method | BLEU-1↑ | BLEU-4↑ | ROUGE-L↑ | CIDEr↑ | BERTScore↑ | Avg Drop vs Ref 3D↑ |
|---|---|---|---|---|---|---|
| Ref 3D Input | 0.556 | 0.117 | 0.450 | 0.233 | 0.436 | – |
| 3D Input (TRACE) | 0.385 | 0.033 | 0.310 | 0.058 | 0.240 | −50.7% |
| 3D Input (WHAM) | 0.433 | 0.064 | 0.350 | 0.095 | 0.308 | −35.6% |
| 2D Input | 0.392 | 0.044 | 0.321 | 0.062 | 0.264 | −46.7% |
3D Input (WHAM) w/ A_3D |
0.469 | 0.036 | 0.378 | 0.106 | 0.352 | −34.9% |
2D Input w/ A_real |
0.507 | 0.093 | 0.411 | 0.151 | 0.374 | −17.5% |
🎯 Training
Three steps: (1) train the 2D motion encoder E_2D, (2) train the real-video adapter A_real for ViTPose inputs, (3) train the adapter A_3D for estimated-3D inputs (the fair-comparison arm).
[!TIP] The 2D interface requires no training for 2DTM2T. It reuses
E_2Dand the adapters trained in2DMotionGPT/— which is the whole point of the plug-and-play design. (The TM2T base model itself was retrained once with the matched VQ-VAE architecture; see Repository Layout.)
Step 1: Train 2D Encoder
2DMotionGPT (encoder-only; also used by 2DTM2T):
cd 2DMotionGPT
python train_2d_vqvae_ver4_coco_normalized.py \
    --cfg configs/config_h3d_stage1.yaml --nodebug
2DMG-MotionLLM (trains its own 2D encoder independently):
cd 2DMG-MotionLLM
python 2d_vq_train.py --dataname t2m
Step 2: Train 2D Adapter (ViTPose → latent space)
2DMotionGPT (adapter also used by 2DTM2T):
cd 2DMotionGPT
python -m train_adapter \
    --cfg configs/config_h3d_stage1.yaml --nodebug \
    --vqvae_ckpt ./checkpoints/2d_vqvae_ver3/MotionGPT_2DEncoder/encoder_only-l1-bs64-lr0.0001/best_vqvae_epoch2960_valacc0.4471.tar \
    --estimated_motion_dir ./dataset/humanml3d_for_render
2DMG-MotionLLM:
cd 2DMG-MotionLLM
python -u train_adapter.py \
    --vqvae_2d_ckpt ./checkpoints/2d_vq_train/t2m/best_2dvq_epoch1881_ratio0.5557.pt \
    --estimated_motion_dir ../2DMotionGPT/dataset/humanml3d_for_render \
    --meta_dir ../2DMotionGPT/deps/t2m/t2m/VQVAEV3_CB1024_CMT_H1024_NRES3/meta \
    --data_root ./dataset/HumanML3D \
    --ckpt_save_dir ./checkpoints/adapter/MG-MotionLLM \
    --max_epochs 3000 --batch_size 64 --val_every 10 \
    --adapter_type residual \
    --wandb_project MG-MotionLLM-Adapter \
    --gpu_id 7
Step 3: Train 3D Adapter (WHAM → latent space)
2DMotionGPT (adapter also used by 2DTM2T):
cd 2DMotionGPT
python train_adapter_3d.py \
    --cfg configs/config_h3d_stage1.yaml --nodebug \
    --estimated_motion_dir ./dataset/humanml3d_for_render_wham
2DMG-MotionLLM:
cd 2DMG-MotionLLM
python train_adapter_3d.py \
    --estimated_motion_dir ../2DMotionGPT/dataset/humanml3d_for_render_wham \
    --val_every 10 \
    --val_text_every 100
🚧 Limitations
- Over-generalized captions. On real videos, MotionGPT and MG-MotionLLM show a larger Avg Drop vs Ref 3D than TM2T. A likely cause is that newer MoLMs generate more detailed descriptions, while the adapter's correction smooths the motion sequence and suppresses fine-grained differences, pushing the representation toward an average motion pattern. Decoding the 2D-derived tokens back through the VQ-VAE decoder confirms this: with the adapter, an S-shaped walking trajectory is no longer preserved in the reconstructed root trajectory.
- Imitation error in the dataset. Because videos were collected by asking participants to imitate HumanML3D motions, discrepancies between the reference motion and the performed motion can cause semantic mismatches (86.4% of pairs were verified as consistent).
- Scope of the 2D-vs-3D conclusion. The comparison holds under the evaluated monocular pose-estimation setting (TRACE, WHAM, ViTPose), and the analysis is conducted where 2D features are explicitly aligned to the 3D latent space. It does not establish that 3D-specific information is unnecessary in general.
📖 Citation
If you find this work useful, please consider citing:
@inproceedings{yokoyama2026plugandplay,
  title     = {A Plug-and-Play 2D Motion Interface for Real-World Motion Language Models},
  author    = {Yokoyama, Kaname and Ukita, Norimichi},
  booktitle = {Proceedings of the European Conference on Computer Vision (ECCV) Workshops,
               Human-Centric Motion Intelligence Workshop (HCMIW)},
  note      = {Oral Presentation},
  year      = {2026}
}
🙏 Acknowledgements
This work builds on the following excellent projects — we thank the authors for releasing their code and data: