
iamazy/elasticsearch-sql
iamazy/elasticsearch-sql has 346 GitHub stars and 90 forks. Star changes are not measured yet. Last checked 2026-11-14 12:27 UTC. Last push 2023-06-14.
What you can do
- SQL Order by (Asc & Desc)
- ES Aggregate by
- SQL Between And
- SQL > & < & >= & <=
Gemessener Sternzuwachs
- in 24h
- Verlauf wird gesammelt
- in 7 days
- Verlauf wird gesammelt
- in 15 days
- Verlauf wird gesammelt
- in 1 month
- Verlauf wird gesammelt
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
Über uns
parse sql into elasticsearch dsl with antlr4
DatenREADME.md
OriginalDescription
rewrite elasticsearch-sql2 with antlr4, support jdbc
Changelog
Maven
<dependency>
    <groupId>io.github.iamazy.elasticsearch.dsl</groupId>
    <artifactId>elasticsearch-sql-all</artifactId>
    <version>${latest.version}</version>
</dependency>
或者
<dependencies>
    <dependency>
        <groupId>io.github.iamazy.elasticsearch.dsl</groupId>
        <artifactId>elasticsearch-sql-core</artifactId>
        <version>${latest.version}</version>
    </dependency>
    <dependency>
        <groupId>io.github.iamazy.elasticsearch.dsl</groupId>
        <artifactId>elasticsearch-sql-jdbc</artifactId>
        <version>${latest.version}</version>
    </dependency>
</dependencies>
Plugin(isql)
Installing
Elasticsearch {7.x}
./bin/elasticsearch-plugin install https://github.com/iamazy/elasticsearch-sql/releases/download/{isql-version}/elasticsearch-sql-plugin-{elasticsearch-version}.zip
Usage
1. query dataset with sql
POST _isql
{
    "sql":"select * from fruit"
}
2. parse sql into elasticsearch dsl
POST _isql/_explain
{
    "sql":"select * from fruit"
}
Wiki
Features
1. Based on antlr4
customize grammer of elasticsearch sql
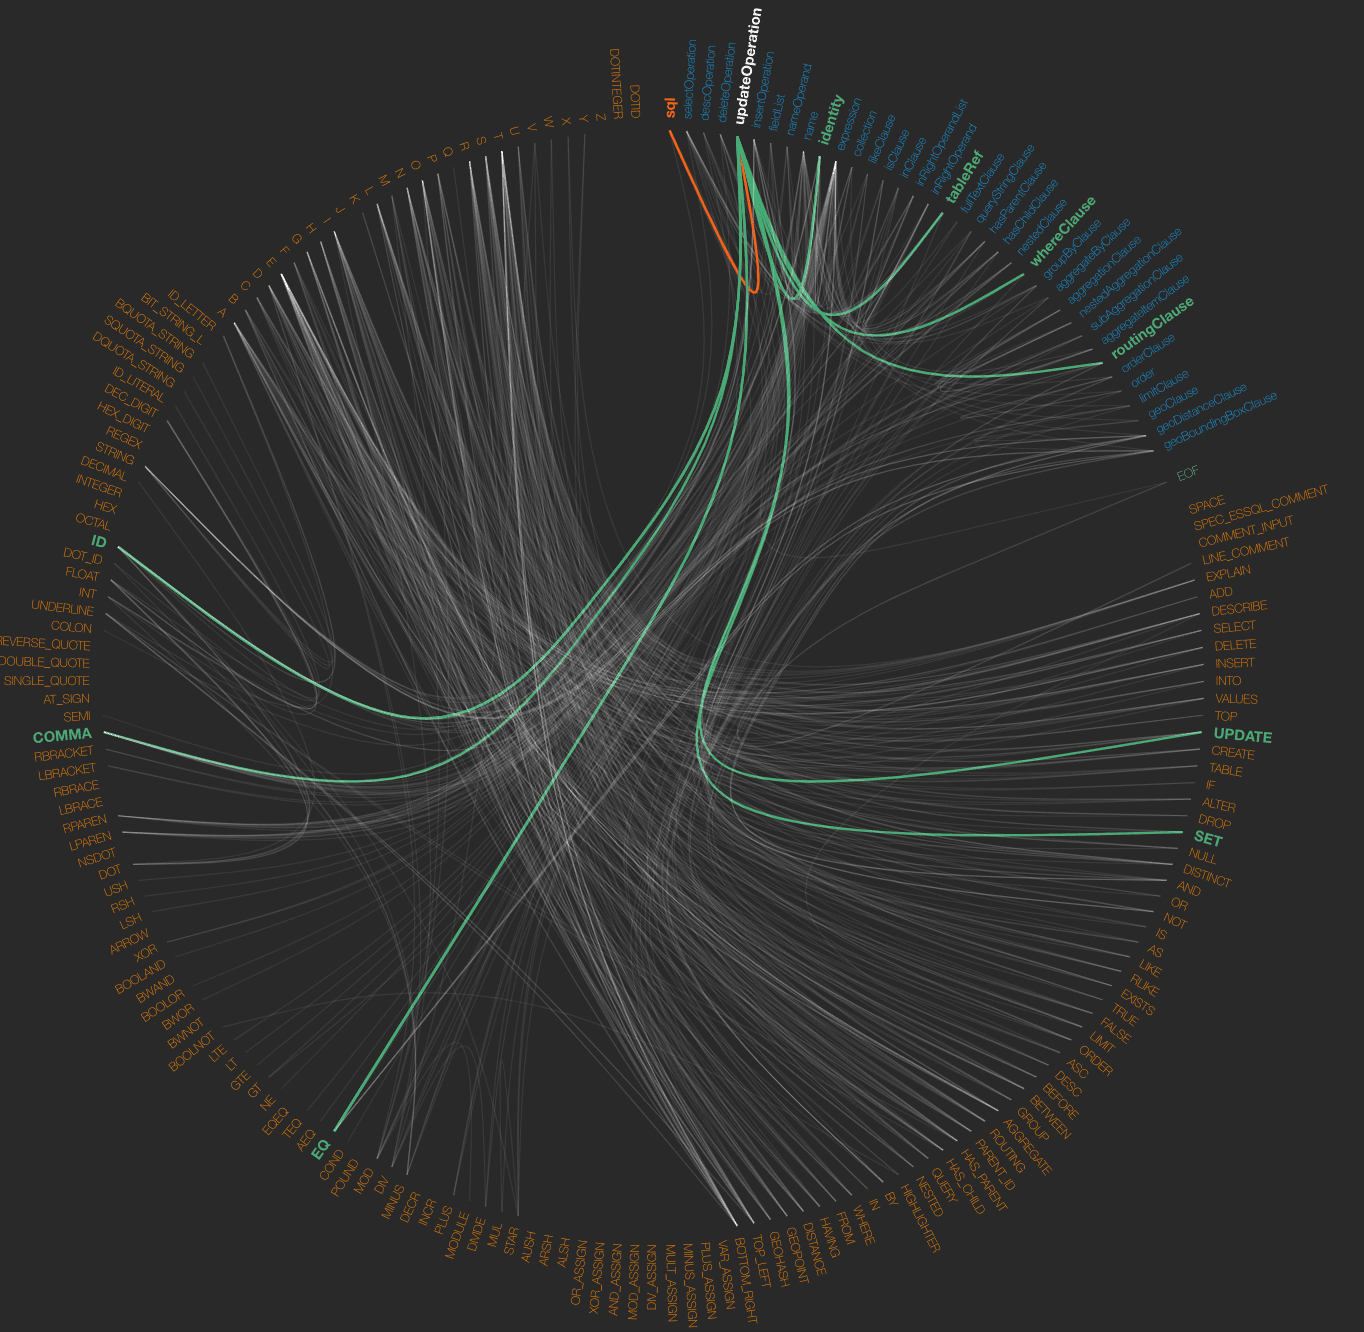
support analyse the walk of sql ast and the relation of tokens
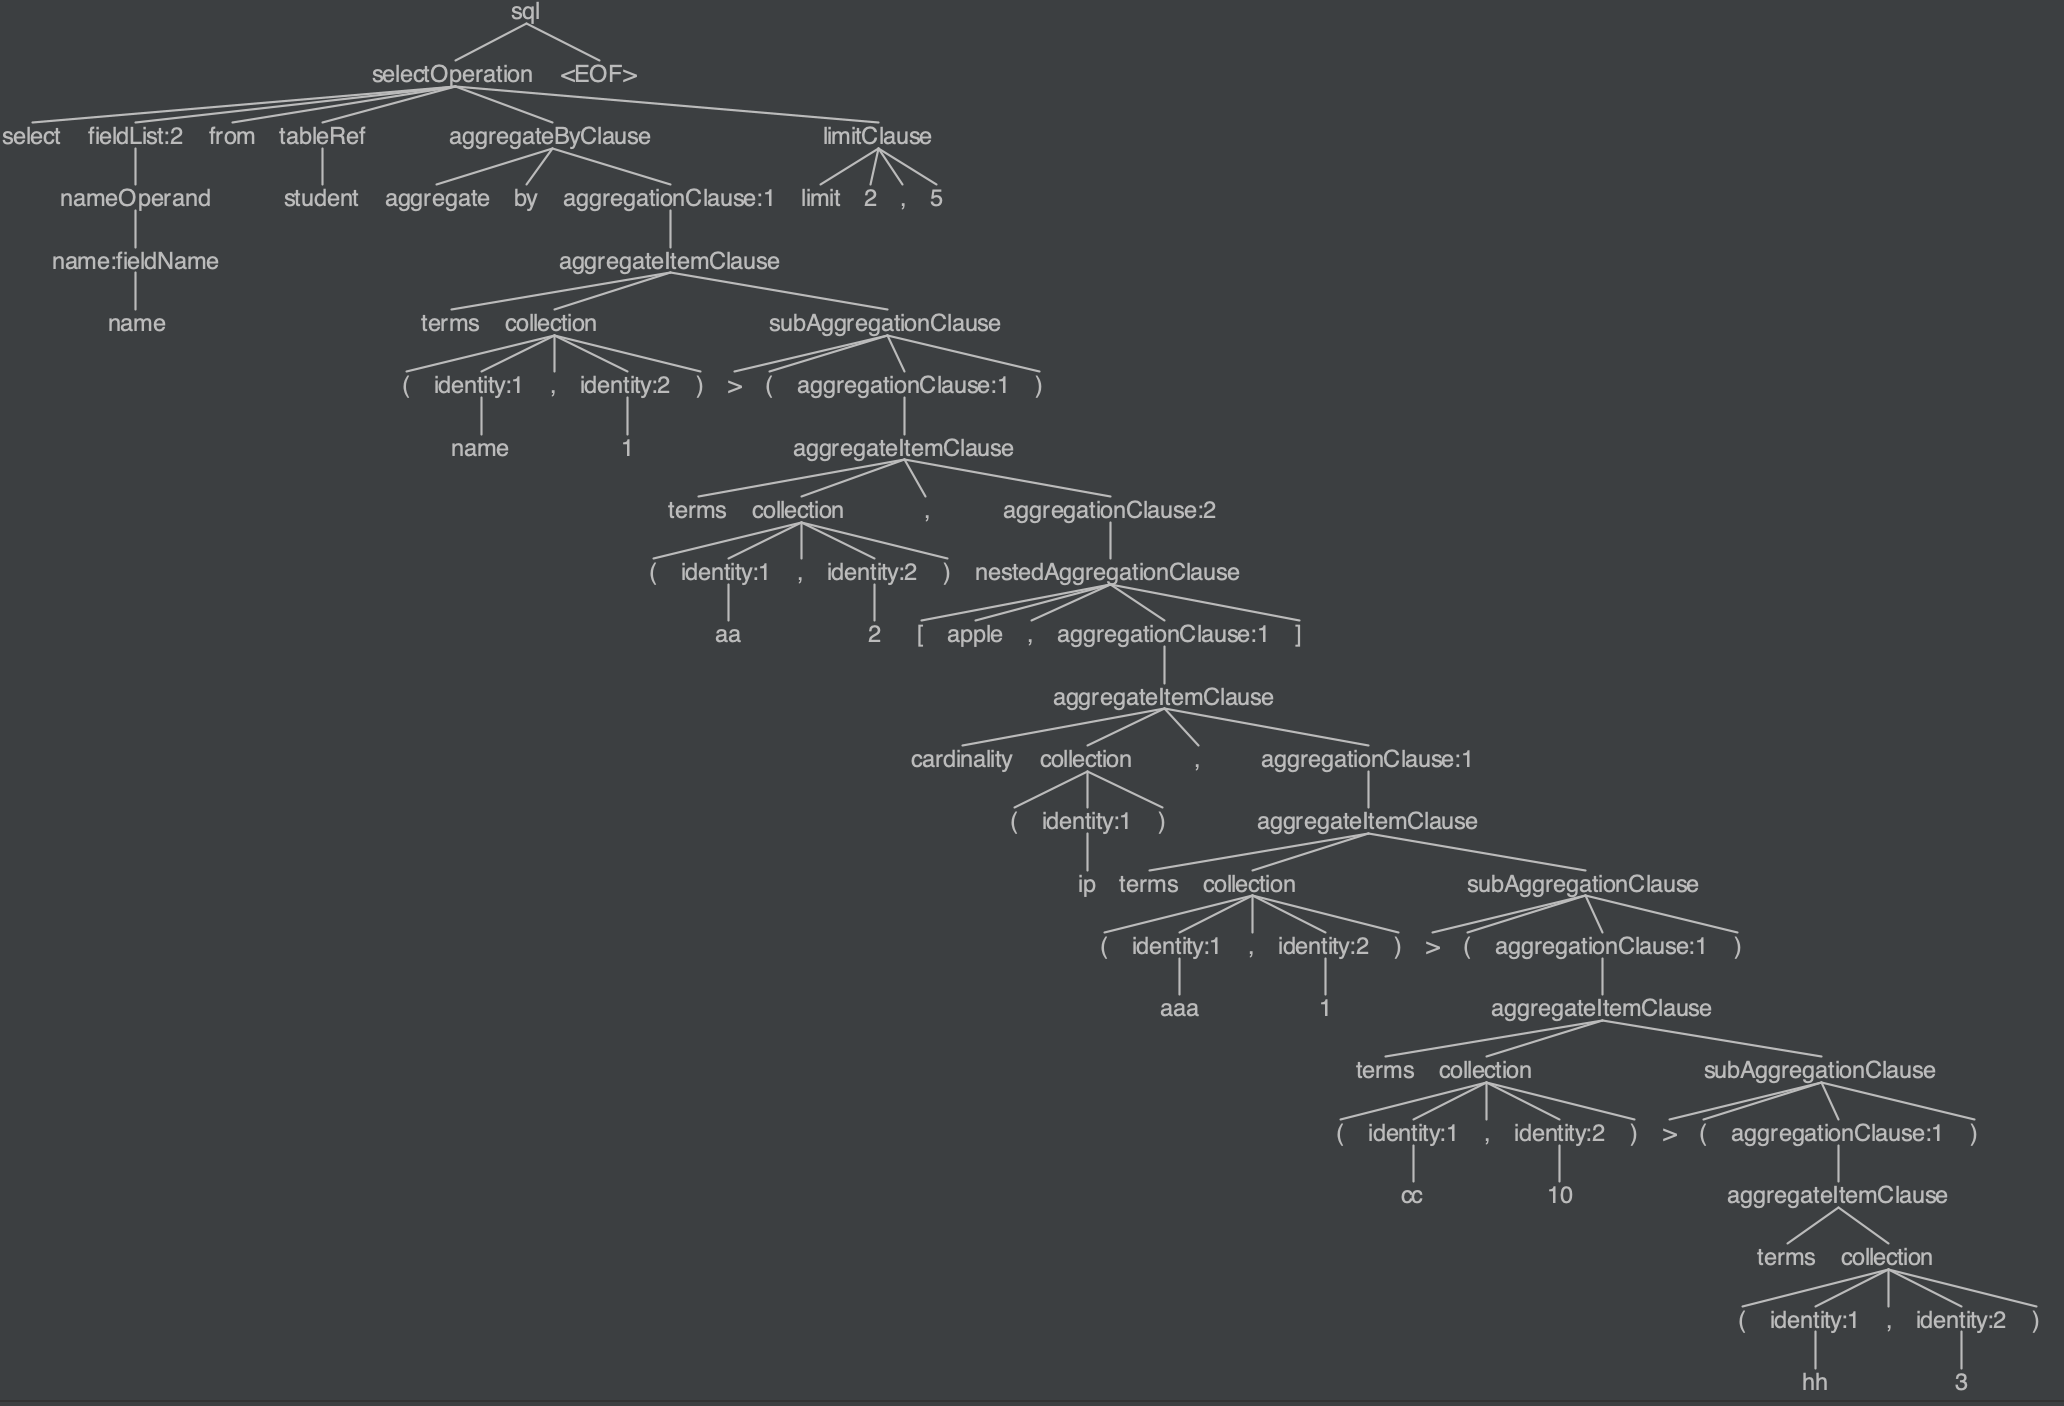
Ast
select name from student aggregate by terms(name,1)>(terms(aa,2),[apple,cardinality(ip),terms(aaa,1)>(terms(cc,10)>(terms(hh,3
)))]) limit 2,5
Relation of Tokens
2. Based on elasticsearch java rest high level client
support for request from third-party http component
cross-language
support for parsing sql into elasticsearch dsl
support x-pack
no need for request pool
3. Integrte into elasticsearch(isql)
Features
- SQL Select
- SQL Where
- SQL Order by (Asc & Desc)
- SQL Group by
- ES Aggregate by
- SQL And & Or
- SQL In
- SQL Between And
- SQL Is
- SQL Not
- SQL Null
- SQL Nvl
- SQL Max
- SQL Min
- SQL Sum
- SQL Avg
- SQL > & < & >= & <=
- ES Explain
- ES FullText
- ES Match
- ES MultiMatch
- ES QueryString
- ES SimpleQueryString
- ES HasParent
- ES HasChild
- ES Join
- ES Script
- ES Fuzzy
- ES Prefix
- ES Regex
- ES Term
- ES Wildcard
- ES Routing
- ES Nested Query
- ES Nested Aggregation
- ES Include & Exclude
- ES From
- ES Size
- ES Range(Number,Date)
- ES MatchAll
- ES MatchPhrase
- ES MatchPhrasePrefix
- ES DeleteByQuery
- ES Cardinality
- ES TopHits
- ES Nested
- ES GeoDistance
- ES GeoBoundingBox
- ES GeoPolygon
- ES GeoShape
- ES GeoJsonShape
- ES SubAggregation
- ES Scroll Id
- ES Highlighter
- ES Boosting
- ES Function Score
- ES Disjunction Max (DisMax)
- SQL Like
- SQL Desc
- ES Reindex
- ES Track Total Hits
- SQL Update
- ES Update By Query
- SQL Delete
- ES DeleteByQuery
- SQL Insert
- Java Jdbc
Todo
- SQL Having
- SQL Customise Function
- ES Analysis
- ES Boosting
- ...
Examples
1. select,include,exclude,from,where,in,and,or,has_parent,geo_distance,limit
select name,^h!age,h!gender from student where ((a in (1,2,3,4)) and has_parent(apple,bb~='fruit')) and c=1 and (coordinate = [40.0,30.0] and distance = '1km' or t='bb') limit 2,5
generate dsl
{
  "from" : 2,
  "size" : 5,
  "query" : {
    "bool" : {
      "must" : [ {
        "terms" : {
          "a" : [ "1", "2", "3", "4" ],
          "boost" : 1.0
        }
      }, {
        "has_parent" : {
          "query" : {
            "bool" : {
              "must" : [ {
                "match" : {
                  "bb" : {
                    "query" : "'fruit'",
                    "operator" : "OR",
                    "prefix_length" : 0,
                    "max_expansions" : 50,
                    "fuzzy_transpositions" : true,
                    "lenient" : false,
                    "zero_terms_query" : "NONE",
                    "auto_generate_synonyms_phrase_query" : true,
                    "boost" : 1.0
                  }
                }
              } ],
              "adjust_pure_negative" : true,
              "minimum_should_match" : "1",
              "boost" : 1.0
            }
          },
          "parent_type" : "apple",
          "score" : true,
          "ignore_unmapped" : false,
          "boost" : 1.0
        }
      }, {
        "term" : {
          "c" : {
            "value" : "1",
            "boost" : 1.0
          }
        }
      } ],
      "should" : [ {
        "geo_distance" : {
          "coordinate" : [ 30.0, 40.0 ],
          "distance" : 1000.0,
          "distance_type" : "arc",
          "validation_method" : "STRICT",
          "ignore_unmapped" : false,
          "boost" : 1.0
        }
      }, {
        "term" : {
          "t" : {
            "value" : "'bb'",
            "boost" : 1.0
          }
        }
      } ],
      "adjust_pure_negative" : true,
      "minimum_should_match" : "1",
      "boost" : 1.0
    }
  },
  "_source" : {
    "includes" : [ "name", "gender" ],
    "excludes" : [ "age" ]
  }
}
2. nested,query_string,match(~==)
select name from student where (([class1, age>1 and [class1.class2, name='hhha']] and c=1) or b~=='hhhhh') and query by 'apppple' limit 2,5
generate dsl
{
  "from" : 2,
  "size" : 5,
  "query" : {
    "bool" : {
      "must" : [ {
        "query_string" : {
          "query" : "apppple",
          "fields" : [ ],
          "type" : "best_fields",
          "default_operator" : "or",
          "max_determinized_states" : 10000,
          "enable_position_increments" : true,
          "fuzziness" : "AUTO",
          "fuzzy_prefix_length" : 0,
          "fuzzy_max_expansions" : 50,
          "phrase_slop" : 0,
          "escape" : false,
          "auto_generate_synonyms_phrase_query" : true,
          "fuzzy_transpositions" : true,
          "boost" : 1.0
        }
      } ],
      "should" : [ {
        "bool" : {
          "must" : [ {
            "nested" : {
              "query" : {
                "bool" : {
                  "must" : [ {
                    "range" : {
                      "age" : {
                        "from" : "1",
                        "to" : null,
                        "include_lower" : false,
                        "include_upper" : true,
                        "boost" : 1.0
                      }
                    }
                  }, {
                    "nested" : {
                      "query" : {
                        "bool" : {
                          "must" : [ {
                            "term" : {
                              "name" : {
                                "value" : "'hhha'",
                                "boost" : 1.0
                              }
                            }
                          } ],
                          "adjust_pure_negative" : true,
                          "minimum_should_match" : "1",
                          "boost" : 1.0
                        }
                      },
                      "path" : "class1.class2",
                      "ignore_unmapped" : false,
                      "score_mode" : "avg",
                      "boost" : 1.0
                    }
                  } ],
                  "adjust_pure_negative" : true,
                  "minimum_should_match" : "1",
                  "boost" : 1.0
                }
              },
              "path" : "class1",
              "ignore_unmapped" : false,
              "score_mode" : "avg",
              "boost" : 1.0
            }
          }, {
            "term" : {
              "c" : {
                "value" : "1",
                "boost" : 1.0
              }
            }
          } ],
          "adjust_pure_negative" : true,
          "boost" : 1.0
        }
      }, {
        "match_phrase" : {
          "b" : {
            "query" : "'hhhhh'",
            "slop" : 0,
            "zero_terms_query" : "NONE",
            "boost" : 1.0
          }
        }
      } ],
      "adjust_pure_negative" : true,
      "minimum_should_match" : "1",
      "boost" : 1.0
    }
  },
  "_source" : {
    "includes" : [ "name" ],
    "excludes" : [ ]
  }
}
3. aggregate by
select name from student aggregate by terms(name,1)>(terms(aa,2),terms(bb,3)>(terms(cc,4))),terms(age,10)>(terms(weight,10))
generate dsl
{
  "from" : 0,
  "size" : 15,
  "query" : {
    "match_all" : {
      "boost" : 1.0
    }
  },
  "_source" : {
    "includes" : [ "name" ],
    "excludes" : [ ]
  },
  "aggregations" : {
    "name" : {
      "terms" : {
        "size" : 1,
        "shard_size" : 2,
        "min_doc_count" : 1,
        "shard_min_doc_count" : 1,
        "show_term_doc_count_error" : false,
        "order" : [ {
          "_count" : "desc"
        }, {
          "_key" : "asc"
        } ]
      },
      "aggregations" : {
        "aa" : {
          "terms" : {
            "size" : 2,
            "shard_size" : 4,
            "min_doc_count" : 1,
            "shard_min_doc_count" : 1,
            "show_term_doc_count_error" : false,
            "order" : [ {
              "_count" : "desc"
            }, {
              "_key" : "asc"
            } ]
          }
        },
        "bb" : {
          "terms" : {
            "size" : 3,
            "shard_size" : 6,
            "min_doc_count" : 1,
            "shard_min_doc_count" : 1,
            "show_term_doc_count_error" : false,
            "order" : [ {
              "_count" : "desc"
            }, {
              "_key" : "asc"
            } ]
          },
          "aggregations" : {
            "cc" : {
              "terms" : {
                "size" : 4,
                "shard_size" : 8,
                "min_doc_count" : 1,
                "shard_min_doc_count" : 1,
                "show_term_doc_count_error" : false,
                "order" : [ {
                  "_count" : "desc"
                }, {
                  "_key" : "asc"
                } ]
              }
            }
          }
        }
      }
    },
    "age" : {
      "terms" : {
        "size" : 10,
        "shard_size" : 20,
        "min_doc_count" : 1,
        "shard_min_doc_count" : 1,
        "show_term_doc_count_error" : false,
        "order" : [ {
          "_count" : "desc"
        }, {
          "_key" : "asc"
        } ]
      },
      "aggregations" : {
        "weight" : {
          "terms" : {
            "size" : 10,
            "shard_size" : 20,
            "min_doc_count" : 1,
            "shard_min_doc_count" : 1,
            "show_term_doc_count_error" : false,
            "order" : [ {
              "_count" : "desc"
            }, {
              "_key" : "asc"
            } ]
          }
        }
      }
    }
  }
}
4. nested aggregation,subAggregation(~)
select name from student aggregate by terms(name,1)>(terms(aa,2),[apple,cardinality(ip),terms(aaa,1)>(terms(bb,1),terms(cc,10)>(terms(hh,3),avg(age)),terms(vv,1))]) limit 2,5
generate dsl
{
  "from" : 2,
  "size" : 5,
  "query" : {
    "match_all" : {
      "boost" : 1.0
    }
  },
  "_source" : {
    "includes" : [ "name" ],
    "excludes" : [ ]
  },
  "aggregations" : {
    "name" : {
      "terms" : {
        "size" : 1,
        "shard_size" : 2,
        "min_doc_count" : 1,
        "shard_min_doc_count" : 1,
        "show_term_doc_count_error" : false,
        "order" : [ {
          "_count" : "desc"
        }, {
          "_key" : "asc"
        } ]
      },
      "aggregations" : {
        "aa" : {
          "terms" : {
            "size" : 2,
            "shard_size" : 4,
            "min_doc_count" : 1,
            "shard_min_doc_count" : 1,
            "show_term_doc_count_error" : false,
            "order" : [ {
              "_count" : "desc"
            }, {
              "_key" : "asc"
            } ]
          }
        },
        "nested_apple" : {
          "nested" : {
            "path" : "apple"
          },
          "aggregations" : {
            "ip_cardinality" : {
              "cardinality" : {
                "field" : "ip"
              }
            },
            "aaa" : {
              "terms" : {
                "size" : 1,
                "shard_size" : 2,
                "min_doc_count" : 1,
                "shard_min_doc_count" : 1,
                "show_term_doc_count_error" : false,
                "order" : [ {
                  "_count" : "desc"
                }, {
                  "_key" : "asc"
                } ]
              },
              "aggregations" : {
                "bb" : {
                  "terms" : {
                    "size" : 1,
                    "shard_size" : 2,
                    "min_doc_count" : 1,
                    "shard_min_doc_count" : 1,
                    "show_term_doc_count_error" : false,
                    "order" : [ {
                      "_count" : "desc"
                    }, {
                      "_key" : "asc"
                    } ]
                  }
                },
                "cc" : {
                  "terms" : {
                    "size" : 10,
                    "shard_size" : 20,
                    "min_doc_count" : 1,
                    "shard_min_doc_count" : 1,
                    "show_term_doc_count_error" : false,
                    "order" : [ {
                      "_count" : "desc"
                    }, {
                      "_key" : "asc"
                    } ]
                  },
                  "aggregations" : {
                    "hh" : {
                      "terms" : {
                        "size" : 3,
                        "shard_size" : 6,
                        "min_doc_count" : 1,
                        "shard_min_doc_count" : 1,
                        "show_term_doc_count_error" : false,
                        "order" : [ {
                          "_count" : "desc"
                        }, {
                          "_key" : "asc"
                        } ]
                      }
                    },
                    "age_avg" : {
                      "avg" : {
                        "field" : "age"
                      }
                    }
                  }
                },
                "vv" : {
                  "terms" : {
                    "size" : 1,
                    "shard_size" : 2,
                    "min_doc_count" : 1,
                    "shard_min_doc_count" : 1,
                    "show_term_doc_count_error" : false,
                    "order" : [ {
                      "_count" : "desc"
                    }, {
                      "_key" : "asc"
                    } ]
                  }
                }
              }
            }
          }
        }
      }
    }
  }
}
Stargazers over time
Ähnliche Projekte entdecken
Asabeneh/30-Days-Of-Python
Die Programmier-Challenge 30 Days of Python ist eine Schritt-für-Schritt-Anleitung, um die Programmiersprache Python in 30 Tagen zu lernen. Diese Challenge kann mehr als 100 Tage dauern. Gehe in deinem eigenen Tempo vor. Diese Videos können ebenfalls helfen: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,730 Sternegrafana/grafana
Offene und kombinierbare Plattform für Observability und Datenvisualisierung. Visualisiert Metriken, Logs und Traces aus mehreren Quellen wie Prometheus, Loki, Elasticsearch, InfluxDB, Postgres und vielen weiteren.
77,898 Sterneredis/redis
Für Entwickler, die echtzeitfähige, datengesteuerte Anwendungen erstellen, ist Redis der bevorzugte, schnellste und funktionsreichste Cache, Datenstrukturserver und die entsprechende Abfrageengine für Dokumente und Vektoren.
77,491 Sterneapache/superset
Apache Superset ist eine Plattform für Datenvisualisierung und Datenexploration.
75,522 Sterne