
datajoint/datajoint-python
datajoint/datajoint-python has 198 GitHub stars and 103 forks. GitHot measured 0 stars in 24 hours, +1 in 7 days, and +1 in 15 days. Last checked 2026-11-11 11:59 UTC. Last push 2026-11-05.
So werden diese Zahlen gemessen
Relational Workflows: where database schemas define executable data pipelines.
Gemessener Sternzuwachs
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- +1
- in 1 month
- Verlauf wird gesammelt
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
README.md
OriginalDataJoint Library for Python
The DataJoint Library is a framework for scientific data pipelines based on the Relational Workflow Model — a paradigm where your database schema is an executable specification of your workflow.
- Tables represent workflow steps — Each table is a step in your pipeline
- Foreign keys encode dependencies — Parent tables must be populated before child tables
- Computations are declarative — Define what to compute; DataJoint handles when
- Results are immutable — Full lineage and reproducibility
Documentation: https://docs.datajoint.com
📘 Upgrading from legacy DataJoint (pre-2.0)? See the Migration Guide for a step-by-step upgrade path.
| PyPI |

|
Conda |

|
Tests |

|
| License |

|
Citation |

|
Coverage |

|
Installation
pip install datajoint
or with Conda:
conda install -c conda-forge datajoint
Example Pipeline
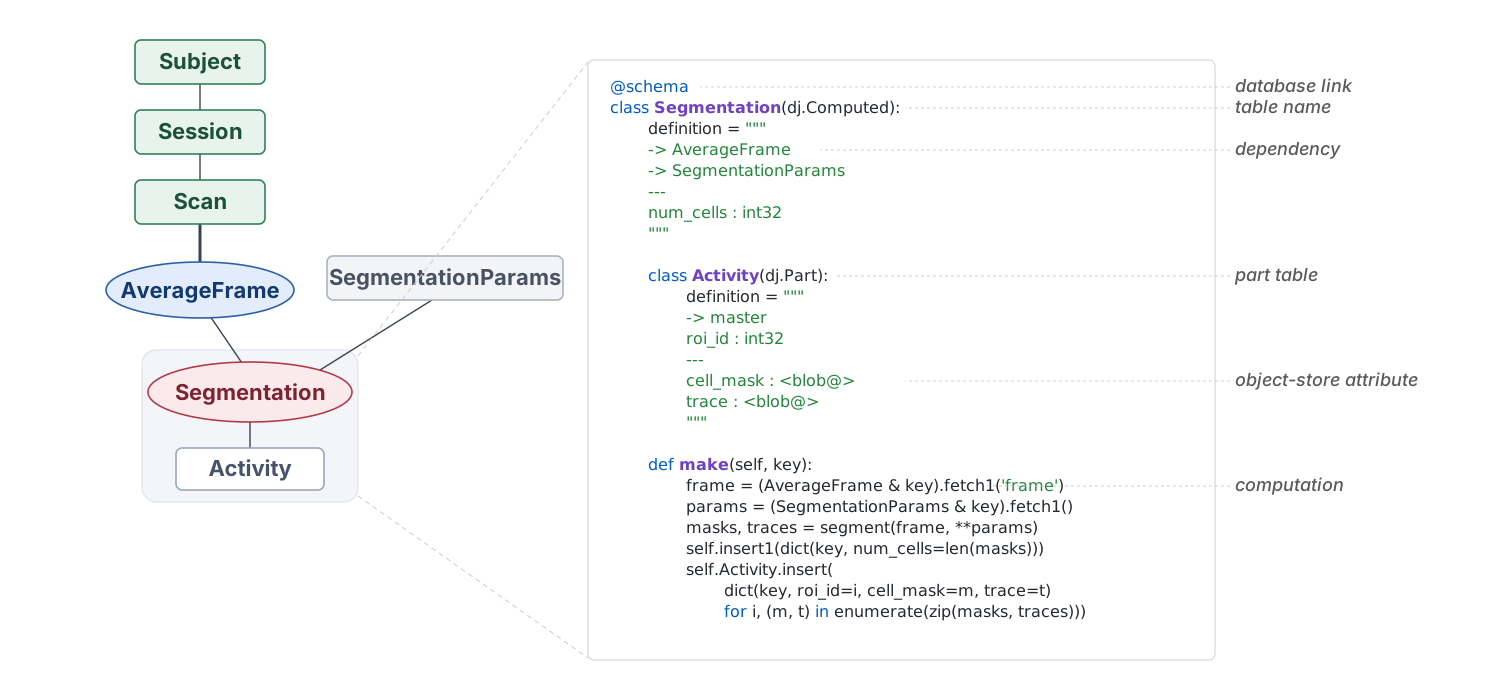
Cite DataJoint: Yatsenko et al., 2026 — RRID: SCR_014543
Resources
- Documentation — Complete guides and reference
- Tutorials — Learn by example
- How-To Guides — Task-oriented guides
- API Reference — Complete API documentation
- Migration Guide — Upgrade from legacy versions
- DataJoint Elements — Example pipelines for neuroscience
- GitHub Discussions — Community support
Contributing
See CONTRIBUTING.md for development setup and guidelines.
Ähnliche Projekte entdecken
Asabeneh/30-Days-Of-Python
Die Programmier-Challenge 30 Days of Python ist eine Schritt-für-Schritt-Anleitung, um die Programmiersprache Python in 30 Tagen zu lernen. Diese Challenge kann mehr als 100 Tage dauern. Gehe in deinem eigenen Tempo vor. Diese Videos können ebenfalls helfen: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 Sternegrafana/grafana
Offene und kombinierbare Plattform für Observability und Datenvisualisierung. Visualisiert Metriken, Logs und Traces aus mehreren Quellen wie Prometheus, Loki, Elasticsearch, InfluxDB, Postgres und vielen weiteren.
77,830 Sterneredis/redis
Für Entwickler, die echtzeitfähige, datengesteuerte Anwendungen erstellen, ist Redis der bevorzugte, schnellste und funktionsreichste Cache, Datenstrukturserver und die entsprechende Abfrageengine für Dokumente und Vektoren.
77,395 Sterneapache/superset
Apache Superset ist eine Plattform für Datenvisualisierung und Datenexploration.
75,473 Sterne