
ali-faraz-py/deepfake-detector
ali-faraz-py/deepfake-detector has 34 GitHub stars and 1 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-12 12:38 UTC. Last push 2026-08-17.
So werden diese Zahlen gemessen
AI-powered deepfake detector that classifies uploaded face images and videos as Real or Fake with confidence scores. Full-stack app built with PyTorch (EfficientNet-B0), FastAPI, and Next.js — trained on 100k+ images and deployed with Vercel + Render.
Gemessener Sternzuwachs
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Verlauf wird gesammelt
- in 1 month
- Verlauf wird gesammelt
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
README.md
Original🔍 Deepfake Detector
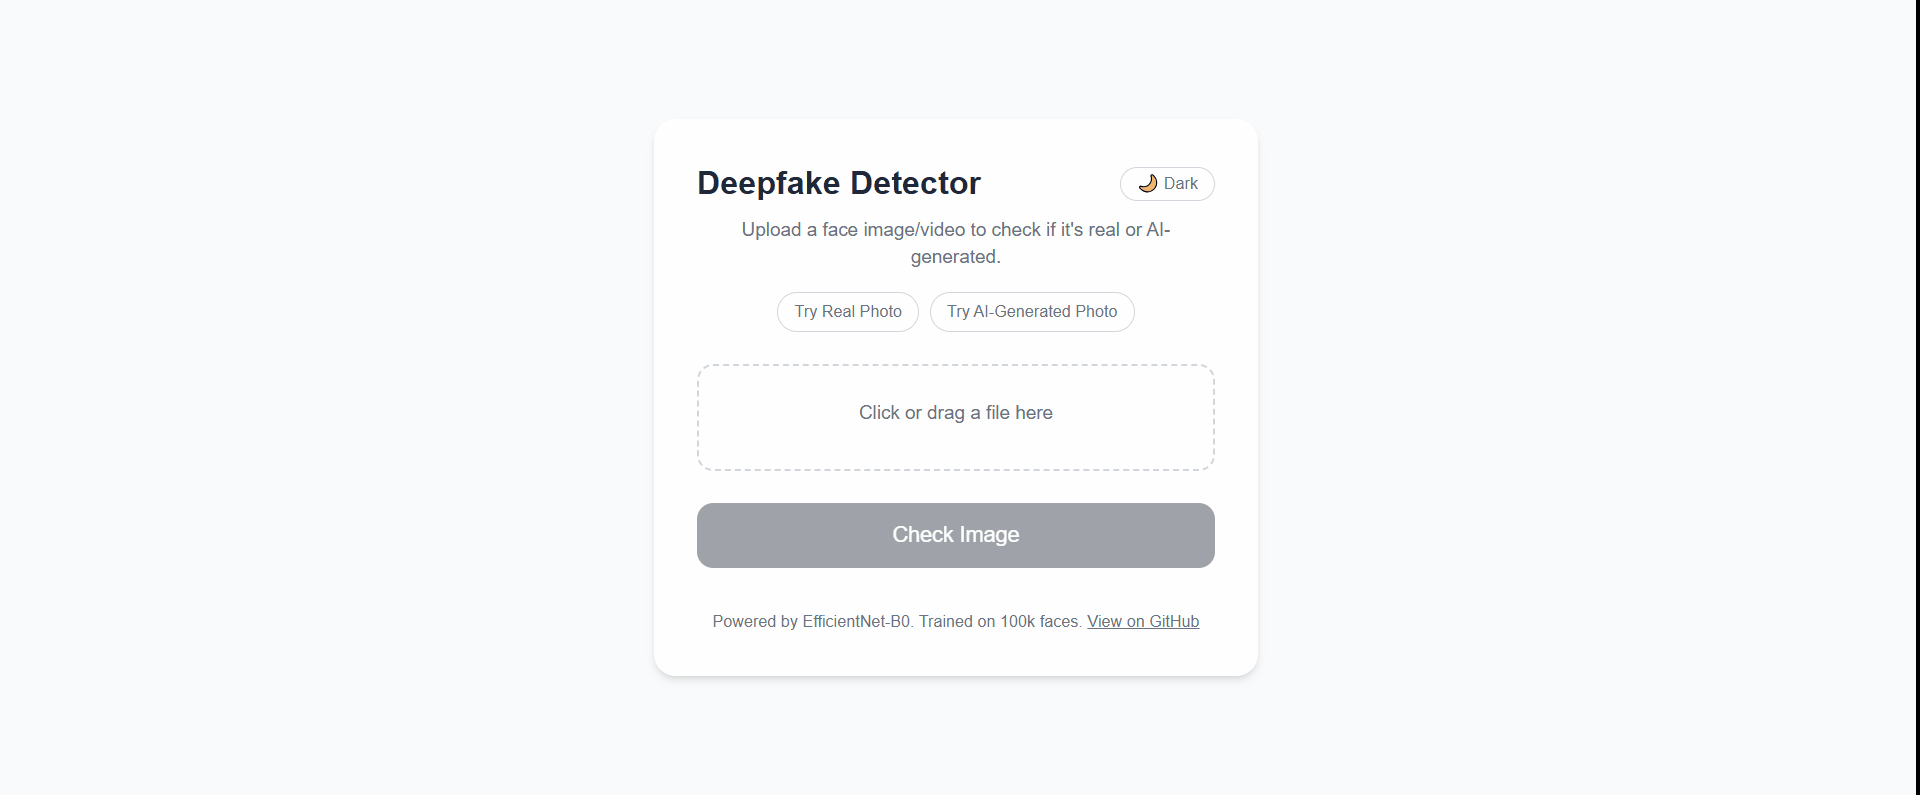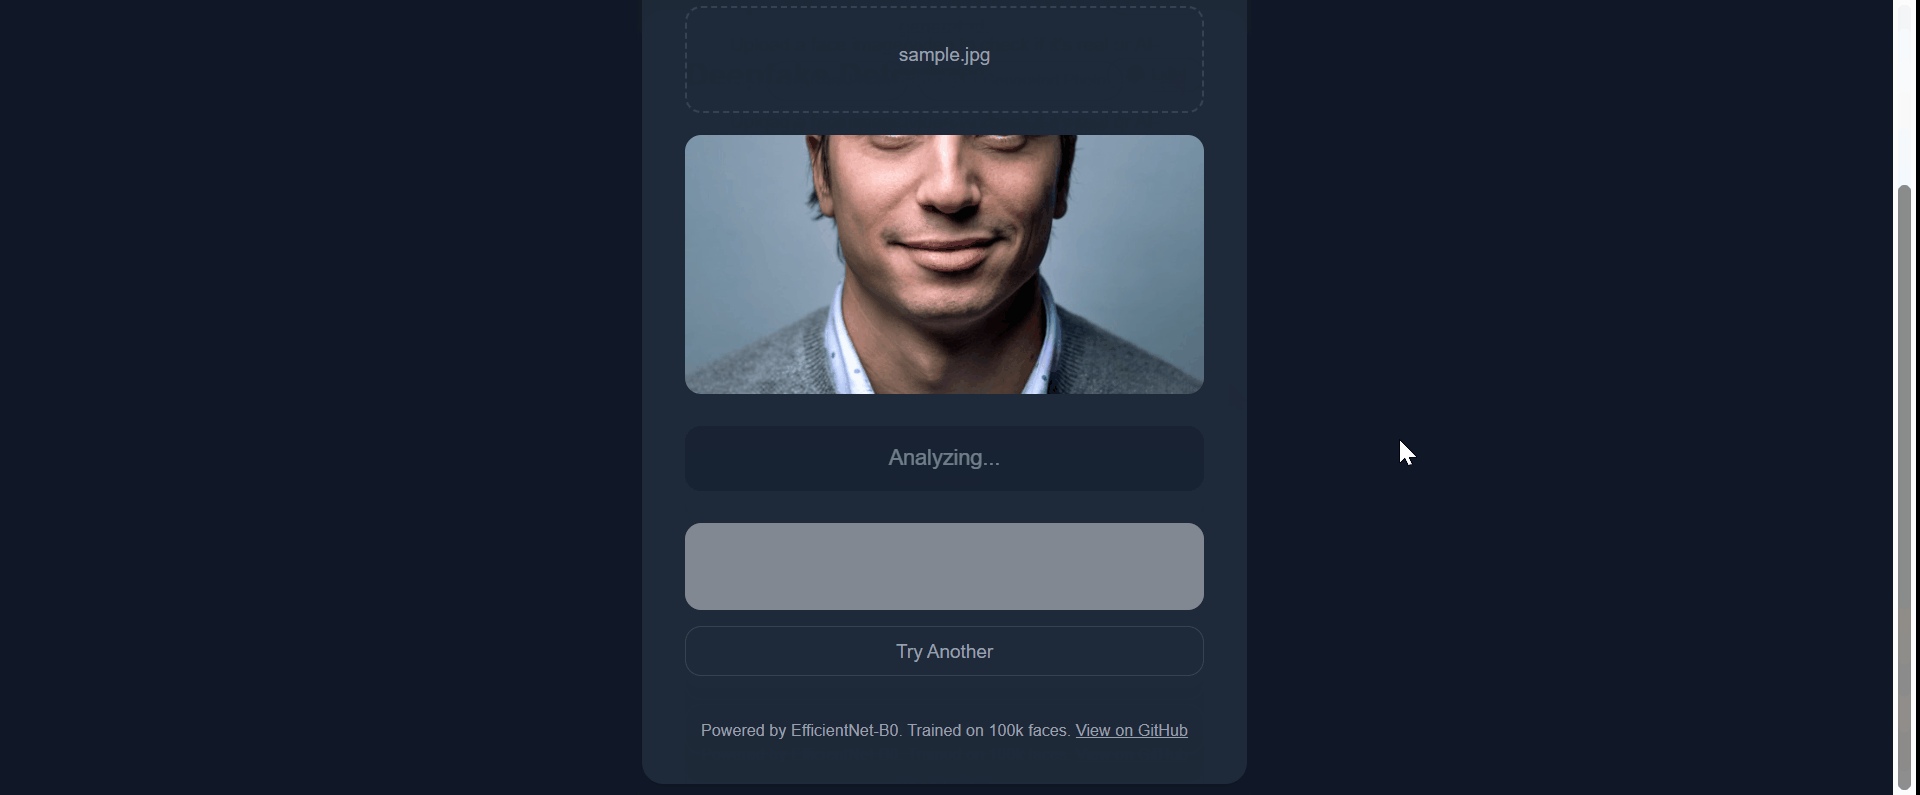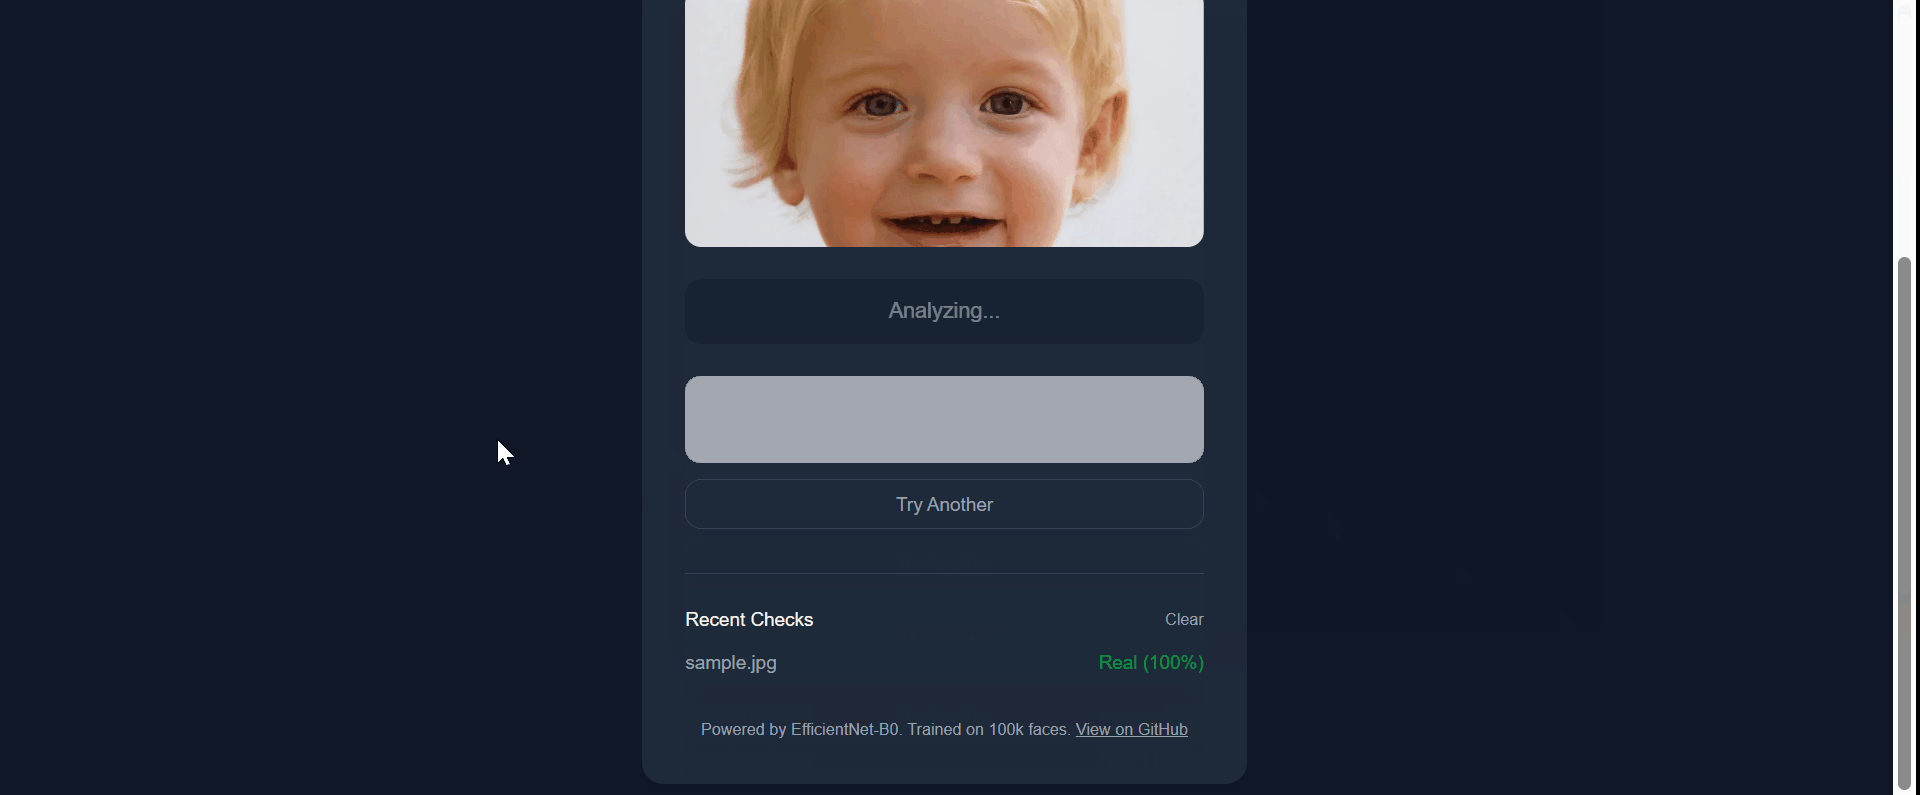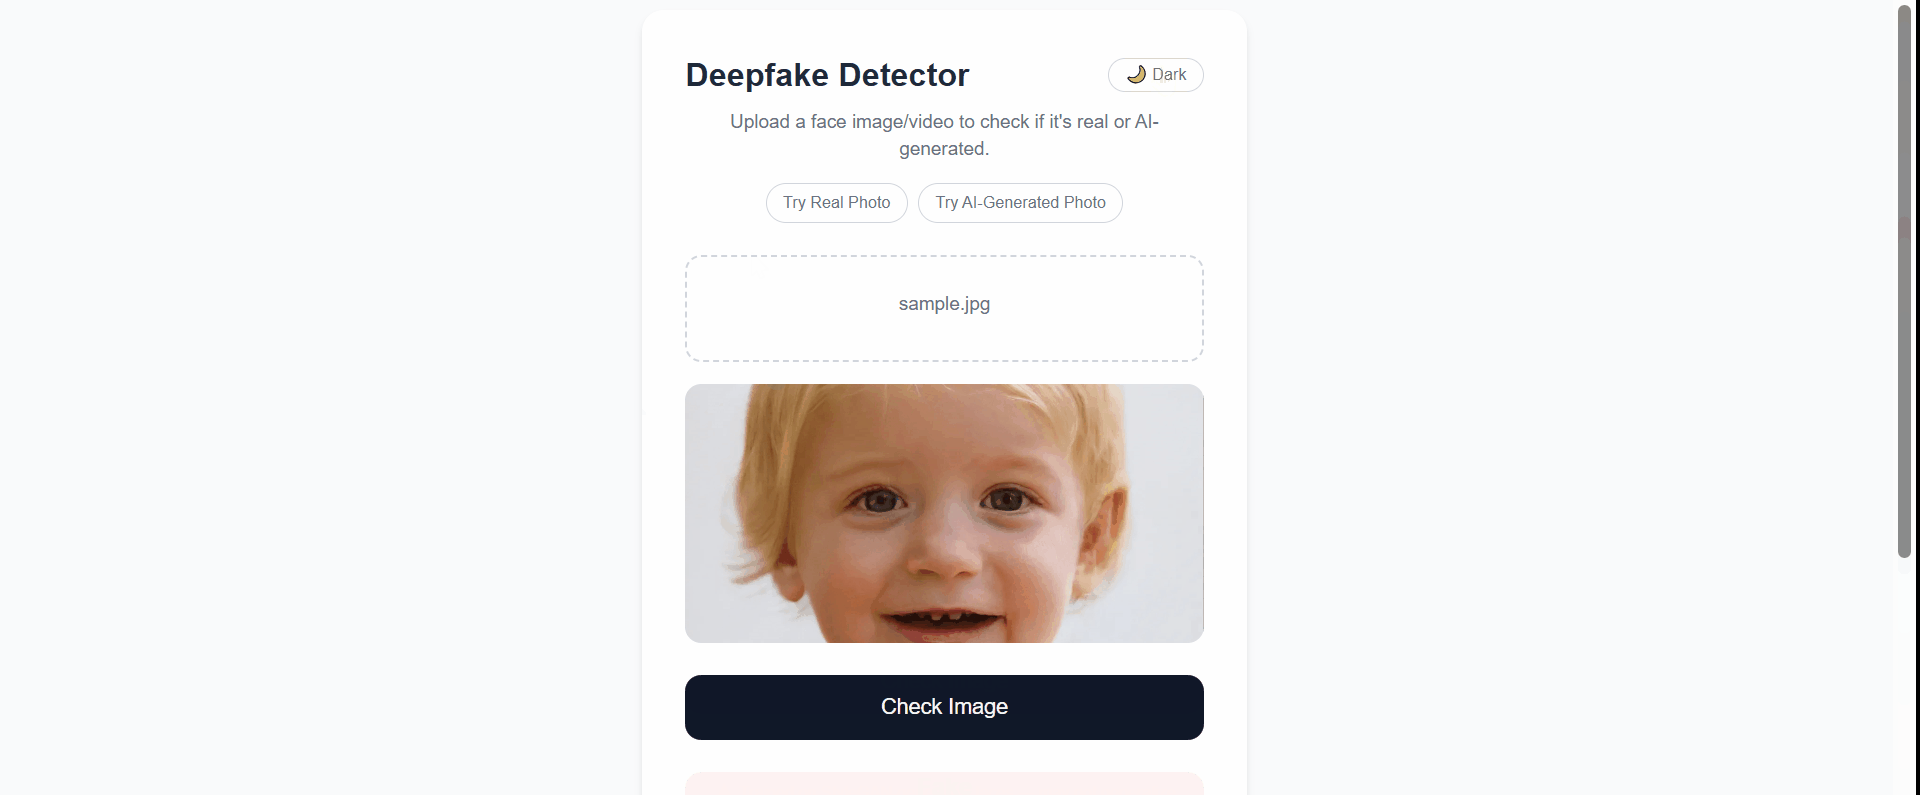
An AI-powered web app that analyzes uploaded face images and videos to classify them as Real or Deepfake, with a confidence score. Built as a full-stack project covering model training, backend API development, and frontend deployment.
Live app: deepfake-detector-olive.vercel.app Backend API: deepfake-detector-api-amqf.onrender.com
Demo
What it does
- Upload a face image or video
- The model classifies it as Real or Fake
- Returns a confidence percentage, shown with a visual confidence bar
- For videos, samples multiple frames and averages predictions across them
- Drag-and-drop upload, live preview, and a history of recent checks
- Try-it-now sample buttons (one real photo, one AI-generated photo) for visitors without their own test files
- File type and size validation, with toast notifications for errors
- Dark mode toggle
- A visible disclaimer noting the model's known generalization limits (see below)
Tech Stack
Frontend
- Next.js (React)
- Tailwind CSS
- Deployed on Vercel
Backend
- FastAPI (Python)
- PyTorch + EfficientNet-B0
- OpenCV (video frame extraction)
- Deployed on Render
Model Training
- Trained on Google Colab (free GPU)
- Dataset: 140k Real and Fake Faces (Kaggle, by xhlulu)
- 100,000 training images / 20,000 validation images
- 3 epochs, ~99.7% training accuracy
How it works
- The frontend sends the uploaded file to the FastAPI backend
- If it's an image, it's resized, normalized, and passed through EfficientNet-B0
- If it's a video, OpenCV extracts ~5-10 sampled frames, each is classified individually, and the results are averaged into one final prediction
- The model returns a label (
Real/Fake) and a confidence score as JSON - The frontend displays the result with a color-coded card
Known Limitations
- Generalization: The model was trained on StyleGAN-generated faces (the dataset's specific fake-image style). It performs very well (~99.7%) on that distribution, but may not generalize reliably to images generated by other AI tools (e.g. diffusion models like Midjourney or DALL·E), since those leave different visual artifacts than the ones the model learned to detect. This is a well-documented, open challenge in deepfake detection research generally — not unique to this project.
- Cold starts: The backend is hosted on Render's free tier, which spins down after inactivity. The first request after idle time may take 30-60 seconds to respond.
- Video processing: Limited to a small number of sampled frames (not every frame) to stay within free-tier memory limits.
Running Locally
Backend
cd backend
pip install -r requirements.txt
uvicorn app.main:app --reload
Frontend
cd frontend
npm install
npm run dev
Create a .env.local file in frontend/ with:
NEXT_PUBLIC_API_URL=http://127.0.0.1:8000
Project Structure
deepfake-detector/
├── backend/
│   ├── app/
│   │   ├── main.py           # FastAPI routes
│   │   ├── model.py          # Model loading + inference
│   │   └── preprocessing.py  # Video frame extraction
│   ├── models/
│   │   └── deepfake_model.pth
│   └── requirements.txt
└── frontend/
    └── src/app/
        └── page.js           # Upload UI + result display
Author
Built by Ali Faraz as a portfolio project exploring the intersection of computer vision, cybersecurity, and full-stack deployment.
Ähnliche Projekte entdecken
tensorflow/tensorflow
Ein Open-Source-Framework für maschinelles Lernen für alle
201,505 Sternehuggingface/transformers
🤗 Transformers: das Framework zur Modelldefinition für State-of-the-Art-Modelle des maschinellen Lernens in Text, Vision, Audio und multimodal, für Inferenz und Training.
168,815 SterneAUTOMATIC1111/stable-diffusion-webui
Web-UI für Stable Diffusion
165,300 SterneComfy-Org/ComfyUI
Die leistungsstärkste und modularste GUI, API und das Backend für Diffusionsmodelle mit einer Oberfläche aus Graphen und Knoten. Die schnellste lokale Inferenz-Engine der Welt.
146,472 Sterne