
alanarazi7/TabSTAR
alanarazi7/TabSTAR has 93 GitHub stars and 16 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and 0 in 15 days. Last checked 2026-11-21 22:06 UTC. Last push 2026-10-16.
Gemessener Sternzuwachs
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 0
- in 1 month
- Verlauf wird gesammelt
Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.
Über uns
TabSTAR: A Tabular Foundation Model for Tabular Data with Text Fields
Maschinelles LernenREADME.md
OriginalTabSTAR: A Tabular Foundation Model for Tabular Data with Text Fields


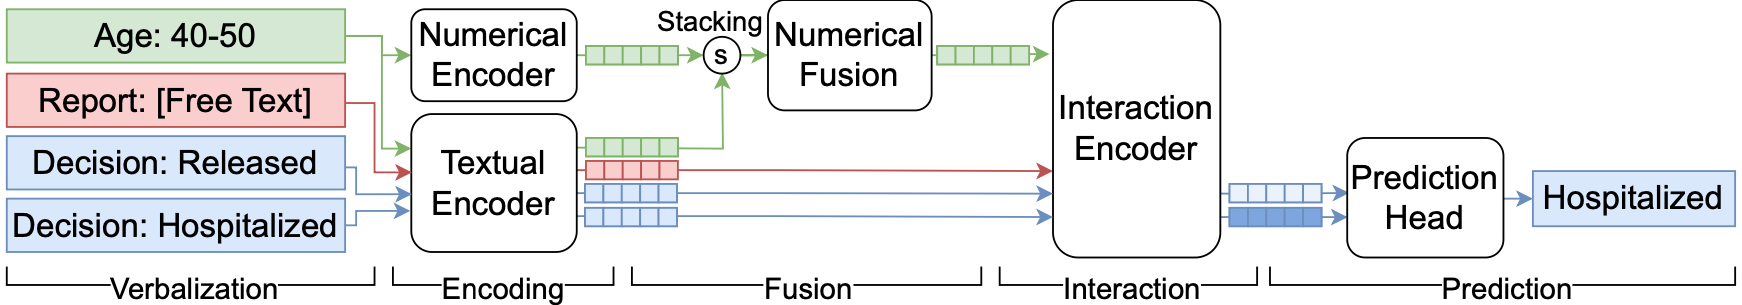
Welcome to the TabSTAR repository! 👋
You can either use TabSTAR as a package for your own tabular data tasks, or explore the full repository for research purposes, including customized pretraining and replication of paper results.
🚀 TabSTAR v1.1 is out
We released TabSTAR v1.1, a new generation of pretrained TabSTAR models. It ships alongside the original models, in its own module, so existing code keeps working unchanged:
| import | estimators | |
|---|---|---|
| TabSTAR | tabstar.tabstar_model |
TabSTARClassifier, TabSTARRegressor |
| TabSTAR v1.1 | tabstar.tabstarv1p1_model |
TabSTARv1p1Classifier, TabSTARv1p1Regressor |
See TabSTAR v1.1 below for usage. The v1.1 pretraining code lives in tabstarv1p1_pretrain/; a detailed writeup of what changed will follow.
📚 Resources
- Paper: TabSTAR: A Tabular Foundation Model for Tabular Data with Text Fields
- Project Website: TabSTAR
Package Mode
Use this mode if you want to fit a pretrained TabSTAR model to your own dataset.
Installation
pip install tabstar
Inference Example
Using TabSTAR is as simple as this:
from importlib.resources import files
import pandas as pd
from sklearn.model_selection import train_test_split

from tabstar.tabstar_model import TabSTARClassifier

csv_path = files("tabstar").joinpath("resources", "imdb.csv")
x = pd.read_csv(csv_path)
y = x.pop('Genre_is_Drama')
x_train, x_test, y_train, y_test = train_test_split(x, y, test_size=0.1)
tabstar = TabSTARClassifier()
tabstar.fit(x_train, y_train)
# tabstar.save("my_model_path.pkl")
# tabstar = TabSTARClassifier.load("my_model_path.pkl")
# y_pred = tabstar.predict(x_test)
metric = tabstar.score(X=x_test, y=y_test)
print(f"AUC: {metric:.4f}")
Below is a template you can use to quickly get started with TabSTAR with your own data.
from pandas import DataFrame, Series
from sklearn.model_selection import train_test_split

from tabstar.tabstar_model import TabSTARClassifier, TabSTARRegressor

# --- USER-PROVIDED INPUTS ---
x_train = None  # TODO: load your feature DataFrame here
y_train = None  # TODO: load your target Series here
is_cls = None   # TODO: True for classification, False for regression
x_test = None   # TODO Optional: load your test feature DataFrame (or leave as None)
y_test = None   # TODO Optional: load your test target Series (or leave as None)
# -----------------------------

# Sanity checks
assert isinstance(x_train, DataFrame), "x should be a pandas DataFrame"
assert isinstance(y_train, Series), "y should be a pandas Series"
assert isinstance(is_cls, bool), "is_cls should be a boolean indicating classification or regression"

if x_test is None:
    assert y_test is None, "If x_test is None, y_test must also be None"
    x_train, x_test, y_train, y_test = train_test_split(x_train, y_train, test_size=0.1)

assert isinstance(x_test, DataFrame), "x_test should be a pandas DataFrame"
assert isinstance(y_test, Series), "y_test should be a pandas Series"

tabstar_cls = TabSTARClassifier if is_cls else TabSTARRegressor
tabstar = tabstar_cls()
tabstar.fit(x_train, y_train)
# tabstar.save("my_model_path.pkl")
# tabstar = TabSTARClassifier.load("my_model_path.pkl")
y_pred = tabstar.predict(x_test)
# metric = tabstar.score(X=x_test, y=y_test)
TabSTAR v1.1
The v1.1 models are a drop-in alternative to the examples above. Swap the import and the class name:
from tabstar.tabstarv1p1_model import TabSTARv1p1Classifier, TabSTARv1p1Regressor

tabstar = TabSTARv1p1Classifier()
tabstar.fit(x_train, y_train)
y_pred = tabstar.predict(x_test)
metric = tabstar.score(X=x_test, y=y_test)
fit, predict, predict_proba, score, save and load behave as they do for the original models.
Model cards: classification, regression.
Research Mode
Use this section when you want to pretrain, finetune, or evaluate TabSTAR on benchmarks. It assumes you are actively working on model development, experimenting with different datasets, or comparing against other methods.
Installation
After cloning the repo, run:
source init.sh
This will install all necessary dependencies, set up your environment, and download any example data needed to get started.
Benchmark Evaluation
If you want to evaluate TabSTAR on public datasets belonging to the paper's benchmark:
python tabstar_paper/do_benchmark.py --model=tabstar --dataset_id=<DATASET_ID>
This script can over the 400 datasets in the paper, both for TabSTAR and other baselines presented in the paper.
The --dataset_id argument should be selected as the value of datasets appearing at tabstar/datasets/all_datasets.py.
Pretraining
To pretrain TabSTAR on a specified number of datasets:
python tabstar_paper/do_pretrain.py --n_datasets=256
--n_datasets determines how many datasets to use for pretraining. You can reduce this number for quick debugging, but note this will harm downstream performance.
For the TabSTAR v1.1 pretraining pipeline (T4 data curation, pretraining, per-epoch finetunability Elo), see tabstarv1p1_pretrain/.
Finetuning
Once pretraining finishes, note the printed <PRETRAINED_EXP> identifier. Then run:
python tabstar_paper/do_finetune.py --pretrain_exp=<PRETRAINED_EXP> --dataset_id=46655
--dataset_id is an ID for the downstream task you want to evaluate yourself on. Only the 400 datasets in the paper are supported.
Citation
If you use TabSTAR in your research, please cite:
@inproceedings{
arazi2025tabstar,
title={Tab{STAR}: A Tabular Foundation Model for Tabular Data with Text Fields},
author={Alan Arazi and Eilam Shapira and Roi Reichart},
booktitle={The Thirty-ninth Annual Conference on Neural Information Processing Systems},
year={2025},
url={https://openreview.net/forum?id=FrXHdcTEzE}
}
License
MIT
❤️ Contributors
Ähnliche Projekte entdecken
Wird geladen…