Skip to content
Projekte

KaiWU5/Awesome-AI4AI has 220 GitHub stars and 7 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-12 22:39 UTC. Last push 2026-11-04.

So werden diese Zahlen gemessen

Updated weekly — until humanity achieves AI4AI. 965 curated papers across Benchmarks, Harness Design, and Model Design — from long-horizon agents to recursive self-improvement. Citation rankings, GitHub stars, and source-verified weekly news.

Gemessener Sternzuwachs

in 24h
+2
in 7 days
Verlauf wird gesammelt
in 15 days
Verlauf wird gesammelt
in 1 month
Verlauf wird gesammelt

Nettoänderungen in überlappenden Zeiträumen, keine Tagessummen. Fehlende Messwerte bleiben leer. Sterne zeigen Interesse, nicht Qualität.

README.md

Original

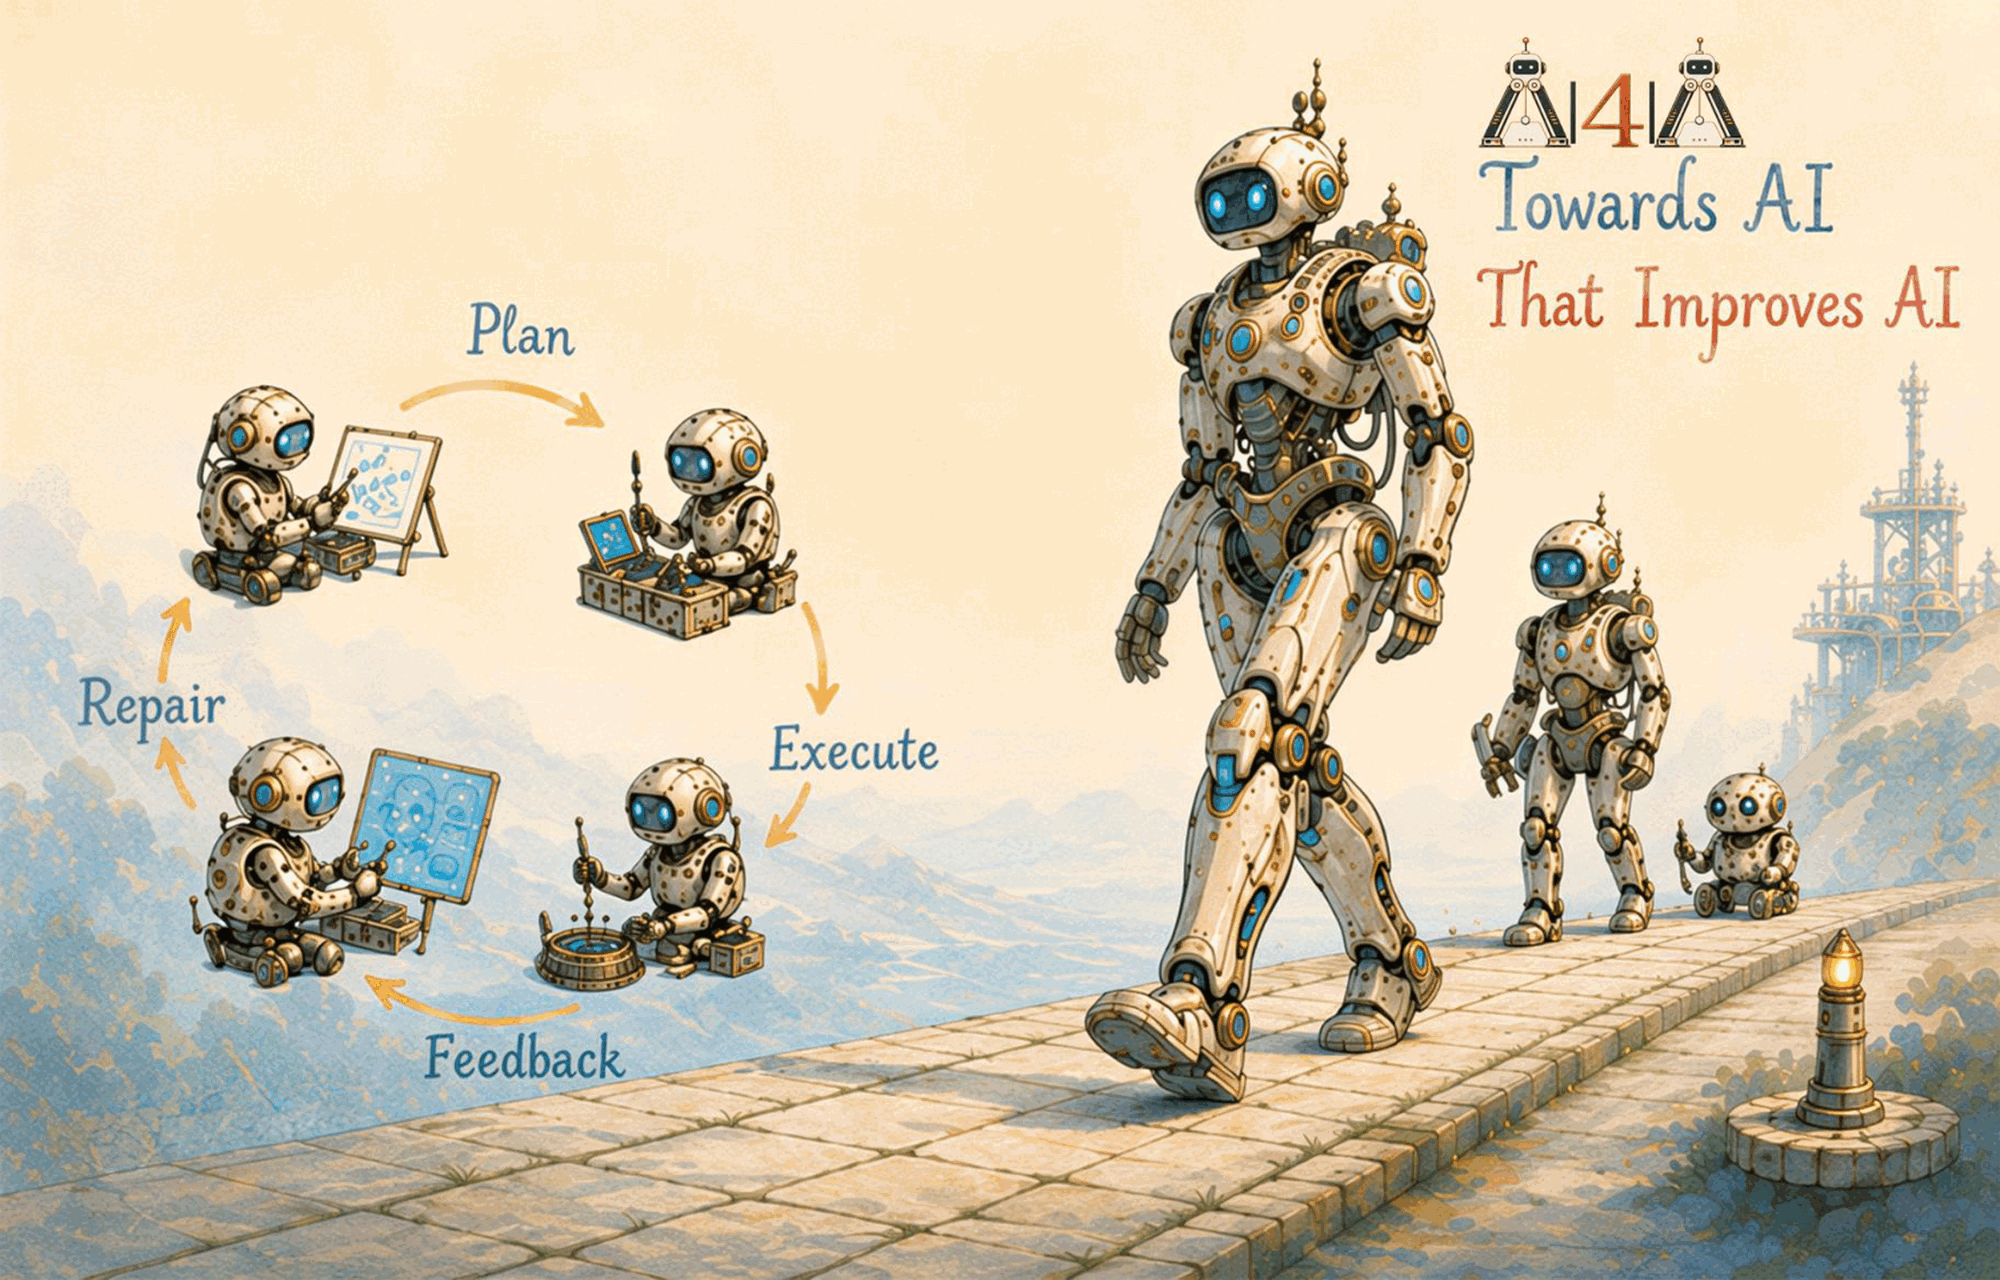
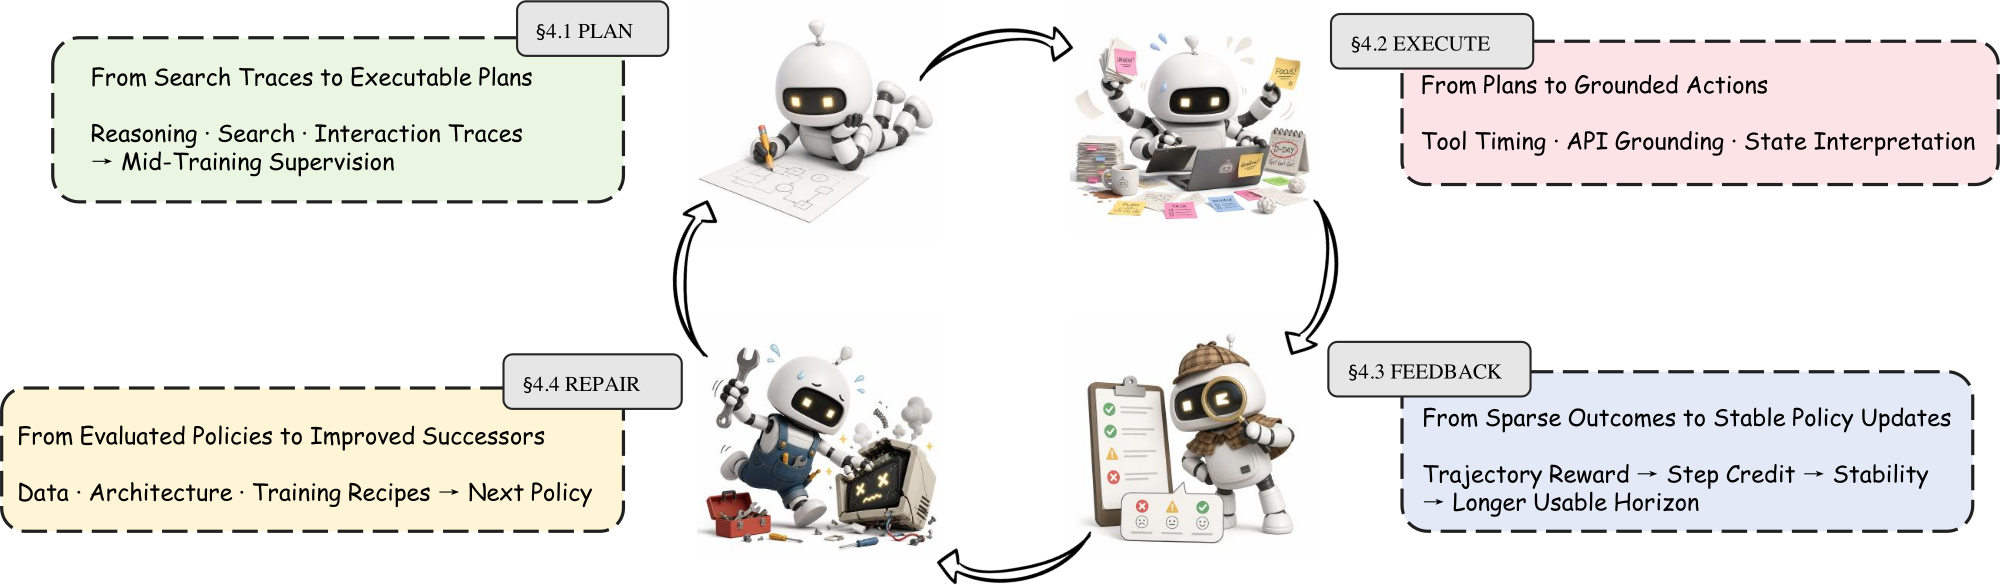
Towards AI that improves AI — the plan, execute, feedback, repair loop

🚀 Awesome AI4AI

🔄 Updated weekly — until humanity achieves AI4AI.

Follow the journey: Star ⭐ · Watch 👀 for weekly updates · Read this week's picks →

AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement
Definitions, Reliable Horizons, and Open Problems · 23 authors · 7 institutions

Top AI-for-AI papers, releases, and blogs — curated every week. Stay tuned 🔥

Living catalog: 965 papers · 449 benchmarks · 596 harness studies · 213 model studies
Collections overlap. The original survey covers 223 papers.

Paper, nice layout Paper on Preprints.org Project Site RSIHub Harness Blog DOI


Why This Repo

🔄 Refreshed rankings
Citations, GitHub stars, and rankings refresh with maintainer updates.
🗞️ Weekly update
New papers added to the catalog, plus source-verified papers and releases selected every week.
🧭 Survey-grounded map
From long-horizon agents to recursive self-improvement.

Star ⭐ to save the map · Watch 👀 for weekly updates · Share 🔁 with your lab

What's New

  • 🤝 2026-10-26 — Community contributions integrated. Added ReCreate, Meta-Team, Agon, EvoRepair, and Harness Engineering for Language Agents to Harness Design, and PerspectiveGap to Benchmarks. Related Lists now links to three complementary community resources.

  • 📚 2026-11-03 — 527 papers added. Expanded Benchmarks, Harness Design, and Model Design with verified new and previously missed papers; rebuilt the full catalog and both ranking families.

  • 📄 2026-08-30 — Companion survey now online. Read AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement—Definitions, Reliable Horizons, and Open Problems.

  • 🔄 Maintainer refresh. Citations, GitHub stars, and recent-paper/yearly rankings are rebuilt from the catalog.

  • 🚀 2026-11-03 — Latest weekly edition published. Read the source-verified news digest below.

🗂️ Explore the full collection

📅 Weekly News · Top 10

Updated 2026-11-03 · Weekly news picks, refreshed every Monday alongside citation rankings.

How we select: The top stories from the trailing 30 days, scored on publisher authority, discussion volume, whether a concrete verifiable result is reported, whether it changes what agent builders do now, whether an artifact was released, and expected durability. Only primary sources are cited, and performance claims remain attributed to their publishers.

Date · Type News Why it matters
2026‑11‑02
Paper
SelfImprove-Bench: Evaluating Generalization in Self-Improving Agents
Xu, Yang et al. · arXiv
The authors introduce a reproducible RSI benchmark with a G0–G4 generalization ladder spanning exploration, planning and reasoning, and report that evolution gains do not consistently transfer across levels.
2026‑10‑30
Paper
Exo: An Architecture for Self-Improving Systems at Runtime
Krentsel et al. · arXiv
The authors let an agent revise its harness during ongoing work behind a protected activation layer. Against a fixed-policy control, they report 35–61% lower held-out model cost on AppWorld and SREGym with comparable correctness.
2026‑10‑29
Paper
MoLRSI: A Recursive Self-Improving AI agent for Molecular Discovery
Zhang et al. · arXiv
The authors combine workflow and model-architecture search with persistent cross-task memory. They report a 15.9% experimental antibiotic hit rate versus 8.7% for a prior expert-led workflow on the same training data and screening library.
2026‑10‑28
Model release
Gemini 4 Carbon: our next frontier model
Google DeepMind
Google announces Carbon for long-horizon engineering and cybersecurity, reporting 88.2% on SEC-bench Pro. Access begins with pre-release testing and selected cyber defenders through Fairwind; general developer and consumer access is still forthcoming.
2026‑10‑26
Model release
Introducing GPT-6.1 Terra
OpenAI
OpenAI releases a model for visual reasoning and computer use in Work, Codex and the API. It reports a 15-point Agents’ Last Exam gain over GPT-5.6 Terra at medium effort at about one-third the cost, and 50.3% on Terminal-Bench 4.0 at max effort.
2026‑10‑26
Paper
Skill∞: Recursive Self-Improvement for Agent Skill Optimization
Tao et al. · arXiv
The authors make the skill optimizer itself a reusable, revisable meta-skill. They report 60.7% on 83 SkillsBench tasks, compared with 56.4% for human-curated skills and 54.5% for SkillEvolver.
2026‑10‑23
Model release
Kimi K3.1 Pro series is live
Moonshot AI
Moonshot rolls out Kimi K3.1 Pro and its Highspeed variant in Kimi Code, with a 1M-token context window and improved long-horizon agent capabilities. Its technical blog reports 65.7% on Terminal-Bench 4.0 and says full weights are planned by November 4; this edition treats the product launch and future weight release separately.
2026‑10‑18
Open-weight release
Introducing Flint
Recursive
Recursive releases a 40B-total / 2.5B-active MoE for local agentic coding and says its Eureka Machine helped develop the architecture, data, training, quantization and inference stack. The official post reports over 125 tokens/s on an M4 Pro at short contexts.
2026‑10‑16
Open-weight release
Beam is now available
Reflection
Reflection releases Beam under Apache 2.0 with 501B total and 23B active parameters, multiple weight precisions, a speculative drafter, and the Mirror CLI harness. The release makes its coding and long-horizon agent stack available for deployment and customization.
2026‑10‑09
Paper
Harness²: Recursive Agent Harnessing for an Open World
Google Research
Google Research introduces two connected loops that refine the current task harness and retain evidence-supported lessons for future tasks, with model weights fixed. The authors report gains across three professional benchmarks; the Apache-2.0 implementation supports OpenCode and Codex, parallel and sequential recursion, and reproducible benchmark runs. Official code.

Want next week's news? Watch the repository. Citation counts, rankings, and the weekly news picks are published with maintainer updates. Browse past editions →

📈 Live Rankings

Citation counts are current through 2026-10-17 from Semantic Scholar and OpenAlex. Rankings are discovery aids, not quality scores; audit evidence remains independent of popularity. GitHub stars are snapshots from 2026-11-03. For papers indexed as multiple versions, retain the largest title-verified count reported by the configured sources. All yearly rankings use first public appearance year; a later venue year never moves a paper into a newer cohort.

Latest metric check: 2026-11-03. Title-verified citations for 773/981 catalog records; 6 previously cited records retain older counts and 202 records remain without a verified index count. GitHub stars refreshed for 317 records across 312 repositories. The complete citation as-of date above advances only after unresolved counts are verified.

Top Ranking Papers by Average Monthly Citations

Paper Venue Date Citations Avg. cites/month Code
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces arXiv 2026-01 612 68.0 GitHub · ★ 2,614
AlphaEvolve: A coding agent for scientific and algorithmic discovery arXiv 2025-06 1051 65.7 —
Towards End-to-End Automation of AI Research Nature 2026 2026-03 317 45.3 GitHub · ★ 7,433
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory European Conference on Artificial Intelligence (ECAI) 2025-04 793 44.1 GitHub · ★ 68,321
Meta-Harness: End-to-End Optimization of Model Harnesses arXiv 2026-03 305 43.6 GitHub · ★ 1,248
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models Proceedings of the 42nd International Conference on Machine Learning 2025 634 39.6 GitHub · ★ 13,061
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models arXiv 2025-10 453 37.8 GitHub · ★ 1,423
Kimi K3: Open Frontier Intelligence arXiv 2026-07 103 34.3 GitHub · ★ 9,041
Group-in-Group Policy Optimization for LLM Agent Training Advances in Neural Information Processing Systems 2025-05 548 32.2 GitHub · ★ 2,422
LLMs Get Lost In Multi-Turn Conversation International Conference on Learning Representations 2025-05 527 31.0 GitHub · ★ 302

🏆 Most-Cited Papers by Year

Top 12 of 2026 by citations
Paper Date Citations Code
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
arXiv
2026-01 612 GitHub · ★ 2,614
Towards End-to-End Automation of AI Research
Nature 2026
2026-03 317 GitHub · ★ 7,433
Meta-Harness: End-to-End Optimization of Model Harnesses
arXiv
2026-03 305 GitHub · ★ 1,248
Kimi K3: Open Frontier Intelligence
arXiv
2026-07 103 GitHub · ★ 9,041
Self-Harness: Harnesses That Improve Themselves
arXiv
2026-06 100 GitHub · ★ 137
Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
arXiv preprint arXiv:2604.08224
2026-04 73 —
Hindsight Credit Assignment for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.08754
2026-03 66 —
DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks
arXiv preprint arXiv:2607.07946
2026-07 61 GitHub · ★ 1,884
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-03 60 GitHub · ★ 611
Natural-Language Agent Harnesses
arXiv
2026-03 58 —
ProgramBench: Can Language Models Rebuild Programs From Scratch?
arXiv
2026-05 56 GitHub · ★ 980
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
arXiv preprint arXiv:2601.16746
2026-01 56 GitHub · ★ 319
Top 12 of 2025 by citations
Paper Date Citations Code
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-02 1222 GitHub · ★ 1,010
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06 1051 —
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04 793 GitHub · ★ 68,321
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03 756 GitHub · ★ 433
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025 634 GitHub · ★ 13,061
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05 548 GitHub · ★ 2,422
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05 527 GitHub · ★ 302
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10 453 GitHub · ★ 1,423
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05 394 GitHub · ★ 2,479
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04 342 GitHub · ★ 1,333
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
arXiv
2025-09 308 GitHub · ★ 557
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12 297 —
Top 12 of 2024 by citations
Paper Date Citations Code
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-06 1502 GitHub · ★ 1,488
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-04 1356 GitHub · ★ 3,250
Self-rewarding language models
arXiv
2024-01 774 —
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07 550 GitHub · ★ 2,135
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02 511 GitHub · ★ 567
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10 502 GitHub · ★ 1,789
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01 494 GitHub · ★ 1,128
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05 486 GitHub · ★ 995
Automated design of agentic systems
ICLR 2025
2024-08 444 GitHub · ★ 1,659
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07 439 GitHub · ★ 546
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05 410 GitHub · ★ 4,096
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03 407 GitHub · ★ 279
Top 12 of 2023 by citations
Paper Date Citations Code
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-02 6192 —
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-03 6117 GitHub · ★ 3,394
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-04 6015 GitHub · ★ 22,332
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-05 5152 GitHub · ★ 6,087
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-03 5147 GitHub · ★ 847
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-10 4403 GitHub · ★ 6,138
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-05 2647 GitHub · ★ 7,310
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-07 2466 GitHub · ★ 5,764
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-07 2300 GitHub · ★ 1,640
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-05 1767 GitHub · ★ 13,061
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-10 1624 GitHub · ★ 25,326
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-06 1554 GitHub · ★ 1,036

🧪 Benchmarks

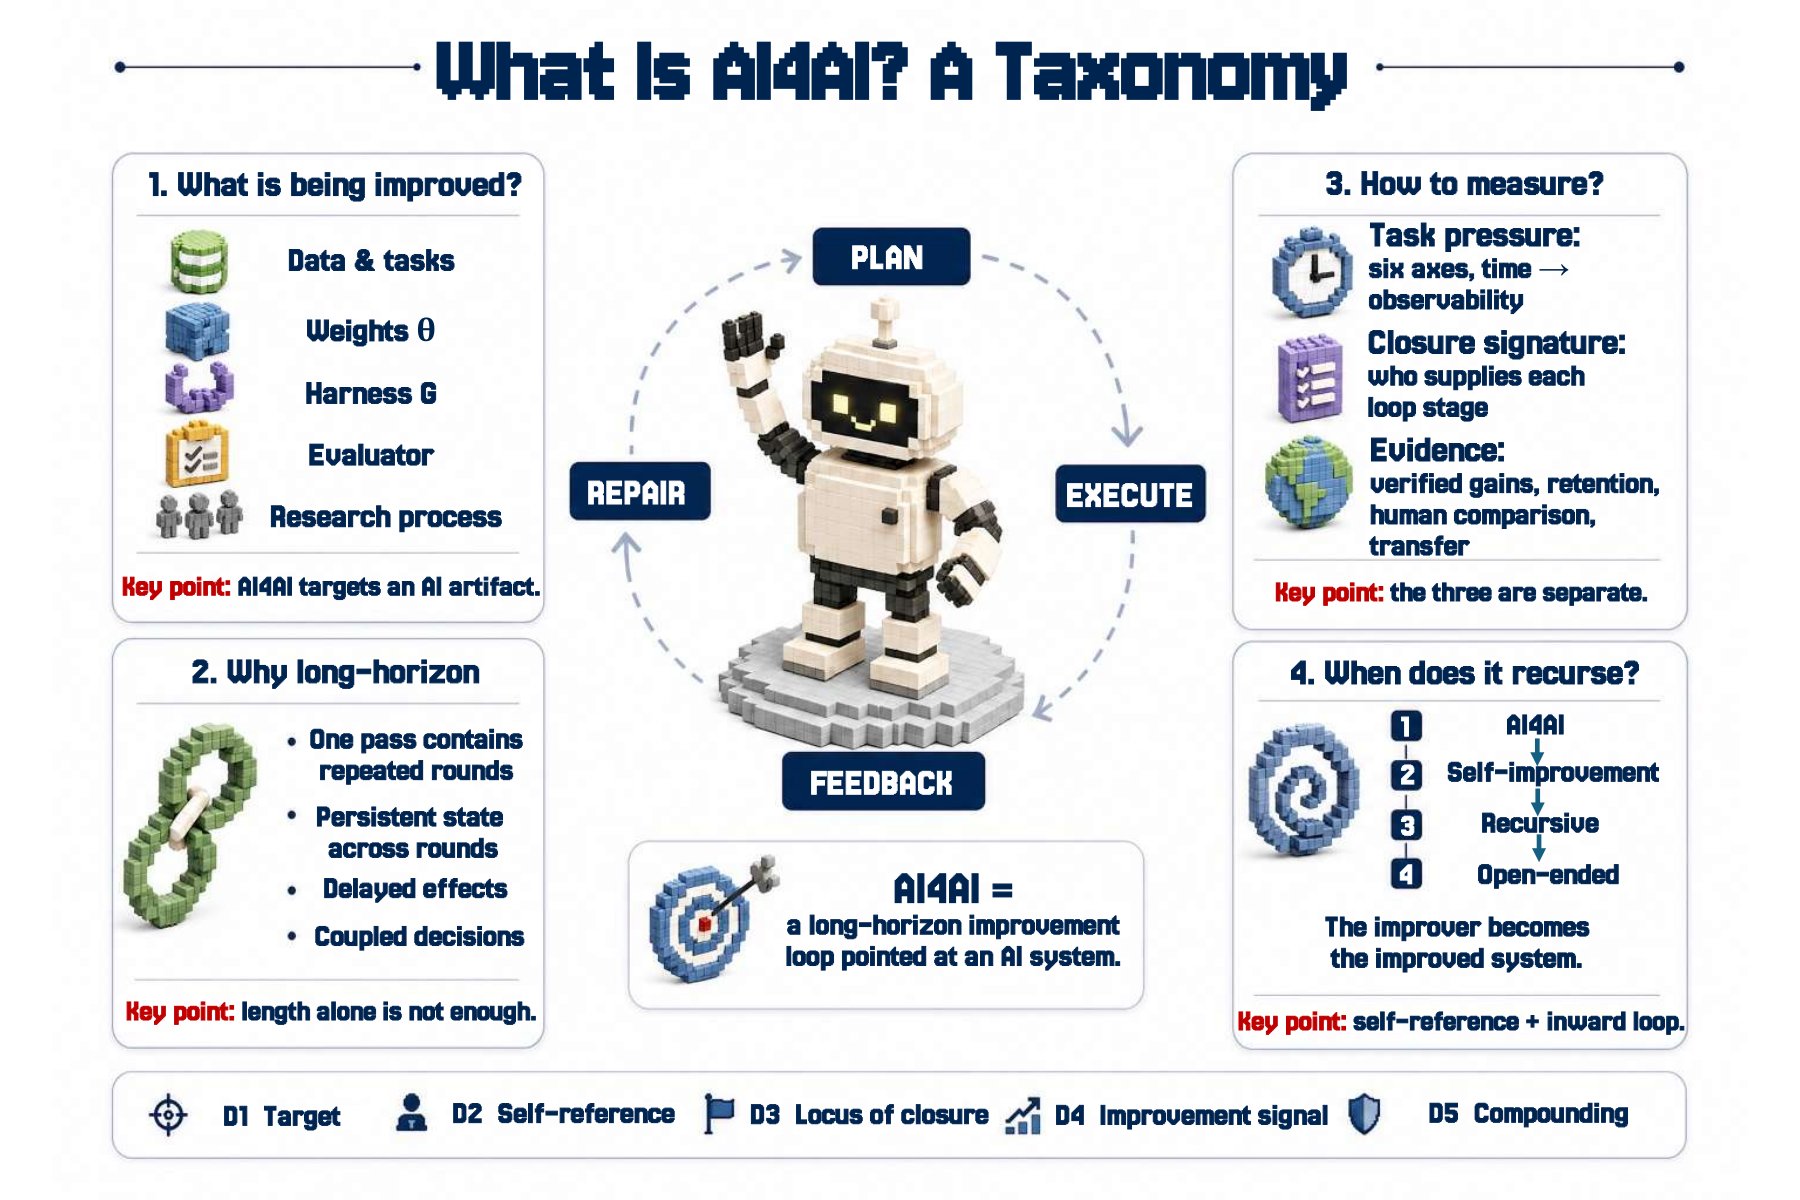
Figure 3 from the companion survey: What Is AI4AI? A Taxonomy

449 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

Paper Date Citations Code
DeliverBench: Benchmarking AI Agents on Delivering Realistic Multi-Stage Professional Projects
arXiv
2026-11 — —
Can We Stop the Backtest Yet? Anytime-Valid Promotion Tests for Adaptive Financial Research Agents
arXiv
2026-11 0 —
ScienceCUA: Resource-to-Skill Construction and Execution-Guided Skill Evolution for Scientific Computer Use Agents
arXiv
2026-11 — —
SelfImprove-Bench: Evaluating Generalization in Self-Improving Agents
arXiv
2026-11 — GitHub · ★ 2
GeoGuesser Bench: Benchmarking Vision-Language Agents on Interactive Geolocation
arXiv
2026-11 — —
Benchmark of THReD: Evaluating an LLM Agent and Its Preprocessing Tools for Turning Electronic Health Records into AI-Ready Datasets
arXiv
2026-11 — —
Do Agents Still Follow the Rules? Benchmarking Rule Compliance under Agent Context Compaction
arXiv
2026-11 — —
WebHarbor: Docking Real Websites for Evolving GUI Agent Environments
arXiv
2026-11 — GitHub · ★ 40
DiabAgent: Toward Agentic Physiological Control
arXiv
2026-11 — —
Four Bridges: Measuring Deception Propensity in a Multi-Agent Game
arXiv
2026-11 — —
Top-$k$ Retrieval Leaves Memory Value Undetermined
arXiv
2026-11 — —
RxnMiner: A Multimodal Agent for Structured Reaction Data Extraction from Chemistry Figures
arXiv
2026-11 — GitHub · ★ 4
Predictive Safety Guardrails Do Not Always Make LLM Agents Safer
arXiv
2026-11 — —
Parametric CAD Bench v3: Evaluating Agentic Parametric CAD Authoring from Text and Engineering Drawings
arXiv
2026-11 — GitHub · ★ 21
Measuring AI Agents as Teammates with Collaborative Intelligence
arXiv
2026-11 — Project
EEFA: A Framework for the Ethical Evaluation of AI Agents
arXiv
2026-11 — —
MAGAR: Multimodal Agents for GUI-Based 3D Mechanical Assembly and Minimal Rework
arXiv
2026-11 — —
Accessed, never disclosed: Silent access to protected health information by medical artificial intelligence agents
arXiv
2026-11 — —
MCP Tool Poisoning in Agentic AI Frameworks: A Cross-Framework Measurement Study
arXiv
2026-11 — —
Can LLM Agents Be Forward-Deployed Engineers? Requirement Discovery and Delivery for Enterprise Text-to-SQL
arXiv
2026-11 — —
Can Coding Agents Sustain Continual Evolution without Forgetting?
arXiv
2026-11 — GitHub · ★ 0
Beyond Accuracy: How Quantization Affects Coding Agents
arXiv
2026-11 — —
MemShift: Separating Detection from Repair in LLM-Derived Personal Memory
arXiv
2026-11 — GitHub · ★ 1
VeriHarm-Bench: Measuring Harmful Success in LLM Coding Agents Verifiably
arXiv
2026-11 — —
ACTOR: Action-Centered Temporal Organization for Literary Role-Playing Agents
arXiv
2026-11 — GitHub · ★ 5
From Tool State to Scientific Action: Auditing Decision Provenance in Biomedical Research Agents
arXiv
2026-11 — —
CONFIRM: Governing Scientific Reporting for Trustworthy Agentic Neuroimaging
arXiv
2026-11 — —
LegoEnv: Self-Evolving Agentic Environments via Modular Recombination
arXiv
2026-11 — —
MAC-Bench: Benchmarking Multi-Agent Collaboration via Interconnected Tasks
arXiv
2026-11 — —
TriPhysBench: Evaluating Physical Intelligence for Embodied Agents
arXiv
2026-11 — —
Delivered, Not Used: Evaluating Agent Memory at Its Point of Use
arXiv
2026-11 — —
Just-in-Time Skill Retrieval via Long-Horizon State Tracking
arXiv
2026-11 — —
MemHarmBench: Evaluating Cross-Session Prompt Injection in Memory-Persistent AI Agents
arXiv
2026-11 — GitHub · ★ 3
Do Embodied VLMs Actually Use Their Scene-Graph Memory?
arXiv
2026-11 — —
Beyond Prompt Injection: The Tool Update Gap in LLM Agent Security
arXiv
2026-11 — —
Better Answers, Weaker Evidence Control: Evidence Bypass in On-Policy Distillation
arXiv
2026-11 — GitHub · ★ 0
Launder-Bench: Can Repository-Level Agentic Code Laundering Be Detected?
arXiv
2026-11 — —
Step-Zero Attack: Agent Safety Before Observability
arXiv
2026-11 — —
RECEIPT: Measuring and Repairing the Return Assumption of LLM Agents in Web Service Operations
arXiv
2026-11 — —
AgenticMobility: An Open-Source Platform for Multi-AI-Agent Mobility Dynamics
arXiv
2026-11 — —
An auditable agentic pipeline for variant-to-gene prioritisation, validated against orthogonal functional evidence
arXiv
2026-11 — —
Can Large Language Model Agents Learn by Watching Tutorial Videos?
arXiv
2026-11 — —
Decision Models as Policy Gates for Coding Agents: Explicit Policy Boundaries Improve Detection and Reduce False Alarms
arXiv
2026-11 — GitHub · ★ 1
Multi-Agent Collusion and the J-Space
arXiv
2026-11 — —
Switch-SWE: Do Coding Agents Hold Focus When Switching Between Unfinished Tasks?
arXiv
2026-11 — GitHub · ★ 26
Decision-Centric Research: A Calibrated Decision Model and Benchmark for Scientific Agents
arXiv
2026-10 — —
Designing Informative Actions: Action Construction for Long-Horizon Research Agents
arXiv
2026-10 — —
When LLMs Modify Themselves: Convergence, Values, and Stopping in Iterative Self-Improvement
arXiv
2026-10 — —
CivicBench: A Benchmark and Memory Framework for Web-Based Civic Data Analytics
arXiv
2026-10 — —
Can Agentic AI Undermine Its Own Assurance Loop? Closed-Loop Dependency Assurance for Cognitive Network Digital Twins
arXiv
2026-10 — —
The Verifier Is Part of the Simulator: Evidence-View Gaming in Agentic Equation Discovery
arXiv
2026-10 — GitHub · ★ 1
CuriousTogether: Implications of Curiosity and Cultural Grounding in Multi-Agent LLM Interactions
arXiv
2026-10 — —
Toward Bounding Coding-Agent Autonomy in Software Maintenance: A Pilot Study of Boundary Contracts
arXiv
2026-10 — —
Dependable Agents Need Hard and Fuzzy Rules
arXiv
2026-10 — —
AStockArena: Beyond Returns, Can We Entrust Real Capital to the Decisions of Financial Agents?
arXiv
2026-10 — —
Do Social Influence Pressures Move LLM Agents? Evidence from Delegated Audit Judgment
arXiv
2026-10 — —
CompSkill: Compiling Execution Experience for Skill Retrieval
arXiv
2026-10 — GitHub · ★ 0
When 200 OK Is Not an Answer: Silent Fetch Failures in Agentic Web Content Acquisition
arXiv
2026-10 — —
MemU-Bench: Benchmarking GUI Agents on Long-Horizon User Interactions
arXiv
2026-10 — —
TradeWar: A Benchmark for Execution-Grounded Trade Negotiation with Adaptive LLM Agents
arXiv
2026-10 — —
ANGLER: Verifier-Grounded Benchmarking with an Adaptive Attacker for Web Agents
arXiv
2026-10 — —
Dependence-Aware Risk Assessment and Optimal Design of AI-Agent Safeguard Systems
arXiv
2026-10 — —
Decentralized Multi-Agent Coordination and Communication in Shared Codebases
arXiv
2026-10 — Project
Fidelity Collapses with Table Size, Not Turn Count: Delivery Architecture in a Deployed Tool-Using Agent
arXiv
2026-10 — —
When AI Agents Act on Our Behalf: A Taxonomy of Human-Agent Interaction Failure
arXiv
2026-10 — —
Real Computation or Merely Naming? A Pre-Registered Mechanism Audit of 25 Cognitive-Architecture Modules in an LLM-Based Agent System
arXiv
2026-10 — —
Cross-Interface Authorization for AI Computer-Use Agents
arXiv
2026-10 — —
Operon-S1: a fast decision controller for long-horizon biomedical agents
arXiv
2026-10 — —
ImplicitHop: Evaluating knowledge integration across context and memory
arXiv
2026-10 — —
Confident Fools or Careful Searchers? A Behavioural Study of When LLMs Search Beyond Their Static Internal Memory
arXiv
2026-10 — —
KEEPER: Learning Control-Sufficient Textual Memory for Long-Horizon LLM Agents
arXiv
2026-10 — —
BlindToChange: AI Agents Can Find Changes When Asked But Do They Look When Needed?
arXiv
2026-10 — —
Lineage Is Memory: Parent Inheritance and Feedback Disclosure in Short-Budget LLM-Guided Optimization
arXiv
2026-10 — GitHub · ★ 1
When Disclosure Is Compulsory: Evaluating Ride-Hailing Rebalancing Policies with Self-Interested LLM Driver Agents
arXiv
2026-10 — —
TraceSpec: Understanding and Improving Speculative Decoding for LLM Agents
arXiv
2026-10 — —
Completeness and Cost of Retrieval Structures for Multi-Tool Requests in LLM Agents
arXiv
2026-10 — —
Benchmarking Forecasting Agents on Yesterday's Tomorrows
arXiv
2026-10 — —
More Rules, Longer Lists? Benchmarking Self-Evolving Agents on a Hidden-Rule Curriculum
arXiv
2026-10 — —
DynaRev: Benchmarking Web Agents under Dynamic Goal Revision
arXiv
2026-10 0 GitHub · ★ 0
Bank-World: A Benchmark for Evaluating Agents on Banking Workflows
arXiv
2026-10 0 —
From Intent to Improvement: Agentic Dataset Search for Better Model Training
arXiv
2026-10 0 GitHub · ★ 2
ATLAS-Bench: An Agentic Tool-Use Benchmark for Local Area Search
arXiv
2026-10 0 —
AgentDecept: Benchmarking Deceptive Behavior in Tool-Using LLM Agents under Pressure
arXiv
2026-10 0 —
Well-Specified and Well-Tested? Assessing SWE-bench-Style Datasets with a Self-Evolving Agent
arXiv
2026-10 0 —
Appreciation Teaches Unauthorized Execution: Self-Evolution Degrades the Robustness of Personal Agents to Indirect Prompt Injection
arXiv
2026-10 0 GitHub · ★ 2
rTaste: Do Research Agents Have Taste? Evaluating Early Stage Research Judgment
arXiv
2026-10 0 GitHub · ★ 1
How Specific Do I Need to Be? Effects of User Query Underspecification on Deep Research Agents
arXiv
2026-10 0 —
Kerkoporta: Injecting Structured-Output Backdoors in Reasoning Coding Agents
arXiv
2026-10 — —
BABA-Bench: Evaluating Long-Horizon Patient-Advocacy Agents
arXiv
2026-10 — —
ReplayRCA: Measuring Post-hoc Diagnosis and Live Oversight of Agent Failures by Counterfactual Replay
arXiv
2026-10 — GitHub · ★ 0
P-ContextBench: From Personal Fact Recall to Personalized Agent Behavior
arXiv
2026-10 — —
Does Recursive Knowledge Construction Help Agents Verify Consensus Claims in Science?
arXiv
2026-10 — —
"Shall We Approve?" Consequence-Aware Approval for Autonomous Coding Agents
arXiv
2026-10 — —
Characterizing LLM Agent Behaviors in Module Shadowing Environments
arXiv
2026-10 — —
PrivacyFlow: Privacy in AI Agents through Information Flow Analysis and Consequence-Aware Risk Management
arXiv
2026-10 — —
Pre-Crime for Agents, at the Last Second: Probing When a Recruited Agent Gives In
arXiv
2026-10 0 GitHub · ★ 1
VeriCUA: Verification as Agentic Exploration for Computer-Using Agents
arXiv
2026-10 0 —
Prefix Executability: Evaluating Tool-Using Agents Beyond Final Success
arXiv
2026-10 0 —
EnvOS: Auditing Computer-Use Agents When the World Moves On : Phenomenon-Based Task Construction, Certification, and Evidence-Based Evaluation
arXiv
2026-10 0 —
Finding Is Not Returning, Returning Is Not Reconstructing: A Multi-Dimensional Evaluation of Agent Social Re-entry
arXiv
2026-10 0 —
Before the Next Rollout: Diagnosing Skill Utility Shifts from Policy Updates
arXiv
2026-10 0 —
What Does "Now" Mean to Your Computer-Use Agent? Stale Screenshots, Page Loads, and Which Check to Run Before a Click
arXiv
2026-10 0 GitHub · ★ 0
When to Assist and What to Suggest: Joint Gating and Memory-Grounded Hint Generation in One Compact Decoder
arXiv
2026-10 0 —
Gym-Anything for Robotics: Scaling physical simulations with digital agents
arXiv
2026-10 0 Project
Practical Assessment of Agentic Systems in Acoustics
arXiv
2026-10 0 —
Judging Before Propagation: Task-Graph Contextual Integrity for Multi-Agent Privacy
arXiv
2026-10 0 —
Soei: Structured Observability of Evidence and Intent for Multi-Agent AI Software Engineering
arXiv
2026-10 0 —
Clean Sheets and Checkpoints: Evidence Complexity for Certifying Sequential Agent Risk
arXiv
2026-10 0 —
HERA: Assessing an Autonomous Agent for Quantum Device Measurement
arXiv
2026-10 0 GitHub · ★ 0
HALO: Human-Grounded Granular Evaluation of Proactive Agents
arXiv
2026-10 0 —
AgentHeal: Evaluating Goal-Preserving Resource Recovery of Web Agents under Access Barriers
arXiv
2026-10 0 GitHub · ★ 1
Aligning Autoresearch: Co-Improvement between Agents and Humans
arXiv
2026-10 0 —
Beyond fabrication: Misattributed numbers in papers written by AI research agents
arXiv
2026-10 0 GitHub · ★ 0
An Alignment Benchmark for Enterprise Agents on Era by Eon
arXiv
2026-10 0 —
Masked Erosion: How Acceptance Gates Lose Redundant Safeguards in Self-Improving Agents
arXiv
2026-10 0 —
DecompGym: Benchmarking LLM Agents on Designing Decomposition Algorithms
arXiv
2026-10 0 GitHub · ★ 1
SkillCT: A Multidimensional Benchmark and Execution-Free Baseline for Agent Skill Assessment
arXiv
2026-10 0 —
How Deterministic SAST and AI Security Agents Divide the Work: Coverage, Harness Policy and Cost in Snyk VulnBench 2.0
arXiv
2026-10 0 GitHub · ★ 7
EPSBench: Benchmarking LLM Agents for Earnings Forecasting
arXiv
2026-10 0 —
TreasuryQA Bench: Can AI Agents Work an Archive of Scanned Financial Records?
arXiv
2026-10 0 —
Where You Inject Matters: The Trust Region Effect in LLM Agents
arXiv
2026-10 0 —
Investor's Last Exam: Can AI Agents Do Equity Investment Without Seeing the Future?
arXiv
2026-10 0 —
Disparity Laundering: Consensus Without Fairness in Clinical Multi-Agent Systems
arXiv
2026-10 0 GitHub · ★ 0
Distilling the Shape of Uncertainty: What On-Policy Distillation Learns and How to Predict It
arXiv
2026-10 0 GitHub · ★ 0
WeVisCut: The Whole Editing Room in One Agent From Narration to Long-Form Video
arXiv
2026-10 0 —
Vendster: An Evaluation Arena to Investigate How Forecasting Tool Quality Affects LLM Agent Behaviors in Buyer-Vendor Negotiation
arXiv
2026-10 0 GitHub · ★ 0
Precedent or Intent? What Coding Agents Follow When Evolving Existing Code
arXiv
2026-10 0 —
Is it my preference? Role Grounding Attack against Agent's Memory via Social Interaction
arXiv
2026-10 0 —
Repairs for Whom? Evaluator-Executor Mismatch in Selecting Repairs for Failed LLM Agents
arXiv
2026-10 0 —
LiveSearch: Questions as Executable Verifier Code for a Live Benchmark of Professional-Source Financial Search Agents
arXiv
2026-10 0 —
OpenGray: a benchmark for evaluating the decisions of radiotherapy planning agents
arXiv
2026-10 0 —
AutoVend: Benchmarking LLM Agents on Long-Horizon Autonomous Vending Operations
arXiv
2026-10 0 —
RubricAtlas: Mining Type-Level Rubrics from Expert Reports to Evaluate Deep Research Agents
arXiv
2026-10 0 —
CogArena: Benchmarking Multimodal Agents on Interactive Behavioral Experiments
arXiv
2026-10 0 GitHub · ★ 3
FeatureArc: Benchmarking Coding Agents on Evolving Features
arXiv
2026-10 0 —
Benchmarking LLM Agents for Behaviorally Adequate Test Generation from Software Requirements
arXiv
2026-10 0 —
NextEval: An Agent-Based Solver and Benchmark for Derivative-Free Optimization
arXiv
2026-10 0 —
Agentic Backdoors via Pretraining Poisoning
arXiv
2026-10 0 GitHub · ★ 8
Benchmarking Task Takeover Across Agent Handoffs
arXiv
2026-10 0 —
Your Policy Is Secretly a Harness: The Decision Geometry of Agent Interfaces
arXiv
2026-10 0 GitHub · ★ 1
SciGame: Let Agents Play the Scientific Discovery Games in the Real and Counterfactual World
arXiv
2026-10 0 —
FilingLoop: Evaluating and Evolving LLM Agents for Corporate Disclosure Review and Revision
arXiv
2026-10 0 —
Evaluating and improving AI agents for sequencing protocol understanding
arXiv
2026-10 0 —
Detecting Covert Collusion between AI Agents through Partner-Outsider Positive Listening
arXiv
2026-10 0 —
Measuring Where Intent Gets Lost in Agentic Smart Contract Synthesis
arXiv
2026-10 0 —
What Does an Ontology Catch? Curated, LLM-Generated and Data-Derived Ontologies as Checkers of LLM Agents over Knowledge Graphs
arXiv
2026-10 0 —
WebAnything: From the Wild Web to Scalable Agent Environments
arXiv
2026-10 0 GitHub · ★ 6
Scan Before You Install: Detecting and Mitigating Local and Composite Vulnerabilities in Skills
arXiv
2026-10 0 —
Poisoned Skills: Propagating Jailbreaks Through Agent Markdown Files
arXiv
2026-10 0 —
When Skills Tell Agents Not to Ask: A Large-Scale Study of Oversight Directives in Agent Skills
arXiv
2026-10 0 —
Rare, Relevant, and Still Wrong: How Memory Fails LLM Group Decisions
arXiv
2026-10 0 —
TeamGym: A Gym for Team Decision-Making by AI Agents with Distributed Information
arXiv
2026-10 0 —
Concordat: Typed Sessions for LLM Agents
arXiv
2026-10 0 GitHub · ★ 2
M4Bench: Evaluating Procedural Specification for Clinical EHR Derivation Agents
arXiv
2026-10 0 GitHub · ★ 49
Does Your Generalist Skill Optimizer Really Incentivize Agentic Tasks? Rethinking Skill Optimization via Bipartite Attribution
arXiv
2026-10 0 GitHub · ★ 4
God Does Not Play Dice: Enforcing Batch Invariance in Agentic Kernel Generation
arXiv
2026-10 0 —
InfraDev: Can Coding Agents Develop AI Infrastructure, and How Can We Tell?
arXiv
2026-10 0 —
CASEL: Consequence-Aware Selective Execution for Reliable Long-Horizon Tool-Using Agents
arXiv
2026-10 0 —
Monitor Accuracy Isn't the Answer: A Decision-Value Framework for Evaluating AI Agent Restart Monitors
arXiv
2026-10 0 —
When to Intervene? An Empirical Study of Errors and Self-Recovery in LLM Agents
arXiv
2026-10 0 Project
Correction or Manipulation? Measuring Epistemic Vigilance in LLM Agents Under User Pressure
arXiv
2026-10 0 —
Your Agent Acts Differently When You're Around: How User Presence Changes Agent Behavior in Negotiation
arXiv
2026-10 0 —
Gym-Anything-RT: Scaling Real-Time Environments for Vision-Language Agents
arXiv
2026-10 0 —
Test-Time Communication in Trading Agent Swarms
arXiv
2026-10 0 —
Where Should the Evaluation Budget Go in LLM-Driven Agent Scaffold Evolution?
arXiv
2026-10 0 —
Blindfold: Keeping the Audit Coin Secret from LLM Agents
arXiv
2026-10 0 —
Beyond QASecClaw: Agent Scaling, Verifier Feedback, and Evidence Reliability in Software Assurance
arXiv
2026-10 0 —
FIDES-Live: Evaluating Behavioral Concordance in Sequential Trading Agents
arXiv
2026-10 0 —
Words or Deeds? How LLMs Predict Users' Decisions in Human-Agent Dialogue
arXiv
2026-10 0 —
kw-bench: Breaking Frontier Harnesses on Real-World Tasks
arXiv
2026-10 0 GitHub · ★ 0
Context Is a Pipeline, Not a Window: Information Attrition in LLM Agent Harnesses
arXiv
2026-10 0 —
Free to Look, Free to Reason: Simple LLM Harnesses Outdiagnose Hand-Crafted Root Cause Analysis Agents
arXiv
2026-10 0 —
Omni-InteractScope: Benchmarking Proactive and Agentic Interaction in Continuous Omnimodal Streams
arXiv
2026-10 0 —
RSIV-Harness: A Recursive Self-Improvement Harness Framework for Open-Domain Conversational Text-to-Visualization
arXiv
2026-10 0 —
PatentAgentBench: Benchmarking LLM Agents with Professional Patent Task Suites
arXiv
2026-10 0 —
ClinVerse: A Realistic Multi-Agent Diagnostic Environment for Training and Evaluating Medical Agents
arXiv
2026-10 0 —
The Right Fact, the Wrong Decision: SciValidityBench for Scientific Agent Memory
arXiv
2026-10 — —
SearchHorizonBench: A Benchmark for Search Value in AI Agents
arXiv
2026-10 0 —
SlowLab: Benchmarking Autonomous AI Agents on a Year of Experiments They Cannot Undo
arXiv
2026-10 0 GitHub · ★ 0
Profiling a Frontier Agent with EBench: From Direct Control to Harness with Policy
arXiv
2026-10 0 Project
SkillLifeBench: Benchmarking Security Across the Lifecycle of Agent Skills
arXiv
2026-10 0 GitHub · ★ 1
How Do Coding-Agent Harnesses Self-Evolve? An Empirical Study of Retrospective Adaptation
arXiv
2026-10 0 —
The Physical Cost of Context: Quality-Constrained Resource Accounting for Coding Agents
arXiv
2026-10 0 —
Quantifying Claim Smoothing by LLM Research Agents
arXiv
2026-10 0 GitHub · ★ 0
iPrefBench: A User-Centric Benchmark for Personalized Mobile Use Agents
arXiv
2026-10 0 —
When Retrieval Is Not Enough: Obsolete Facts in Agent Memory
arXiv
2026-10 0 —
Agent or Human? Detecting Commits by AI Coding Agents in the Absence of Authorship Signatures
arXiv
2026-10 0 —
Replication or Corroboration? An Axiomatic Framework for Evidential Dependence in Multi-Agent Debate
arXiv
2026-10 0 —
Log-To-Leak: Prompt Injection Attacks on Tool-Using LLM Agents via the Model Context Protocol
arXiv
2026-10 0 —
Do Coding Agents Still Need a Debugger? Frontier-Model-Based Fault Localization at the Accuracy Ceiling
arXiv
2026-10 — —
PROBE: Frontier Coding Agents Find Different Bugs Than Maintainers Fix
arXiv
2026-10 0 —
Generation and Verification: Human-Agent Collaboration for Safety-Critical Automotive Software Engineering
arXiv
2026-10 0 —
UnityBench-Mini3D: Evaluating LLM Agents for 3D Game Development in Unity
arXiv
2026-10 0 —
A Unified Arena for LLM Agents across Diverse Eurogame
arXiv
2026-10 — —
AgenticCity-Bench: Longitudinal Multimodal Observations of Urban Dynamics with Agentic Reasoning
arXiv
2026-10 0 Project
Proof-of-Agentness: Towards Verifying Agents on the Web
arXiv
2026-10 0 —
LongSearchEval: Evaluating Long-Horizon Web Search Capabilities of Large Language Models via a Trajectory-Aware Agent Framework with Failure-Node Localization
arXiv
2026-10 0 —
Co-Design Bench: Multimodal Collaborative Coding Evaluation for Agentic Models
arXiv
2026-10 0 Project
Collective Emergent Alignment: Measuring and Amplifying Interaction-Induced Reasoning Alignment in Multi-Agent LLMs
arXiv
2026-10 0 —
Scope-Gap Injection: Exploiting Evaluator Channel Blind Spots in the OpenClaw Agent Security Competition
arXiv
2026-10 0 —
The Agent in the Middle: How AI-Mediated Access Reshapes Web Vulnerability Exploitation
arXiv
2026-10 0 —
The Hidden Costs of Forgetting: A Study of Trajectory Deletion in Software Engineering Agents
arXiv
2026-10 0 —
V$^3$AST-Bench: Verifiable, Valid, and Versatile Safety Evaluation for Coding Agents
arXiv
2026-10 — GitHub · ★ 5
CoSA: The Conflict of Skills Attack in Real-World LLM Agent Ecosystems
arXiv
2026-10 0 —
NumTrace: Auditing the Number Provenance of Financial Analyst Agents
arXiv
2026-10 0 —
Adaptive Retrieval, Selective Answers: Evaluating Conformal Factuality in Agentic RAG
arXiv
2026-10 0 GitHub · ★ 0
Silent and Costly: Characterizing and Detecting Prompt-Caching Mis-Integration in LLM Agents
arXiv
2026-10 0 —
Babysitting AI Agents: A User-Centered Taxonomy and Study of Agentic Delegation Failures
arXiv
2026-10 0 —
RobotAgentBench: Towards Open-world Robot Autonomy
arXiv
2026-10 0 Project
From Questions to Queries to Insights: A Schema-Grounded Agentic Workflow for Natural-Language Crash Data Analysis
arXiv
2026-10 0 —
Semantic Atoms for Scalable Text Analysis in Data Analytics in the Era of LLM-Based Agents
arXiv
2026-10 0 —
BehaviorMem: Building and Evaluating User Memory from Real-World E-Commerce Behavior Streams
arXiv
2026-10 0 —
Rethinking Verification in Agent Harnesses
arXiv
2026-10 0 —
R2A-Sales: A Policy-Atom-Matched Benchmark for Rule-to-Action Gaps in Goal-Directed Sales Agents
arXiv
2026-10 0 —
AgentProofBench: Benchmarking Reusable Verifiers for Web Agents
arXiv
2026-10 0 —
SentryBench: A Cost-Sensitive Benchmark for Adversarial Robustness of Tool-Using LLM Agents in Public-Safety Deployments
arXiv
2026-10 0 —
Continual Learning Exam: Benchmarking Long-Horizon RSI and Experiential Learning in LLM Agents
arXiv
2026-10 0 Project
The Coordination Tax and the Heterogeneity Dividend: Break-Even Conditions for Multi-Agent LLM Pipelines
arXiv
2026-10 0 —
What Effort Level Should I Choose? On the Economics of Reasoning Effort in LLM Agents
arXiv
2026-10 0 —
CTXAgent - Self-Controlled Context Management of LLM Agents
arXiv
2026-10 0 —
Matched Capabilities, Different Behaviors: A Controlled Study of MCP and CLI Interfaces for Language Agents
arXiv
2026-10 0 —
Task Success Is Not Enough: Side-effect-Aware Evaluation of Tool-Using Language Model Agents
arXiv
2026-10 0 GitHub · ★ 1
LLM WikiLeaks: Uncovering URL-Based Capability Extension and Security Circumvention in Agentic Message Boards
arXiv
2026-10 0 —
The Price of Scale in Proactive Memory Recall
arXiv
2026-10 0 GitHub · ★ 0
ParetoRSI-Gym: Can AI Agents Improve Language Models Across Multiple Domains?
arXiv
2026-10 0 —
Outcome-Aware Agents: When Does Causal Structure Help a Forward Model Foresee the Consequences of Actions?
arXiv
2026-10 — GitHub · ★ 0
AndroidFlux: Evaluating and Reward Modeling Failure Recovery Capabilities in Mobile Use Multimodal Agents
arXiv
2026-10 0 —
SEEK: Skill Extraction with Evolving Knowledge against Frontier Science Agents
arXiv
2026-10 0 —
NameTrap: Steering AI Coding Agents Toward Security Vulnerabilities via Variable Names
arXiv
2026-10 0 —
$\Delta\tau$-Bench: Pushing Agents Toward a Moving Capability
arXiv
2026-10 0 —
Memory Tax: Dissecting the Net Value of Agent Memory
arXiv
2026-10 0 Project
How Do Small Coding Agents Use Code Graphs and Embeddings?
arXiv
2026-10 0 —
Build, Don't Play: Self-Improving LLM Research Agents Develop a Hearthstone Battlegrounds AI That Rivals Top Players
arXiv
2026-10 0 GitHub · ★ 228
PACE: Research Proving Agent for Adaptive Conjecture Exploration
arXiv
2026-10 0 —
SkillShift-Bench: Benchmarking Skill Learning under Environment Evolution for Web Agents
arXiv
2026-10 0 Project
Build or Adopt? Custom-Built vs. General-Purpose LLM Agent Harnesses for Automotive GUI Testing
arXiv
2026-10 0 —
RSI Arena: Towards Recursive Self-Improvement with Human Feedback
arXiv
2026-10 0 Project
ReGE: Stronger Agents through Experience Synthesis
arXiv
2026-10 0 —
FraudSociety: A Generative Agent-Based Society for the Financial-Fraud Economy
arXiv
2026-10 0 —
ConMem: Counterfactual Multi-Scenario Probing for Resolving LLM Memory Misalignment
arXiv
2026-10 0 —
AgentOrch: How Close Can Global Orchestration Come to Step-by-Step Interaction?
arXiv
2026-10 0 —
Memory or a Clock? Auditing a Memory Advantage in XLand-MiniGrid with Seeds, Maps and Evaluation Noise Apart
arXiv
2026-10 0 GitHub · ★ 0
Strategic Calibration in LLM Multi-Agent Systems: Audited Pivot Scoring for Truthful Elicitation
arXiv
2026-10 0 —
ProbeID: Verifying MCP Tool Identity for LLM Agents under Registry Drift
arXiv
2026-10 0 —
Can Agentic Code Review Catch Vulnerabilities Before They Are Merged?
arXiv
2026-10 — GitHub · ★ 4
Novel or Not? PatEx-Gym: Agentic Prior-Art Search for Novelty Assessment in Patent Examination
arXiv
2026-10 0 —
Estimation of Propagated Risk in LLM-based Multi-Agent Systems
arXiv
2026-10 0 —
AOS-Bench: Can LLM Agents Manage Dynamic Workloads?
arXiv
2026-10 0 —
Responsibility Boundaries for Agentic Systems: A Comparative Evaluation of Probabilistic Agentic Programming
arXiv
2026-10 0 —
Position, Role or Label? A Controlled Study of Instruction Conflicts in LLM Agents
arXiv
2026-10 0 GitHub · ★ 1
RIDAR: Safeguarding Research Integrity in Autonomous Research Agents via Automated Detection and Runtime Intervention
arXiv
2026-10 0 —
AgentPhishing: A Benchmark of LLM Email Agents Under Adaptive Attack
arXiv
2026-10 0 —
What the Specification Did Not Say: Specification-Oracle Gaps in Test-Graded Coding-Agent Benchmarks
arXiv
2026-10 0 —
Beyond Watching and Searching: Benchmarking Agents for Video-centered Deep Research Reports
arXiv
2026-10 0 GitHub · ★ 14
EpiSEM-Bench: Evaluating Safety and Evidence Recovery in LLM Agents under Missing Evidence
arXiv
2026-10 0 —
Simulated Control Evals
arXiv
2026-10 0 —
Can LLMs Improve Their Own Harness? A Controlled Study on ARC-AGI-3
arXiv
2026-10 0 —
From Prose to Properties: Testing Research Claims with ARATest for Agent-Native Science
arXiv
2026-10 0 GitHub · ★ 6
Why Bother Me Again? Benchmarking Personal Agent Memory for Interaction Preferences
arXiv
2026-10 0 —
GAV: A scientific experimentation environment for PDE agents
arXiv
2026-10 0 GitHub · ★ 6
Real PMIDs, Wrong Papers: Harness Design for Biomedical Claim-Verification Agents
arXiv
2026-10 0 GitHub · ★ 3
PreCoMem: Predictive Cognitive Memory for Self-Evolving Long-Term Dialogue Agents
arXiv
2026-10 0 GitHub · ★ 1
GenXR-Bench: Benchmarking Coding Agents for Interactive XR Development
arXiv
2026-10 0 GitHub · ★ 0
Quant-Arena: Benchmarking LLM Agents for Quantitative Trading Research
arXiv
2026-10 0 —
MOSAIC: An Omni-Modal Benchmark for Long-Term Memory and Cross-Modal Reasoning in Conversational Agents
arXiv
2026-10 0 —
IFC-MCQ: Automatically Generating Multiple-Choice Benchmarks for Evaluating LLM Agents on IFC Data Retrieval
arXiv
2026-10 0 —
AgentPolicyForge: From Executable Environments to Policy Benchmarks and Adaptive Guards
arXiv
2026-10 0 —
RSI Control: Can AI Models Perform Covert Sabotage in the Self-Improvement Process?
arXiv
2026-10 0 —
CUA-Recovery: Benchmarking Error Recovery in Long-Horizon Computer-Use Agents
arXiv
2026-10 0 GitHub · ★ 2
DuplexLedger: Benchmarking Transactional Memory in Full-Duplex Speech Agents
arXiv
2026-10 0 GitHub · ★ 4
Act on Your Behalf, Beyond Your Authorization: Benchmarking LLM Agent Authorization Alignment
arXiv
2026-10 0 GitHub · ★ 3
MemDev-Bench: Does Memory Help Code Agents?Benchmarking Memory Systems over Real Repository Histories
arXiv
2026-10 0 —
Recoverability and Verifier Strength: Two Measured Preconditions for Unattended Agent Self-Improvement
arXiv
2026-10 0 —
After the Attacker Leaves: Benchmarking Carryover Attacks on LLM Agents
arXiv
2026-10 0 —
Auditing the Product, Not the Recursion: The Evaluation Evidence Behind Recursive Self-Improvement Claims
arXiv
2026-10 0 —
Is Anyone Enforcing the Cartel? What Reinforcement Learning Teaches LLM Agents in Markets
arXiv
2026-10 0 —
CAPSafe: A Benchmark for Contextual Action and Plan Safety Reasoning in Embodied Agents
arXiv
2026-10 0 —
VerifierBench: Benchmarking the Generation of Executable Verifiers for LLM Agents
arXiv
2026-10 0 —
ReuF2F: Benchmarking Coding Agents on Formalized Undergraduate Research Problems
arXiv
2026-10 0 GitHub · ★ 25
LoWAgent: A Low-Resource Multilingual Benchmark for Web Agents
arXiv
2026-10 0 —
When the harness decides success: state that cannot be re-observed
arXiv
2026-10 0 GitHub · ★ 0
VibeTraining-Bench: Data-Trainer-Harness Co-Design for Iterative System Improvement
arXiv
2026-10 0 GitHub · ★ 6
Reliable Before Profitable: QuantHarness for Governing Financial Strategy Development with LLM Agents
arXiv
2026-10 0 —
CXBench: A Benchmark for Process-Compliant LLM Agents in Regulated Customer-Experience Workflows
arXiv
2026-10 0 —
When Should AI Chime In? Benchmarking Timely Contribution of Proactive Agents in Multi-Party Chat
arXiv
2026-10 0 —
Are Self-Evolving Agents Continual Learners?
arXiv
2026-10 0 —
RefCraft: Benchmarking Visual-Reference-Conditioned Agentic Generation through Web Development
arXiv
2026-10 0 —
AdaExploreBench: Benchmarking LLM Agents for Proactive Exploration and Test-time Adaptation in Evolving Environments
arXiv
2026-10 0 —
RealControlBench: A Benchmark for Interpretability-Informed Fine-Grained Control of LLMs and Agents
arXiv
2026-10 0 —
What Can't Jev Decide? Probing the Limits of One-Pass Decision Models
arXiv
2026-10 0 —
BrandEval: A Two-Track Multi-Agent Benchmark for Risk-Sensitive LLM Crisis Communication
arXiv
2026-10 0 GitHub · ★ 1
MemDerive: A Diagnostic Benchmark for Agent Memory over Evolving Data
arXiv
2026-10 0 —
Auto-MD-bench: Evaluating Autoresearch Agents for Real-World Medical Tasks
arXiv
2026-10 0 GitHub · ★ 1
MemBubble: Benchmarking How Agent Memory Shapes LLM Response Diversity
arXiv
2026-10 0 —
Who Convinced Whom? Tracing How LLMs Change Their Minds in Multi-Agent Systems
arXiv
2026-10 0 —
HSPR: Recovering Software-Agent Benchmark Scores via Hierarchical Posterior Inference
arXiv
2026-10 0 —
OR-License: Evaluating LLM Agents as Real-World Operations Research Practitioners
arXiv
2026-10 0 GitHub · ★ 83
WebCoder: Scaling General Frontend Development with Artifact-Grounded Agentic Reinforcement Learning
arXiv
2026-10 0 —
From Approval to Abuse: Privilege Escalation Attacks on Harness-Protected Coding Agents
arXiv
2026-10 0 —
MS-Eval: Benchmarking Sub-Agent Delegation and Orchestration in MCP-Intensive Working Scenarios
arXiv
2026-10 0 —
PersonaCUABench: Benchmarking Computer-Use Agents Serving Diverse Personas
arXiv
2026-10 0 GitHub · ★ 2
Self-Evolving Agents Can Repair Failures but Struggle to Generalize from Them
arXiv
2026-10 0 —
ToolBottleneckBench: Measuring Tool-Agent Performance under Controlled Pressures and Fixed Harness Budgets
arXiv
2026-10 0 GitHub · ★ 1
Harness-Delta Attribution: Dissecting Gains From Harness Evolution
arXiv
2026-10 0 —
AuditKIT: A Unified Evaluation Spine for Benchmarking, Judging, and Comparing Large Language Models and Agentic Systems
arXiv
2026-10 0 GitHub · ★ 18
From Research Goals to Scientific Closure: Evaluating Agents Through Evidence-Supported Physics Research
arXiv
2026-10 0 —
Skip the Compressor: Coding Agents Fix More Issues When They Pick Whole Files
arXiv
2026-10 0 —
Doc2Harness: Benchmarking LLMs on Long-Horizon Harness Engineering of Coding Agents
arXiv
2026-10 0 —
SEAR: Self-Evolving Agentic Robotics
arXiv
2026-10 0 —
Lessons from Luck: Do LLM-Written Lessons Carry Chance into an Agent's Next Decision?
arXiv
2026-10 0 —
Exposure Is Not Commitment: Double-Stratified Evaluation of Latent Monitors for Tool-Using Agents
arXiv
2026-10 0 GitHub · ★ 0
Recursive Semantic Divergence for LLM Agent Consistency
arXiv
2026-10 0 GitHub · ★ 0
When Agents Collude: Weak-to-Strong On-Policy Distillation for Mitigating Strategic Deception in Multi-Agent Systems
arXiv
2026-10 0 Project
Agent Plasticity: Measuring Self-Improvement Through Experience
arXiv
2026-10 0 —
GeoNatureAgent (GNA): A Framework and Benchmark for Pre-Production Evaluation of Tool-Using Agents on Geospatial and Environmental Tasks
arXiv
2026-10 0 —
AutoSciBench: Autonomous Benchmark Generation for Evaluating Scientific Agents
arXiv
2026-10 0 —
Complex Agents, Shallow Tests: Demystifying and Enhancing Test Adequacy of Agent Harness in the Wild
arXiv
2026-10 0 —
Probe the Harness: Setup Checks for Stale-Data RL Comparisons in Language Models
arXiv
2026-10 0 —
ReFract: Benchmarking Perspective Awareness in Language Model Agents with Text World Models
arXiv
2026-10 0 —
Safety Must Survive Self-Improvement: Why Failures Persist and How Agents Recover
arXiv
2026-10 0 —
Auditing Web Agent Evaluation on WebArena-Lite: Human Review of Outcomes and Trajectories
arXiv
2026-10 0 —
Harnessing LLMs as Agents: What Does It Cost?
arXiv
2026-10 0 —
Agent Error Dataset: Scaling 50,000 Error--Diagnosis Pairs for Failure Analysis and Error-Aware Post-Training
arXiv
2026-09 0 —
CompMat-Bench: Benchmarking AI Agents for Computational Materials Science
arXiv
2026-09 0 —
EurekaBench: Measuring Agentic Ability to Discover New Scientific Insights
arXiv
2026-09 0 —
Harness Evolution as Learning: Approximation, Generalization, and Optimization Limits of Self-Improving Personal Agents
arXiv
2026-09 0 —
LLM Agents Can Easily Tamper With Their Own Traces
arXiv
2026-09 0 —
Total Cost of Agency: Exact Attribution of Memory Injection Cost in Multi-Agent LLM Workflows
arXiv
2026-09 0 GitHub · ★ 0
Bridging Static and Agentic RAG for Taiwanese Historical Question Answering
arXiv
2026-09 0 —
SWE-Bench Pro Verified: A Reliable Benchmark for Software Engineering Agents
arXiv
2026-09 0 —
$\tau^\tau$-Bench: An Environment for End-To-End, Realistic Agent Construction
arXiv
2026-09 0 —
EvoHarnessBench: Can Your Agents Keep Pace with an Evolving Harness?
arXiv
2026-09 0 —
HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?
arXiv
2026-09 0 —
E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation
arXiv
2026-08 0 GitHub · ★ 126
SWE Refactor Bench: Can Coding Agents Complete a Long-Horizon, Whole-Repository Stack Migration?
arXiv
2026-08 0 —
AI4AI-Bench: Benchmarking LLM Agents in Algorithmic Design for Recursive Self-Improvement
arXiv
2026-08 0 —
PAST-Bench: Benchmarking the Foundations of Recursive Self-Improvement in Personal Agents
arXiv
2026-08 0 GitHub · ★ 35
SWE-Bench ProMax: Benchmarking Agents on Large-Scale Multilingual Code Refactoring
arXiv
2026-08 9 —
HarnessOpt-Bench: Evaluating LLMs at Harness Optimization
arXiv preprint arXiv:2608.06301
2026-08 9 —
When History Lies: Evaluating and Improving Tool Use under Misleading Multi-Turn Histories
arXiv preprint arXiv:2608.06057
2026-08 0 —
DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks
arXiv preprint arXiv:2607.07946
2026-07 61 GitHub · ★ 1,884
ChainSWE: Benchmarking Coding Agents on Multi-Bug Software Maintenance
arXiv preprint arXiv:2607.02606
2026-07 7 —
Kimi K3: Open Frontier Intelligence
arXiv
2026-07 103 GitHub · ★ 9,041
Can AI Agents Conduct Open-Ended AI Research? Early Evidence from Two Case Studies
arXiv
2026-07 14 —
RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
arXiv
2026-07 22 GitHub · ★ 179
Do Agent Benchmarks Measure Capability? Protocol Validity in the Age of Agentic AI
arXiv preprint arXiv:2607.22368
2026-07 6 —
Do Agent Optimizers Compound? A Continual-Learning Evaluation on Terminal-Bench 2.0
arXiv preprint arXiv:2607.14004
2026-07 5 GitHub · ★ 8
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-07 8 GitHub · ★ 870
PerspectiveGap: A Benchmark for Multi-Agent Orchestration Prompting
arXiv
2026-06 0 GitHub · ★ 4
FrontierSWE
Proximal Blog
2026 — GitHub · ★ 237
WeaveBench: A Long-Horizon, Real-World Benchmark for Computer-Use Agents with Hybrid Interfaces
arXiv preprint arXiv:2606.09426
2026-06 11 —
Do LLMs Catch Their Own Mistakes? A Comprehensive Benchmark for Reflective Tool Use LLMs
Findings of the Association for Computational Linguistics: ACL 2026
2026 0 —
The Meta-Agent Challenge: Are Current Agents Capable of Autonomous Agent Development?
arXiv preprint arXiv:2606.04455
2026-06 9 GitHub · ★ 24
SWE-Explore: Benchmarking How Coding Agents Explore Repositories
arXiv
2026-06 21 GitHub · ★ 44
SWE-InfraBench: Evaluating Language Models on Cloud Infrastructure Code
arXiv
2026-06 0 —
SWE-Marathon: Can Agents Autonomously Complete Ultra-Long-Horizon Software Work?
arXiv
2026-06 21 —
FARS: A Fully Automated Research System Deployed at Scale
arXiv
2026-06 7 —
DeskCraft: Benchmarking Desktop Agents on Professional Workflows and Human-in-the-Loop Collaboration
arXiv preprint arXiv:2606.03103
2026-06 3 GitHub · ★ 91
NatureBench: Can Coding Agents Match the Published SOTA of Nature-Family Papers?
arXiv
2026-06 9 GitHub · ★ 137
OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks
arXiv
2026-06 39 GitHub · ★ 406
MLS-Bench: A Holistic and Rigorous Assessment of AI Systems on Building Better AI
arXiv preprint arXiv:2605.08678
2026-05 18 GitHub · ★ 128
ProgramBench: Can Language Models Rebuild Programs From Scratch?
arXiv
2026-05 56 GitHub · ★ 980
RoadmapBench: Evaluating Long-Horizon Agentic Software Development Across Version Upgrades
arXiv
2026-05 3 GitHub · ★ 17
SWE Atlas: Benchmarking Coding Agents Beyond Issue Resolution
arXiv
2026-05 7 GitHub · ★ 86
SWE-Chain: Benchmarking Coding Agents on Chained Release-Level Package Upgrades
arXiv
2026-05 11 GitHub · ★ 17
SWE-Cycle: Benchmarking Code Agents across the Complete Issue Resolution Cycle
arXiv
2026-05 5 GitHub · ★ 0
Breaking, Stale, or Missing? Benchmarking Coding Agents on Project-Level Test Evolution
arXiv
2026-05 2 GitHub · ★ 5
How Far Are We From True Auto-Research?
arXiv
2026-05 9 —
Agent^2 RL-Bench: Can LLM Agents Engineer Agentic RL Post-Training?
arXiv preprint arXiv:2604.10547
2026-04 9 GitHub · ★ 15,208
Toward autonomous long-horizon engineering for ML research
arXiv
2026-04 14 GitHub · ★ 146
KnowU-Bench: Towards Interactive, Proactive, and Personalized Mobile Agent Evaluation
arXiv preprint arXiv:2604.08455
2026-04 25 GitHub · ★ 82
CI-Repair-Bench: A Repository-Aware Benchmark for Automated Patch Validation via CI Workflows
arXiv
2026-04 2 GitHub · ★ 1
Evaluating LLM-Based 0-to-1 Software Generation in End-to-End CLI Tool Scenarios
arXiv
2026-04 4 GitHub · ★ 2
AutoSOTA: An End-to-End Automated Research System for State-of-the-Art AI Model Discovery
arXiv
2026-04 21 GitHub · ★ 704
The Long-Horizon Task Mirage? Diagnosing Where and Why Agentic Systems Break
arXiv preprint arXiv:2604.11978
2026-04 28 —
SWE-Milestone: Evaluating AI Agents on Continuous Software Evolution
International Conference on Machine Learning
2026-03 11 GitHub · ★ 80
Beyond pass@1: A Reliability Science Framework for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.29231
2026-03 10 —
Towards End-to-End Automation of AI Research
Nature 2026
2026-03 317 GitHub · ★ 7,433
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-03 60 GitHub · ★ 611
ReCUBE: Evaluating Repository-Level Context Utilization in Code Generation
arXiv
2026-03 1 GitHub · ★ 1
SWE-CI: Evaluating Agent Capabilities in Maintaining Codebases via Continuous Integration
arXiv
2026-03 28 GitHub · ★ 183
FeatureBench: Benchmarking Agentic Coding for Complex Feature Development
arXiv
2026-02 40 GitHub · ★ 100
LongCLI-Bench: A Preliminary Benchmark and Study for Long-horizon Agentic Programming in Command-Line Interfaces
arXiv
2026-02 35 GitHub · ★ 49
AIRS-Bench: A Suite of Tasks for Frontier AI Research Science Agents
arXiv
2026-02 29 GitHub · ★ 125
SWE-rebench V2: Language-Agnostic SWE Task Collection at Scale
arXiv preprint arXiv:2602.23866
2026-02 29 —
LUMINA: Long-horizon Understanding for Multi-turn Interactive Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-01 3 —
RepoGenesis: Benchmarking End-to-End Microservice Generation from Readme to Repository
arXiv
2026-01 13 GitHub · ★ 102
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
arXiv
2026-01 612 GitHub · ★ 2,614
ARC: Active and Reflection-driven Context Management for Long-Horizon Information Seeking Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-01 8 —
DeepPlanning: Benchmarking Long-Horizon Agentic Planning with Verifiable Constraints
arXiv preprint arXiv:2601.18137
2026-01 45 —
Toward ultra-long-horizon agentic science: Cognitive accumulation for machine learning engineering
arXiv
2026-01 28 —
Towards a Science of Scaling Agent Systems
arXiv
2025-12 153 GitHub · ★ 63
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-12 31 GitHub · ★ 44
NL2Repo-Bench: Towards Long-Horizon Repository Generation Evaluation of Coding Agents
arXiv
2025-12 74 GitHub · ★ 192
SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios
arXiv
2025-12 64 GitHub · ★ 61
Holistic Agent Leaderboard: The Missing Infrastructure for AI Agent Evaluation
arXiv preprint arXiv:2510.11977
2025-10 101 GitHub · ★ 308
BuildBench: Benchmarking LLM Agents on Compiling Real-World Open-Source Software
arXiv
2025-09 2 —
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
arXiv
2025-09 308 GitHub · ★ 557
HeroBench: A Benchmark for Long-Horizon Planning and Structured Reasoning in Virtual Worlds
arXiv preprint arXiv:2508.12782
2025-08 7 GitHub · ★ 14
Hell or High Water: Evaluating Agentic Recovery from External Failures
Second Conference on Language Modeling
2025-08 11 GitHub · ★ 5
OdysseyBench: Evaluating LLM Agents on Long-Horizon Complex Office Application Workflows
arXiv preprint arXiv:2508.09124
2025-08 58 GitHub · ★ 20
Evaluation and Benchmarking of LLM Agents: A Survey
Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.2
2025-07 231 GitHub · ★ 21
SWE-MERA: A Dynamic Benchmark for Agenticly Evaluating Large Language Models on Software Engineering Tasks
Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: System Demonstrations
2025-07 8 —
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025 634 GitHub · ★ 13,061
DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents
arXiv preprint arXiv:2506.11763
2025-06 262 GitHub · ★ 848
Mind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge
arXiv preprint arXiv:2506.21506
2025-06 84 GitHub · ★ 114
RoboCerebra: A Large-scale Benchmark for Long-horizon Robotic Manipulation Evaluation
Advances in Neural Information Processing Systems
2025-06 45 GitHub · ★ 79
ALE-Bench: A Benchmark for Long-Horizon Objective-Driven Algorithm Engineering
Advances in Neural Information Processing Systems
2025-06 44 GitHub · ★ 237
ML-Master: Towards AI-for-AI via integration of exploration and reasoning
arXiv
2025-06 63 GitHub · ★ 454
MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research
arXiv preprint arXiv:2505.19955
2025-05 69 GitHub · ★ 38
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05 527 GitHub · ★ 302
SWE-bench Goes Live!
Advances in Neural Information Processing Systems
2025-05 85 GitHub · ★ 261
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04 342 GitHub · ★ 1,333
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03 756 GitHub · ★ 433
A Survey on Evaluation of LLM-based Agents
Findings of the Association for Computational Linguistics: ACL 2026
2025-03 250 —
Robotouille: An Asynchronous Planning Benchmark for LLM Agents
International Conference on Learning Representations
2025-02 43 GitHub · ★ 49
DI-BENCH: Benchmarking Large Language Models on Dependency Inference with Testable Repositories at Scale
Findings of the Association for Computational Linguistics: ACL 2025
2025-01 9 GitHub · ★ 8
TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks
Advances in Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track
2024-12 358 GitHub · ★ 810
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts
arXiv
2024-11 191 GitHub · ★ 171
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10 502 GitHub · ★ 1,789
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10 269 GitHub · ★ 845
Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale
International Conference on Machine Learning
2024-09 225 GitHub · ★ 915
ToolSandbox: A Stateful, Conversational, Interactive Evaluation Benchmark for LLM Tool Use Capabilities
Findings of the Association for Computational Linguistics: NAACL 2025
2024-08 347 GitHub · ★ 290
OfficeBench: Benchmarking Language Agents across Multiple Applications for Office Automation
arXiv preprint arXiv:2407.19056
2024-07 66 GitHub · ★ 49
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07 439 GitHub · ★ 546
Introducing SWE-bench Verified
—
2024 — —
WebCanvas: Benchmarking Web Agents in Online Environments
ICML 2024 Workshop on Agentic Markets
2024-06 128 GitHub · ★ 282
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-06 1502 GitHub · ★ 1,488
NATURAL PLAN: Benchmarking LLMs on Natural Language Planning
arXiv preprint arXiv:2406.04520
2024-06 148 GitHub · ★ 59
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05 486 GitHub · ★ 995
Benchmarking Mobile Device Control Agents across Diverse Configurations
arXiv preprint arXiv:2404.16660
2024-04 54 GitHub · ★ 33
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-04 1356 GitHub · ★ 3,250
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03 407 GitHub · ★ 279
OmniACT: A Dataset and Benchmark for Enabling Multimodal Generalist Autonomous Agents for Desktop and Web
Computer Vision -- ECCV 2024
2024-02 172 —
WebLINX: Real-World Website Navigation with Multi-Turn Dialogue
International Conference on Machine Learning
2024-02 195 GitHub · ★ 164
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02 511 GitHub · ★ 567
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01 494 GitHub · ★ 1,128
VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01 41 GitHub · ★ 490
MinePlanner: A Benchmark for Long-Horizon Planning in Large Minecraft Worlds
Proceedings of the 6th ICAPS Workshop on the International Planning Competition (WIPC)
2023-12 9 GitHub · ★ 23
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-10 4403 GitHub · ★ 6,138
AgentBench: Evaluating LLMs as Agents
International Conference on Learning Representations
2023-08 1494 GitHub · ★ 3,808
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-07 2466 GitHub · ★ 5,764
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-07 2300 GitHub · ★ 1,640
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-06 1554 GitHub · ★ 1,036
WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents
Advances in Neural Information Processing Systems
2022-07 1544 GitHub · ★ 613
BEHAVIOR-1K: A benchmark for embodied AI with 1,000 everyday activities and realistic simulation
Proceedings of The 6th Conference on Robot Learning
2022 474 GitHub · ★ 1,790
WebGPT: Browser-assisted question-answering with human feedback
arXiv preprint arXiv:2112.09332
2021-12 2138 —
ALFRED: A Benchmark for Interpreting Grounded Instructions for Everyday Tasks
Proceedings of the IEEE/CVF conference on computer vision and pattern recognition
2019-12 1243 GitHub · ★ 533
World of Bits: An Open-Domain Platform for Web-Based Agents
Proceedings of the 34th International Conference on Machine Learning
2017 352 —

🛠️ Harness Design

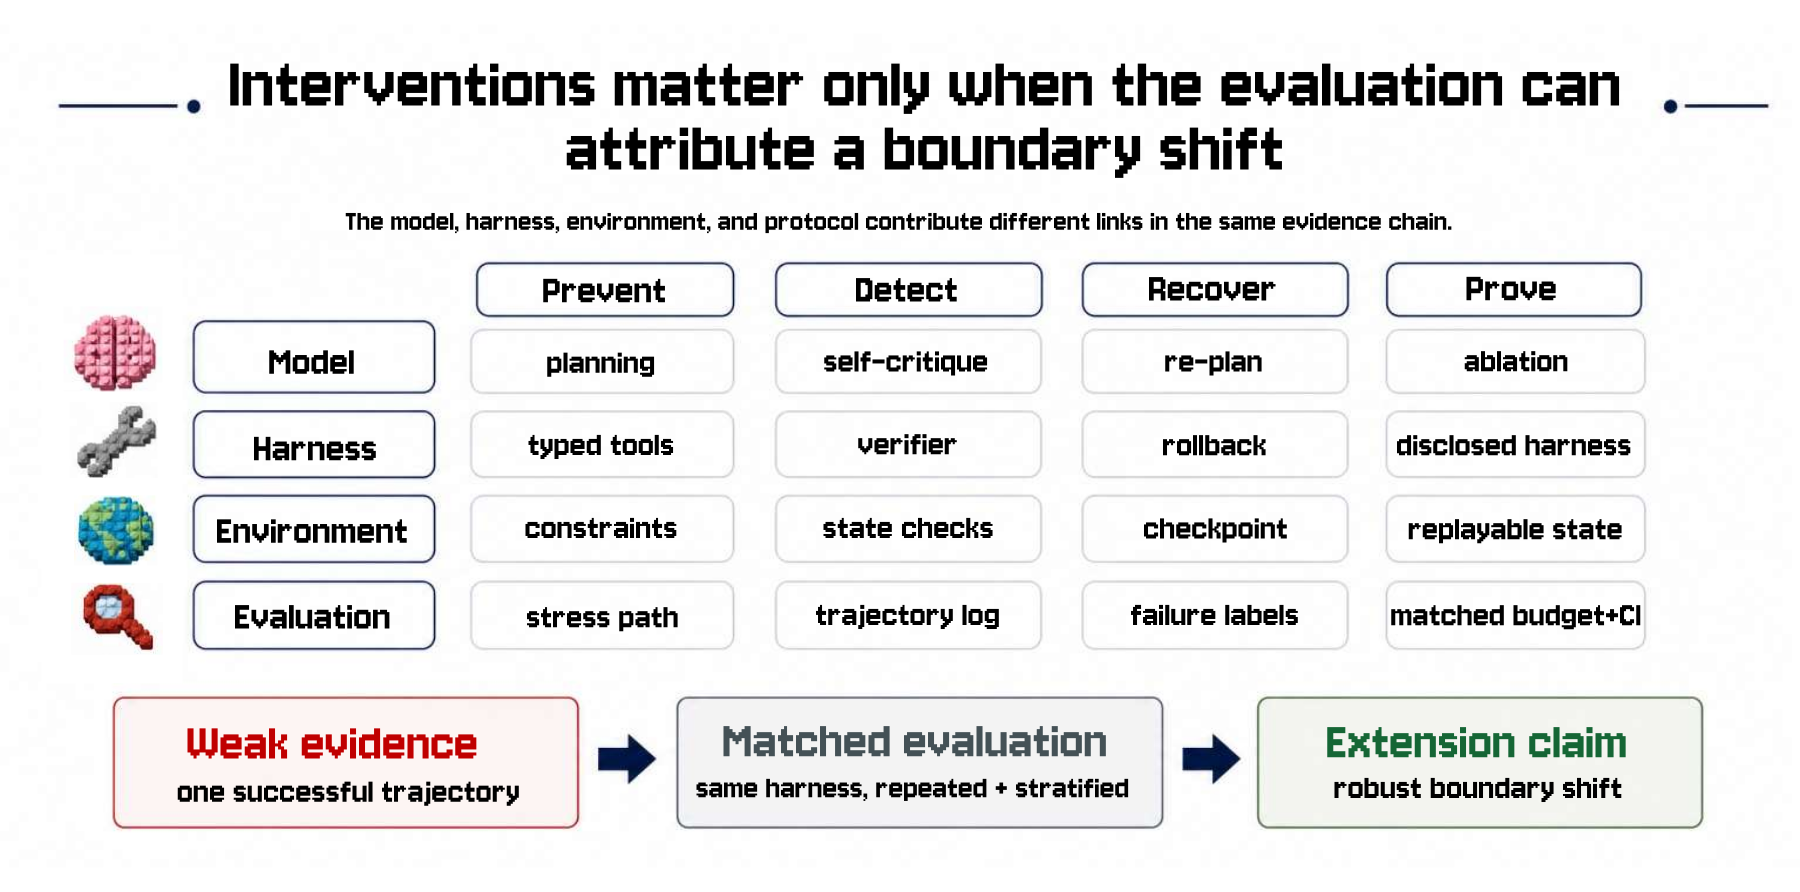
Evidence chain for reliable harness interventions

596 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

Paper Date Citations Code
Optimize the Harness, Not the Model: Fitting a Minimal Agent to a Self-Hostable LLM for Investigative Analysis
arXiv
2026-11 — —
Can We Stop the Backtest Yet? Anytime-Valid Promotion Tests for Adaptive Financial Research Agents
arXiv
2026-11 0 —
ScienceCUA: Resource-to-Skill Construction and Execution-Guided Skill Evolution for Scientific Computer Use Agents
arXiv
2026-11 — —
Auto-Research Agent on MSA Organization to Improve Protein-Protein Complex Structure Prediction
arXiv
2026-11 — —
CARE: Grounded Recursive Self-Improvement for Production Customer-Service Agents
arXiv
2026-11 — —
GeoGuesser Bench: Benchmarking Vision-Language Agents on Interactive Geolocation
arXiv
2026-11 — —
Strategist: Evolving Reasoning with Agents
arXiv
2026-11 — —
DiabAgent: Toward Agentic Physiological Control
arXiv
2026-11 — —
FedReady: Bounded Agents for Federation Formation
arXiv
2026-11 — —
An Agentic Framework for Automated Power System Studies and Grid Connection Assessment
arXiv
2026-11 — —
Top-$k$ Retrieval Leaves Memory Value Undetermined
arXiv
2026-11 — —
CoworkOS:Scaling Agent Coworkers for Real-world Automation
arXiv
2026-11 — —
ComplianceAtlas: A Taxonomy-Driven Agentic AI Framework for Automated AI Act Gap Analysis and Remediation
arXiv
2026-11 — —
Action Verification through Conjecture and Refutation for Language Model Agents
arXiv
2026-11 — —
RxnMiner: A Multimodal Agent for Structured Reaction Data Extraction from Chemistry Figures
arXiv
2026-11 — GitHub · ★ 4
Predictive Safety Guardrails Do Not Always Make LLM Agents Safer
arXiv
2026-11 — —
Cumulative and Audited Guardrail Tool Evolution for LLM Agent Safety
arXiv
2026-11 — —
MAGAR: Multimodal Agents for GUI-Based 3D Mechanical Assembly and Minimal Rework
arXiv
2026-11 — —
RecGroupMemory: Feedback-Aware Cohort Memory for E-Commerce Recommendation
arXiv
2026-11 — —
LEANGUARD: Lean-Verified Guardrails for Tool-Using Agents
arXiv
2026-11 — —
Can Coding Agents Sustain Continual Evolution without Forgetting?
arXiv
2026-11 — GitHub · ★ 0
Math Foundation Formalization Agent: A General-Purpose Approach to Formalizing Mathematical Foundations
arXiv
2026-11 — —
Discovering hierarchical governing equations for community-structured complex network dynamics with LLM agents
arXiv
2026-11 — —
IssueLighter: An Issue Type-Aware LLM Agent for Issue Report Validity Assessment
arXiv
2026-11 — —
Scalaris: A Scalable Enterprise Memory Architecture for Conversational AI Assistants
arXiv
2026-11 — —
StateFence: Task-State Protection Against Evidence-Chain Contamination in Blue-Team LLM Agents
arXiv
2026-11 — —
Chain on Demand: Deferred Evidence Organization for Long-Term Conversational Memory
arXiv
2026-11 — —
Late Autumn: LLM Agents Specialize a General Multi-Robot Planner for One Warehouse
arXiv
2026-11 — —
AgiWorld: An Agentic Video World Model for Building Persistent Worlds
arXiv
2026-11 — —
MemShift: Separating Detection from Repair in LLM-Derived Personal Memory
arXiv
2026-11 — GitHub · ★ 1
VeriHarm-Bench: Measuring Harmful Success in LLM Coding Agents Verifiably
arXiv
2026-11 — —
ACTOR: Action-Centered Temporal Organization for Literary Role-Playing Agents
arXiv
2026-11 — GitHub · ★ 5
A State Change Is Local, Its Consequences Are Not: Dependency-Aware State Revision for Long-Term Agent Memory
arXiv
2026-11 — —
ParetoSaddler: Pareto-Guided Optimization of Agent Harnesses for Quality and Cost
arXiv
2026-11 — Project
Self-Evolving Agentic Workflows via Semantic Decomposition of Complex Tasks
arXiv
2026-11 — GitHub · ★ 0
CONFIRM: Governing Scientific Reporting for Trustworthy Agentic Neuroimaging
arXiv
2026-11 — —
A Self-Exploring and Self-Evolving Paradigm for Adaptive Edge AI Development
arXiv
2026-11 — —
Towards Self-Evolving Narrative Systems: Real-Time Adaptation and Long-Term Optimization with LLMs
arXiv
2026-11 — —
Latent Harness: Compiling Agent Behaviors into Post-Block Activation Shifts
arXiv
2026-11 — —
Decoupled Predictive Decision Making: A Shared Conditional Predictor for Agents
arXiv
2026-11 — —
NEIGHBOR: Aligning Service Behaviour and Evidence Use in an LLM Agent for Community Resident Services
arXiv
2026-11 — —
Delivered, Not Used: Evaluating Agent Memory at Its Point of Use
arXiv
2026-11 — —
Just-in-Time Skill Retrieval via Long-Horizon State Tracking
arXiv
2026-11 — —
MemHarmBench: Evaluating Cross-Session Prompt Injection in Memory-Persistent AI Agents
arXiv
2026-11 — GitHub · ★ 3
\textsc{ChatDify}: Automating End-to-End Dify Workflow Synthesis from Natural Language via Multi-Agent Collaboration
arXiv
2026-11 — —
I-PTC: Interactive Programmatic Tool Calling for Stateful Tool-Augmented Agents
arXiv
2026-11 — —
Learning by Doing: Autonomously Compiling and Curating Agent Skills from Verified Traces
arXiv
2026-11 — —
Qubrio: High-Performance Quantum Compilation via Multi-Agent LLM Collaboration
arXiv
2026-11 — GitHub · ★ 2
Beyond Prompt Injection: The Tool Update Gap in LLM Agent Security
arXiv
2026-11 — —
Step-Zero Attack: Agent Safety Before Observability
arXiv
2026-11 — —
RECEIPT: Measuring and Repairing the Return Assumption of LLM Agents in Web Service Operations
arXiv
2026-11 — —
AgenticMobility: An Open-Source Platform for Multi-AI-Agent Mobility Dynamics
arXiv
2026-11 — —
MemRole: From Memories to Decisions for Long-Horizon Reasoning in Role-Playing Agents
arXiv
2026-11 — —
Evolving Memory, Learning to Meta-Control: Test-Time Adaptation for Experience-augmented LLM Agents
arXiv
2026-11 — —
Principled Human-AI Collaboration in Agentic Workflows
arXiv
2026-11 — —
An auditable agentic pipeline for variant-to-gene prioritisation, validated against orthogonal functional evidence
arXiv
2026-11 — —
Can Large Language Model Agents Learn by Watching Tutorial Videos?
arXiv
2026-11 — —
ERIA: An Instruction-Optimized Agent for Clinical EEG Reporting
arXiv
2026-11 — —
Decision Models as Policy Gates for Coding Agents: Explicit Policy Boundaries Improve Detection and Reduce False Alarms
arXiv
2026-11 — GitHub · ★ 1
Multi-Agent Collusion and the J-Space
arXiv
2026-11 — —
Can Large Language Models Extend Their Agentic Capabilities to Goal Pursuit in Open-Ended Multi-Turn Interaction?
arXiv
2026-11 — —
When Should an Agent Refresh? Adaptive Index Reuse for Efficient Long-Horizon Reasoning
arXiv
2026-11 — —
Designing Informative Actions: Action Construction for Long-Horizon Research Agents
arXiv
2026-10 — —
Auriga Technical Report: A Task-Agnostic Agent Harness for Zero-Shot Embodied Manipulation
arXiv
2026-10 — GitHub · ★ 22
When LLMs Modify Themselves: Convergence, Values, and Stopping in Iterative Self-Improvement
arXiv
2026-10 — —
CivicBench: A Benchmark and Memory Framework for Web-Based Civic Data Analytics
arXiv
2026-10 — —
Constraint Dependency Graph Retrieval for Compliance Detection on Long SKILL Documents
arXiv
2026-10 — —
GURU: A Hierarchical Neuro-Symbolic Multi-Agent System for Verification-Aware Automation of Mission-Critical Digital Engineering and Operations
arXiv
2026-10 — —
Can Agentic AI Undermine Its Own Assurance Loop? Closed-Loop Dependency Assurance for Cognitive Network Digital Twins
arXiv
2026-10 — —
Who Schedules Agent Memory? A Sidecar Approach to Long-Horizon Tasks
arXiv
2026-10 — —
FastAgent: A Physics-Aware FastFluent-to-Fluent Workflow for Rapid CFD Screening and Industrial Steam Dewaxing Design
arXiv
2026-10 — —
Autonomous Analysis of Thermoelectric Materials Big Data by Multi-Agentic AI and Construction of a Knowledge Base and Specialized AI
arXiv
2026-10 — —
Skill++: Towards Lifelong Agents via Routing-Aware Skill Refinement
arXiv
2026-10 — —
Agentic Context Management for Multi-Turn Human-AI Conversations
arXiv
2026-10 — —
The Verifier Is Part of the Simulator: Evidence-View Gaming in Agentic Equation Discovery
arXiv
2026-10 — GitHub · ★ 1
Toward Bounding Coding-Agent Autonomy in Software Maintenance: A Pilot Study of Boundary Contracts
arXiv
2026-10 — —
Dependable Agents Need Hard and Fuzzy Rules
arXiv
2026-10 — —
Illusion: Safeguarding Topology Confidentiality in LLM Multi-Agent Systems via Behavior-Preserving Obfuscation
arXiv
2026-10 — —
Agent4FreeFem: A Verification-Guided Framework for Autonomous Topology Optimization
arXiv
2026-10 — —
Old Is Not False: Valid-Time Memory for Interactive Video World Models
arXiv
2026-10 — —
Getting a Grip: Operating Human-Agent Software Teams Through Governed Messages
arXiv
2026-10 — —
Discovering Models for Experimental Quantum Systems with Agentic AI
arXiv
2026-10 — —
CompSkill: Compiling Execution Experience for Skill Retrieval
arXiv
2026-10 — GitHub · ★ 0
When 200 OK Is Not an Answer: Silent Fetch Failures in Agentic Web Content Acquisition
arXiv
2026-10 — —
Exo: An Architecture for Self-Improving Systems at Runtime
arXiv
2026-10 — —
MemU-Bench: Benchmarking GUI Agents on Long-Horizon User Interactions
arXiv
2026-10 — —
Agent Stack for ML Training Lifecycle: Generation, Validation, and Optimization
arXiv
2026-10 — —
TradeWar: A Benchmark for Execution-Grounded Trade Negotiation with Adaptive LLM Agents
arXiv
2026-10 — —
EvoMCP: Co-evolving MCP agents and training data
arXiv
2026-10 — GitHub · ★ 0
From 1D Benchmarks to Complex 3D Geometries: Can Agents Reliably Specify Problems for Automated PDE Simulation?
arXiv
2026-10 — —
MEMIG: Self-evolving Memory Construction for Antibody Optimization
arXiv
2026-10 — —
ANGLER: Verifier-Grounded Benchmarking with an Adaptive Attacker for Web Agents
arXiv
2026-10 — —
Context as Infrastructure: Knowledge Compilation for Retrieval in Agentic Systems with Harnesses
arXiv
2026-10 — GitHub · ★ 93,418
Dependence-Aware Risk Assessment and Optimal Design of AI-Agent Safeguard Systems
arXiv
2026-10 — —
Taurus: LLM-in-the-Loop CT Annotation Matches Coding Agents at Half the Cost
arXiv
2026-10 — —
Fidelity Collapses with Table Size, Not Turn Count: Delivery Architecture in a Deployed Tool-Using Agent
arXiv
2026-10 — —
SPARK: Self-Correcting Embodied Memory via Physical Re-Observation
arXiv
2026-10 — —
Structure-Aware Skill Retrieval and Arbitration for Optimization Modeling
arXiv
2026-10 — —
Learning to Interact and Direct: Co-Evolving Video Director Agents
arXiv
2026-10 — —
Real Computation or Merely Naming? A Pre-Registered Mechanism Audit of 25 Cognitive-Architecture Modules in an LLM-Based Agent System
arXiv
2026-10 — —
Verify--Backtrack Loop: Structured Precondition Recovery for Long-Horizon Language Agents
arXiv
2026-10 — —
Evidence-Guided Recovery for AI Agents with Ambiguous Tool Outcomes and Partial Execution
arXiv
2026-10 — —
Cross-Interface Authorization for AI Computer-Use Agents
arXiv
2026-10 — —
Ask on Demand: Targeted Peer Communication for Parallel Agentic Systems
arXiv
2026-10 — —
Operon-S1: a fast decision controller for long-horizon biomedical agents
arXiv
2026-10 — —
When Should AI Agents Ask? Clarification Requests Under Limited Human Attention
arXiv
2026-10 — —
RoboArchitect: Automating the Design of Robotic Agents with Persistent Memory
arXiv
2026-10 — Project
KEEPER: Learning Control-Sufficient Textual Memory for Long-Horizon LLM Agents
arXiv
2026-10 — —
When Safety Checks Become Privacy Risks: A Privacy-Preserving Paradigm for LLM Agent Safety Auditing
arXiv
2026-10 — —
ART of PIV: Agentic Real-Time Particle Image Velocimetry for Active Flow Control
arXiv
2026-10 — —
Lineage Is Memory: Parent Inheritance and Feedback Disclosure in Short-Budget LLM-Guided Optimization
arXiv
2026-10 — GitHub · ★ 1
MEMENTO: Learning Context Management for Long Context Processing Agents
arXiv
2026-10 — —
TraceSpec: Understanding and Improving Speculative Decoding for LLM Agents
arXiv
2026-10 — —
Completeness and Cost of Retrieval Structures for Multi-Tool Requests in LLM Agents
arXiv
2026-10 — —
Hybrid Computer Use: A Unified Programmatic, Semantic, and Visual Interface for General Agents
arXiv
2026-10 — —
Towards Portable Specification of the Agent Harness
arXiv
2026-10 — —
TSFLab: A Self-Improving Agent-Agnostic Workbench for Time Series Forecasting Research
arXiv
2026-10 — GitHub · ★ 65
MetaVul: Agentic Harness Discovery for Vulnerability Detection
arXiv
2026-10 — —
Collaborative AI agents for autonomous experimental research with solid-state quantum spins
arXiv
2026-10 0 GitHub · ★ 12
KARMA: Training-Free Knowledge-Atomic Harness Evolution for Industrial Advertising Agents
arXiv
2026-10 0 —
MoLRSI: A Recursive Self-Improving AI agent for Molecular Discovery
arXiv
2026-10 0 —
Letting AI Formulate the Research Question: Autonomous Research Agents
arXiv
2026-10 0 —
From Intent to Improvement: Agentic Dataset Search for Better Model Training
arXiv
2026-10 0 GitHub · ★ 2
Compile Away Uncertainty: Self-Evolving Agent Skills via Programmatic Compilation
arXiv
2026-10 0 —
HEMO: Harness Self-Evolution for Multi-Objective Combinatorial Optimization
arXiv
2026-10 0 —
Sandman: A Sandbox Service for Production Agentic Reinforcement Learning
arXiv
2026-10 — —
Well-Specified and Well-Tested? Assessing SWE-bench-Style Datasets with a Self-Evolving Agent
arXiv
2026-10 0 —
Appreciation Teaches Unauthorized Execution: Self-Evolution Degrades the Robustness of Personal Agents to Indirect Prompt Injection
arXiv
2026-10 0 GitHub · ★ 2
Mage-VL-Cowork: A Full Training Recipe to Learn Hybrid Computer Use From Evolved Harnesses
arXiv
2026-10 — Project
How Specific Do I Need to Be? Effects of User Query Underspecification on Deep Research Agents
arXiv
2026-10 0 —
LanG 2.0: Energy-Efficient Agentic AI for Semi-Automated Security Operations at Scale
arXiv
2026-10 — —
Capability-Grounded Agentic Planning
arXiv
2026-10 — —
Agentic World Modeling for Agent Test-time Scaling without Environment Replica
arXiv
2026-10 — —
Does Recursive Knowledge Construction Help Agents Verify Consensus Claims in Science?
arXiv
2026-10 — —
Accept Changes, Reject Attacks: Robust Memory Management for LLM Agents
arXiv
2026-10 — —
"Shall We Approve?" Consequence-Aware Approval for Autonomous Coding Agents
arXiv
2026-10 — —
PrivacyFlow: Privacy in AI Agents through Information Flow Analysis and Consequence-Aware Risk Management
arXiv
2026-10 — —
Pre-Crime for Agents, at the Last Second: Probing When a Recruited Agent Gives In
arXiv
2026-10 0 GitHub · ★ 1
VeriCUA: Verification as Agentic Exploration for Computer-Using Agents
arXiv
2026-10 0 —
Advancing Clinical Genomic Analysis with a Skill-Centred Agent
arXiv
2026-10 0 —
Retrieval as Traversal: Value-Indexed Memory for Stateful Long-Context Agents
arXiv
2026-10 0 —
FIRME: Registry-Anchored Memory Graphs for Evolving, Heterogeneous Investor Knowledge
arXiv
2026-10 0 —
EpiAgent: Epistemic Self-Play for LLM Agents
arXiv
2026-10 0 —
Locating and Closing Information Gaps in Multi-Agent Systems
arXiv
2026-10 0 —
Agentic process evidence
arXiv
2026-10 0 —
EvoTeam: Multi-Agent Collaboration via Evolving Teams
arXiv
2026-10 0 GitHub · ★ 2
Long-Term Agent Memory through Complementary Curation and Consolidation
arXiv
2026-10 0 —
Before the Next Rollout: Diagnosing Skill Utility Shifts from Policy Updates
arXiv
2026-10 0 —
What Does "Now" Mean to Your Computer-Use Agent? Stale Screenshots, Page Loads, and Which Check to Run Before a Click
arXiv
2026-10 0 GitHub · ★ 0
MemSteer: Turning User Histories into Supervision for Agent Memory Optimization
arXiv
2026-10 0 —
Goal-Aware Dynamic Multi-Agent Collaboration for Long-Horizon Tasks
arXiv
2026-10 0 —
From extreme weather to agricultural consequences with agentic AI
arXiv
2026-10 0 —
When to Assist and What to Suggest: Joint Gating and Memory-Grounded Hint Generation in One Compact Decoder
arXiv
2026-10 0 —
Gym-Anything for Robotics: Scaling physical simulations with digital agents
arXiv
2026-10 0 Project
The Athlete as a Scientist of One: Agentic Bayesian Experimental Design for Individualized Physiology from Consumer Wearables
arXiv
2026-10 0 —
TaskFrame: Connecting Task-Level Planning with Frame-Level Control for Game Agents
arXiv
2026-10 0 —
Learning Calibrated Confidence for Multi-Agent Collaboration
arXiv
2026-10 0 —
Practical Assessment of Agentic Systems in Acoustics
arXiv
2026-10 0 —
Can AI Agents Interface Clinicians and Complex Models?
arXiv
2026-10 0 —
LLM Agent-Based Design of RISC-V CPUs with FPGA-in-the-Loop Evaluation
arXiv
2026-10 0 GitHub · ★ 5
Judging Before Propagation: Task-Graph Contextual Integrity for Multi-Agent Privacy
arXiv
2026-10 0 —
Soei: Structured Observability of Evidence and Intent for Multi-Agent AI Software Engineering
arXiv
2026-10 0 —
OPERA: OPamp Design by an Expert-Taught Reasoning Agent, from Specifications to Layout
arXiv
2026-10 0 GitHub · ★ 0
Learning to Formulate: Agentic Hardware-Software Co-Design of AI Infrastructure through Progressive Optimization and Verification
arXiv
2026-10 0 —
EmbodiExp: Compositional Experience Transfer for Embodied Agents
arXiv
2026-10 0 —
REALM: Identifying Minimal Task Assets for LLM Agents
arXiv
2026-10 0 —
PCM: A Proof-Carrying Message Protocol for Verifiable Multi-Agent Communication
arXiv
2026-10 0 GitHub · ★ 37
HERA: Assessing an Autonomous Agent for Quantum Device Measurement
arXiv
2026-10 0 GitHub · ★ 0
Don't Lose the Thread: Empowering Long-Horizon LLM Agents with Cognitive Resource Self-Allocation
arXiv
2026-10 0 —
Agentic LLM reasoning in pediatric diabetes outcome prediction from multimodal medical records
arXiv
2026-10 0 —
AgentHeal: Evaluating Goal-Preserving Resource Recovery of Web Agents under Access Barriers
arXiv
2026-10 0 GitHub · ★ 1
Aligning Autoresearch: Co-Improvement between Agents and Humans
arXiv
2026-10 0 —
Beyond fabrication: Misattributed numbers in papers written by AI research agents
arXiv
2026-10 0 GitHub · ★ 0
Masked Erosion: How Acceptance Gates Lose Redundant Safeguards in Self-Improving Agents
arXiv
2026-10 0 —
SkillCT: A Multidimensional Benchmark and Execution-Free Baseline for Agent Skill Assessment
arXiv
2026-10 0 —
MAS-Loop: Beyond One-Shot Orchestration towards Self-Evolving Multi-Agent Systems
arXiv
2026-10 0 —
MUSE: Multi-Level Memory with Selective Runtime Injection for Scientific Coding Agents
arXiv
2026-10 0 GitHub · ★ 1
Implicit Minor Detection from Multi-Turn Dialogue in High-Risk AI Interactions: A Constrained Self-Evolving LLM Harness
arXiv
2026-10 0 —
Efficient Agentic Audio-Visual Question Answering through Toolset Pruning and Modality Consolidation
arXiv
2026-10 0 —
Auditable Belief Updates as a Missing Safety Layer for LLM-Powered Multi-Agent Systems
arXiv
2026-10 0 —
Think Before You Act: Decision Gate for LLM Agents
arXiv
2026-10 0 —
CALM: Conflict-Aware Lifecycle Memory Governance for Long-Horizon Language Agents
arXiv
2026-10 0 —
Predict the Reward, Not the World: World Reward Models for ML Agents
arXiv
2026-10 0 —
Agent Transfer Protocol: Server-Mediated Agent-to-Agent Communication Architecture for the Agentic Web
arXiv
2026-10 0 —
FACTS-MAS: A Multi-Agent Architecture for Adaptive Forecasting from Heterogeneous Evidence
arXiv
2026-10 0 GitHub · ★ 1
Autonomous Quantum Measurement with Agentic AI
arXiv
2026-10 0 —
Tracekit Box: Running AI Agents in Micro-VMs Where Every Way Out Is Decided and Signed
arXiv
2026-10 0 GitHub · ★ 42
The Code Behind the Layout: AI Agents for Analog Layout Generators
arXiv
2026-10 0 —
WeVisCut: The Whole Editing Room in One Agent From Narration to Long-Form Video
arXiv
2026-10 0 —
A Case Study of a Multi-Agent Kernel-Optimization Loop That Learns a New AI Accelerator
arXiv
2026-10 0 GitHub · ★ 1
What Should a Navigator Remember? Spatiotemporal Memory for Zero-Shot Vision-Language Navigation
arXiv
2026-10 0 —
Skeleton Coding: Program Structure as a Specification for Agents
arXiv
2026-10 0 —
Is it my preference? Role Grounding Attack against Agent's Memory via Social Interaction
arXiv
2026-10 0 —
HEDGE: Gated Hypergraph Memory for Scalable Multi-Agent Debate
arXiv
2026-10 0 —
CoSTA: Co-Evolving Self-Play Timeline Agents for Complex Temporal Knowledge Graph Question Answering
arXiv
2026-10 0 —
Two Birds with One Stone: Skill-Augmented Generation via Unified Retrieval and Utilization
arXiv
2026-10 0 —
Repairs for Whom? Evaluator-Executor Mismatch in Selecting Repairs for Failed LLM Agents
arXiv
2026-10 0 —
GARDEN: Generalist Autonomous Reward Design Through Evidence Navigation for Cooperative Multi-Agent Reinforcement Learning
arXiv
2026-10 0 GitHub · ★ 0
VerifiedLab: Harnessing Knowns for Unknowns
arXiv
2026-10 0 —
Constraining the Commit Boundary: A DIO/ODI-Informed Authorization Guardrail for Agentic Entity Resolution
arXiv
2026-10 0 —
RubricAtlas: Mining Type-Level Rubrics from Expert Reports to Evaluate Deep Research Agents
arXiv
2026-10 0 —
When the Critic Falls Behind: Co-Evolving Rubrics and Harnesses for Continual Agent Self-Improvement
arXiv
2026-10 0 —
NextEval: An Agent-Based Solver and Benchmark for Derivative-Free Optimization
arXiv
2026-10 0 —
GEPA-Curator: Curated Learning for Self Improving Agents
arXiv
2026-10 0 —
A Harness Reducing over-Defensive Writing in Agents by Isolating Objections
arXiv
2026-10 0 —
Benchmarking Task Takeover Across Agent Handoffs
arXiv
2026-10 0 —
Your Policy Is Secretly a Harness: The Decision Geometry of Agent Interfaces
arXiv
2026-10 0 GitHub · ★ 1
SkillMem: Compact External Skill Memory for Latent Multi-Agent Reasoning
arXiv
2026-10 0 —
FilingLoop: Evaluating and Evolving LLM Agents for Corporate Disclosure Review and Revision
arXiv
2026-10 0 —
Evaluating and improving AI agents for sequencing protocol understanding
arXiv
2026-10 0 —
Detecting Covert Collusion between AI Agents through Partner-Outsider Positive Listening
arXiv
2026-10 0 —
Measuring Where Intent Gets Lost in Agentic Smart Contract Synthesis
arXiv
2026-10 0 —
What Does an Ontology Catch? Curated, LLM-Generated and Data-Derived Ontologies as Checkers of LLM Agents over Knowledge Graphs
arXiv
2026-10 0 —
WebAnything: From the Wild Web to Scalable Agent Environments
arXiv
2026-10 0 GitHub · ★ 6
Scan Before You Install: Detecting and Mitigating Local and Composite Vulnerabilities in Skills
arXiv
2026-10 0 —
Poisoned Skills: Propagating Jailbreaks Through Agent Markdown Files
arXiv
2026-10 0 —
When Skills Tell Agents Not to Ask: A Large-Scale Study of Oversight Directives in Agent Skills
arXiv
2026-10 0 —
Rare, Relevant, and Still Wrong: How Memory Fails LLM Group Decisions
arXiv
2026-10 0 —
From Interaction to Capability: Task Advancement as State and Supervision for GUI Agents
arXiv
2026-10 0 —
Concordat: Typed Sessions for LLM Agents
arXiv
2026-10 0 GitHub · ★ 2
M4Bench: Evaluating Procedural Specification for Clinical EHR Derivation Agents
arXiv
2026-10 0 GitHub · ★ 49
Agent-Conditioned Routing: Diverse Reasoning Paths Within One Frozen Model
arXiv
2026-10 0 —
Grounding LLM Agents in Business Processes: Process-Aware Knowledge Graphs for Reliable Multi-Step Service Invocation
arXiv
2026-10 0 —
Does Your Generalist Skill Optimizer Really Incentivize Agentic Tasks? Rethinking Skill Optimization via Bipartite Attribution
arXiv
2026-10 0 GitHub · ★ 4
Proactive Memory for Event-Driven LLM Agents
arXiv
2026-10 0 Project
Evolving Agent Teams
arXiv
2026-10 0 GitHub · ★ 61
Beyond the Evidence Coherence Trap: Agent-Driven Evidence Selection for Temporally Disordered Fake News Detection
arXiv
2026-10 0 —
The View from Nowhere: Population-Centered Agent Evolution
arXiv
2026-10 0 —
Remembering Is Not Enough: Refining Memories and Learning When to Use Them in Multi-Agent Systems
arXiv
2026-10 0 —
God Does Not Play Dice: Enforcing Batch Invariance in Agentic Kernel Generation
arXiv
2026-10 0 —
CASEL: Consequence-Aware Selective Execution for Reliable Long-Horizon Tool-Using Agents
arXiv
2026-10 0 —
Monitor Accuracy Isn't the Answer: A Decision-Value Framework for Evaluating AI Agent Restart Monitors
arXiv
2026-10 0 —
When to Intervene? An Empirical Study of Errors and Self-Recovery in LLM Agents
arXiv
2026-10 0 Project
RouteDRAG: Learning to Route and Control Agentic Execution for Multimodal Document RAG
arXiv
2026-10 0 GitHub · ★ 2
Gym-Anything-RT: Scaling Real-Time Environments for Vision-Language Agents
arXiv
2026-10 0 —
Test-Time Communication in Trading Agent Swarms
arXiv
2026-10 0 —
AnalogScout: Simulation-Efficient PVT-Aware Analog Sizing with LLM Agents
arXiv
2026-10 0 —
Where Should the Evaluation Budget Go in LLM-Driven Agent Scaffold Evolution?
arXiv
2026-10 0 —
Spine: Compiling Subtask Trees into Structured Context for Long-Horizon Coding Agents
arXiv
2026-10 0 —
Blindfold: Keeping the Audit Coin Secret from LLM Agents
arXiv
2026-10 0 —
Beyond QASecClaw: Agent Scaling, Verifier Feedback, and Evidence Reliability in Software Assurance
arXiv
2026-10 0 —
From Voiceprints to User Entities: Online Speaker-Memory Construction for Multi-User Spoken Agents
arXiv
2026-10 0 —
Metacognitive Decoding: Efficient Inference for Diffusion Language Agents
arXiv
2026-10 0 —
ETAMem: Decoupling and Aligning Heterogeneous Memory for Long-Term Conversational Agents
arXiv
2026-10 0 —
TrawMem: Reframing Agent Memory as Task-Oriented Role-Adaptive Workspaces
arXiv
2026-10 0 —
DocSkill: Skill-Integrated Agentic Reasoning for Multilingual Multi-Hop Document Question Answering
arXiv
2026-10 0 —
The Trinity: Capability-Driven Recursive Self-Improvement for Multimodal Agents
arXiv
2026-10 0 —
Context Is a Pipeline, Not a Window: Information Attrition in LLM Agent Harnesses
arXiv
2026-10 0 —
Free to Look, Free to Reason: Simple LLM Harnesses Outdiagnose Hand-Crafted Root Cause Analysis Agents
arXiv
2026-10 0 —
Infinity Machine: a self-improving AI agent for research
arXiv
2026-10 0 —
Skill$^{\infty}$: Recursive Self-Improvement for Agent Skill Optimization
arXiv
2026-10 0 GitHub · ★ 6
RSIV-Harness: A Recursive Self-Improvement Harness Framework for Open-Domain Conversational Text-to-Visualization
arXiv
2026-10 0 —
The Right Fact, the Wrong Decision: SciValidityBench for Scientific Agent Memory
arXiv
2026-10 — —
Harness-Model Collaboration for Long-Horizon Continual Learning
arXiv
2026-10 0 —
Profiling a Frontier Agent with EBench: From Direct Control to Harness with Policy
arXiv
2026-10 0 Project
MarkovSim: an LLM Agent Harness with Bounded Context for Long-Horizon Computational Simulation
arXiv
2026-10 0 —
The Target Agent Is Its Own Best Critic but a Poor Proposer: Self-Improved Red Teaming
arXiv
2026-10 0 —
How Do Coding-Agent Harnesses Self-Evolve? An Empirical Study of Retrospective Adaptation
arXiv
2026-10 0 —
The Physical Cost of Context: Quality-Constrained Resource Accounting for Coding Agents
arXiv
2026-10 0 —
Quantifying Claim Smoothing by LLM Research Agents
arXiv
2026-10 0 GitHub · ★ 0
OA-RAG: Ontology-based Agentic RAG for Faithful LLM Reasoning
arXiv
2026-10 0 —
Ontology-guided multi-agent reasoning for explainable differential diagnosis
arXiv
2026-10 0 —
When Retrieval Is Not Enough: Obsolete Facts in Agent Memory
arXiv
2026-10 0 —
Skill Dreaming: Evolving Repository Skills through Pull Request Streams
arXiv
2026-10 0 —
CohortFlow: A Steerable Clinical Cohort Curation Agent with Localized Semantic Correction
arXiv
2026-10 0 —
Stratum: Repository Memory for Coding Agents Beyond the Context Window
arXiv
2026-10 0 —
Replication or Corroboration? An Axiomatic Framework for Evidential Dependence in Multi-Agent Debate
arXiv
2026-10 0 —
When Connectivity Misleads: Guiding Agentic Search with Contrastive Evidence Paths
arXiv
2026-10 0 —
Log-To-Leak: Prompt Injection Attacks on Tool-Using LLM Agents via the Model Context Protocol
arXiv
2026-10 0 —
Do Coding Agents Still Need a Debugger? Frontier-Model-Based Fault Localization at the Accuracy Ceiling
arXiv
2026-10 — —
PolicyMediator: Multi-Regional Policy Learning through Mediation Agents with Evolving Skills in OPC Ecosystems
arXiv
2026-10 0 —
Generation and Verification: Human-Agent Collaboration for Safety-Critical Automotive Software Engineering
arXiv
2026-10 0 —
EvoRouter: Cost-Efficient Multi-Agent Routing via Insight-Guided On-Policy Distillation
arXiv
2026-10 0 GitHub · ★ 5
Agentic Algorithm Design: LLMs that Propose, Formalise, and Prove Runtime Bounds for Evolutionary Algorithms in Lean
arXiv
2026-10 0 —
Belief-Conditioned Multi-Agent Actor Critic for Decentralized LLM Collaboration
arXiv
2026-10 0 —
Proof-of-Agentness: Towards Verifying Agents on the Web
arXiv
2026-10 0 —
AutoEnergyDesign: An LLM-Driven Agent for Automatic Energy System Design Optimization
arXiv
2026-10 0 —
LongSearchEval: Evaluating Long-Horizon Web Search Capabilities of Large Language Models via a Trajectory-Aware Agent Framework with Failure-Node Localization
arXiv
2026-10 0 —
Collective Emergent Alignment: Measuring and Amplifying Interaction-Induced Reasoning Alignment in Multi-Agent LLMs
arXiv
2026-10 0 —
Scope-Gap Injection: Exploiting Evaluator Channel Blind Spots in the OpenClaw Agent Security Competition
arXiv
2026-10 0 —
SKALOS: Learning to Distinguish Similar Skills with Capability Graphs
arXiv
2026-10 0 —
CEPO: A General Framework for Improving Prompt Optimization in Multi-Agent Systems
arXiv
2026-10 0 —
KAPPA: Checking the Proofs in Statistics Papers with Lean 4 and Language Model Agents
arXiv
2026-10 0 GitHub · ★ 11
The Hidden Costs of Forgetting: A Study of Trajectory Deletion in Software Engineering Agents
arXiv
2026-10 0 —
Autonomous Structural Discovery Of Bioprocess Dynamics And Kinetics Via LLM-Driven Agents
arXiv
2026-10 0 —
RepoTrace: Improving Requirement Tracing in Multi-Round Agent Interactions
arXiv
2026-10 — —
Joint Latent Reasoning and Observation for Agentic Video Understanding
arXiv
2026-10 0 —
CoSA: The Conflict of Skills Attack in Real-World LLM Agent Ecosystems
arXiv
2026-10 0 —
AskGLP1: A Knowledge Graph LLM Agent for Exploring GLP-1 Experience from Online Patient Narratives
arXiv
2026-10 0 GitHub · ★ 2
GUIFlow: Temporal Redundancy-Aware Incremental Inference for GUI Agents
arXiv
2026-10 0 —
AIPC: Evidence-Guided Agent Workflows for PyTorch Project Deployment
arXiv
2026-10 0 —
Adaptive Retrieval, Selective Answers: Evaluating Conformal Factuality in Agentic RAG
arXiv
2026-10 0 GitHub · ★ 0
Silent and Costly: Characterizing and Detecting Prompt-Caching Mis-Integration in LLM Agents
arXiv
2026-10 0 —
SceneAgent: An Agentic Pipeline from 3D and 4D Captures to Simulation Environments
arXiv
2026-10 0 —
Agent Memory as Recommendation: Recommender-System Design for Long-Term Memory of LLM Agents
arXiv
2026-10 0 —
Thinking-in-Bets at Test Time Reduces Sycophantic Revisions in LLM Agents
arXiv
2026-10 0 Project
Agentic Systems for Calibrating Cosmological Simulations
arXiv
2026-10 — GitHub · ★ 0
OmniBrain-0: A Unified Agentic Model for Embodied Intelligence
arXiv
2026-10 0 Project
Hierarchical Skill Evolution for Coding Agent
arXiv
2026-10 0 —
From Questions to Queries to Insights: A Schema-Grounded Agentic Workflow for Natural-Language Crash Data Analysis
arXiv
2026-10 0 —
Semantic Atoms for Scalable Text Analysis in Data Analytics in the Era of LLM-Based Agents
arXiv
2026-10 0 —
BehaviorMem: Building and Evaluating User Memory from Real-World E-Commerce Behavior Streams
arXiv
2026-10 0 —
Rethinking Verification in Agent Harnesses
arXiv
2026-10 0 —
MatOS: An Agent Operating System for Materials Research
arXiv
2026-10 0 GitHub · ★ 12
AgentProofBench: Benchmarking Reusable Verifiers for Web Agents
arXiv
2026-10 0 —
SentryBench: A Cost-Sensitive Benchmark for Adversarial Robustness of Tool-Using LLM Agents in Public-Safety Deployments
arXiv
2026-10 0 —
EvolveMAS: A Unified Self-Evolution Framework for Decentralized Multi-Agent Systems
arXiv
2026-10 0 —
The Coordination Tax and the Heterogeneity Dividend: Break-Even Conditions for Multi-Agent LLM Pipelines
arXiv
2026-10 0 —
EMMA: Structured Episodic Memory for Multi-Agent Workflow Synthesis
arXiv
2026-10 0 —
AgentBaton: Efficient Model Collaboration in Agentic Tasks
arXiv
2026-10 0 —
Agentic AI Orchestration Framework for Spatial Intelligence: Supply Chain Deployment
arXiv
2026-10 0 —
CaliMem: Search-Efficient Data Agent via Calibrated Memory
arXiv
2026-10 0 —
What Effort Level Should I Choose? On the Economics of Reasoning Effort in LLM Agents
arXiv
2026-10 0 —
CTXAgent - Self-Controlled Context Management of LLM Agents
arXiv
2026-10 0 —
Matched Capabilities, Different Behaviors: A Controlled Study of MCP and CLI Interfaces for Language Agents
arXiv
2026-10 0 —
MultiEvoSkill: Structure-Aware Multi-Agent Skill Evolution for Generalizable Skill Artifacts
arXiv
2026-10 0 —
CodeMeepo: A Multi-Agent Workflow for Repository-Level Code Migration and Optimization
arXiv
2026-10 0 —
LLM WikiLeaks: Uncovering URL-Based Capability Extension and Security Circumvention in Agentic Message Boards
arXiv
2026-10 0 —
The Price of Scale in Proactive Memory Recall
arXiv
2026-10 0 GitHub · ★ 0
MulFCoder: Framework-conditioned Multi-agent for MLLM-based Multi-framework Front-end Code Generation
arXiv
2026-10 0 —
ParetoRSI-Gym: Can AI Agents Improve Language Models Across Multiple Domains?
arXiv
2026-10 0 —
Outcome-Aware Agents: When Does Causal Structure Help a Forward Model Foresee the Consequences of Actions?
arXiv
2026-10 — GitHub · ★ 0
AndroidFlux: Evaluating and Reward Modeling Failure Recovery Capabilities in Mobile Use Multimodal Agents
arXiv
2026-10 0 —
SEEK: Skill Extraction with Evolving Knowledge against Frontier Science Agents
arXiv
2026-10 0 —
NameTrap: Steering AI Coding Agents Toward Security Vulnerabilities via Variable Names
arXiv
2026-10 0 —
$\Delta\tau$-Bench: Pushing Agents Toward a Moving Capability
arXiv
2026-10 0 —
Holding a Steady Course: Knowledge Evolution from Expertise and Lessons for Continual Agent Learning
arXiv
2026-10 0 GitHub · ★ 1
Memory Tax: Dissecting the Net Value of Agent Memory
arXiv
2026-10 0 Project
How Do Small Coding Agents Use Code Graphs and Embeddings?
arXiv
2026-10 0 —
Build, Don't Play: Self-Improving LLM Research Agents Develop a Hearthstone Battlegrounds AI That Rivals Top Players
arXiv
2026-10 0 GitHub · ★ 228
PACE: Research Proving Agent for Adaptive Conjecture Exploration
arXiv
2026-10 0 —
SkillShift-Bench: Benchmarking Skill Learning under Environment Evolution for Web Agents
arXiv
2026-10 0 Project
LegoSR: A Unified Framework for Self-improving Agent-Guided Scientific Discovery
arXiv
2026-10 0 GitHub · ★ 33
Build or Adopt? Custom-Built vs. General-Purpose LLM Agent Harnesses for Automotive GUI Testing
arXiv
2026-10 0 —
RSI Arena: Towards Recursive Self-Improvement with Human Feedback
arXiv
2026-10 0 Project
OS-Wizard: Scaling Computer-Using Agents to Specialized Software via Knowledge-Guided Exploration
arXiv
2026-10 0 —
ReGE: Stronger Agents through Experience Synthesis
arXiv
2026-10 0 —
Learning When to Collaborate: Selective Multi-Agent Medical Reasoning via Uncertainty-Aware Routing
arXiv
2026-10 0 —
CoEvolve: Counterfactual-Guided Co-Evolution of Memory and Collaboration in Multi-Agent Systems
arXiv
2026-10 0 —
FraudSociety: A Generative Agent-Based Society for the Financial-Fraud Economy
arXiv
2026-10 0 —
ConMem: Counterfactual Multi-Scenario Probing for Resolving LLM Memory Misalignment
arXiv
2026-10 0 —
AgentOrch: How Close Can Global Orchestration Come to Step-by-Step Interaction?
arXiv
2026-10 0 —
FlashScript: Compiling Recurring Agent Workflows into Reusable Neuro-Symbolic Programs
arXiv
2026-10 0 —
Strategic Calibration in LLM Multi-Agent Systems: Audited Pivot Scoring for Truthful Elicitation
arXiv
2026-10 0 —
ProbeID: Verifying MCP Tool Identity for LLM Agents under Registry Drift
arXiv
2026-10 0 —
Can Agentic Code Review Catch Vulnerabilities Before They Are Merged?
arXiv
2026-10 — GitHub · ★ 4
Novel or Not? PatEx-Gym: Agentic Prior-Art Search for Novelty Assessment in Patent Examination
arXiv
2026-10 0 —
Distill, Debate, Discover: Grounding Multi-Agent Research Ideation in Graph-Distilled Insights
arXiv
2026-10 0 —
Estimation of Propagated Risk in LLM-based Multi-Agent Systems
arXiv
2026-10 0 —
AdaPRA: Process Reward Agents with Adaptive Rubrics for Data Science
arXiv
2026-10 0 —
A Deterministic Security Runtime for LLM Agents on MPI and Batch-Scheduled HPC Systems: Consensus-Governed, Hardware-Rooted Supervision of Every Rank
arXiv
2026-10 — —
Responsibility Boundaries for Agentic Systems: A Comparative Evaluation of Probabilistic Agentic Programming
arXiv
2026-10 0 —
Operationalizing Governed Agentic Workflows in Regulated Finance: A Customer Zero Case Study using Zafin AIOS
arXiv
2026-10 0 —
Cross-Platform Application Migration to HarmonyOS: An Agentic Pipeline with Artifact-Derived Verification
arXiv
2026-10 0 —
Multi-Agent Retrieval-Augmented Causality Assessment (MARCA) of Individual Case Safety Reports in Pharmacovigilance
arXiv
2026-10 0 —
FlexA-Mem: Budget-Adaptive Agentic Memory for LLM Agents
arXiv
2026-10 0 GitHub · ★ 1
Certified Execution Harness for Agentic AI: Safe and Least-Intrusive Petri-Net Supervisory Control Between Reasoning and Action
arXiv
2026-10 0 —
RIDAR: Safeguarding Research Integrity in Autonomous Research Agents via Automated Detection and Runtime Intervention
arXiv
2026-10 0 —
Harnessing Language Models as Optimization Modeling Agents
arXiv
2026-10 0 —
ADAPT for Science: A Multi-Agent System for Self-Evolving Scientific Optimization
arXiv
2026-10 0 —
Governed Self-Evolution for Autonomous Investing: A Multi-Agent LLM System with an Invariant Core
arXiv
2026-10 0 GitHub · ★ 14
HERD: Harness-Evolving Recursive Distillation for Continual Learning
arXiv
2026-10 0 GitHub · ★ 4
From Prose to Properties: Testing Research Claims with ARATest for Agent-Native Science
arXiv
2026-10 0 GitHub · ★ 6
RoleFlow: Self-Evolving Multi-Role Agentic Collaboration via Structural Adaptation
arXiv
2026-10 0 —
GAV: A scientific experimentation environment for PDE agents
arXiv
2026-10 0 GitHub · ★ 6
HGM-Dual: Lineage-Aware Guided Agent Harness Optimization for Long-Horizon Planning
arXiv
2026-10 0 —
GuideEvolve: Self-Evolving Agent Framework with Expert Guidance and 3Ts Mechanisms
arXiv
2026-10 0 —
Real PMIDs, Wrong Papers: Harness Design for Biomedical Claim-Verification Agents
arXiv
2026-10 0 GitHub · ★ 3
PreCoMem: Predictive Cognitive Memory for Self-Evolving Long-Term Dialogue Agents
arXiv
2026-10 0 GitHub · ★ 1
Recursive Self-Improvement on a Budget: Scoring Code Edits Before They Run
arXiv
2026-10 0 —
Harness Scaling for Generalizable Agentic Reinforcement Learning
arXiv
2026-10 0 —
TrainBridge: Agentic NPU Training Optimization Guided by GPU Compilation Evidence
arXiv
2026-10 0 —
Evolving with Open Worlds: Towards Recursive Self-Improvement for Future Forecasting
arXiv
2026-10 0 —
BIRD-RL: Scaling Agentic Reinforcement Learning over Stateful Data-Centric Environments
arXiv
2026-10 0 —
Harness Self-Evolution for Long-Horizon Terminal Agents
arXiv
2026-10 0 —
MaD-RSI: Model-as-Data for Recursive Self-Improvement of Agent Harnesses
arXiv
2026-10 0 —
COMPASS: Routing via Capability-Oriented Model Profiling with Adaptive Search, Selection, and Tool Use
arXiv
2026-10 0 —
Evolving Agent Interfaces
arXiv
2026-10 0 GitHub · ★ 12,861
Self-Evolving Static Analysis via LLM Pseudo-Labeling
arXiv
2026-10 0 —
AgentPolicyForge: From Executable Environments to Policy Benchmarks and Adaptive Guards
arXiv
2026-10 0 —
Self-Improving Agents with World Model Predictive Paths
arXiv
2026-10 0 —
Forging More Tasks into Better Harnesses: Agentic Harness Evolution via Successive Scale Racing
arXiv
2026-10 0 —
FALCA: Falsification-Aware Reinforcement Learning with Hierarchical Credit Assignment for Long-Horizon Deep Search Agents
arXiv
2026-10 0 —
ChartEvo: Self-Evolving Agent Harnesses for Long-Tail Chart Reasoning
arXiv
2026-10 0 —
DuplexLedger: Benchmarking Transactional Memory in Full-Duplex Speech Agents
arXiv
2026-10 0 GitHub · ★ 4
RaspAssistant as an Agentic Framework for Automating Adsorption Simulation Research in Porous Materials
arXiv
2026-10 0 —
Recoverability and Verifier Strength: Two Measured Preconditions for Unattended Agent Self-Improvement
arXiv
2026-10 0 —
KPHarness: Co-Evolving Knowledge and Probing for Long-Horizon Gaming Harnesses
arXiv
2026-10 0 —
GBClaw: An agentic AI framework for atomistic grain boundary research and mechanistic discovery
arXiv
2026-10 0 —
VisualEvolve: A Skill Self-Evolution Framework for Visual Reasoning
arXiv
2026-10 0 —
World2HOSI: A Multi-Expert Harness for Long-Horizon Human-Object-Scene Interaction Generation
arXiv
2026-10 0 —
Self-Evolving Agents through Privileged Retrospective Distillation
arXiv
2026-10 0 —
Measure First, Then Allocate: Calibrated Rollout Budgets for MCP Agents in Reinforcement Learning
arXiv
2026-10 0 —
Object-Oriented Harness: Evolving Agent Harnesses through Object-Oriented Design
arXiv
2026-10 0 —
Learning What to Remember: Resource-Efficient Self-Improvement for Lifelong Agents
arXiv
2026-10 0 GitHub · ★ 3
Reliable Before Profitable: QuantHarness for Governing Financial Strategy Development with LLM Agents
arXiv
2026-10 0 —
EvoSkill v2: Fully Agentic Skill Evolution from Benchmark Adaptation to a Stateful Evolver
arXiv
2026-10 0 —
OpenSaC: A Python Library for Search as Code in Deep Research Agents
arXiv
2026-10 0 GitHub · ★ 4
OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory
arXiv
2026-10 0 —
HarnessRL: Co-Evolving Policies with a Just-in-Time Training Harness for Open-Ended RL
arXiv
2026-10 0 GitHub · ★ 61
HarnessPro: Recursive Harness Self-Improvement with Pareto Optimization for Performance-Cost Trade-offs
arXiv
2026-10 0 GitHub · ★ 142
Cassette-Editor: An Agent Harness for Editing Video the Way You Do
arXiv
2026-10 — —
Epi: Towards a Persistent, Self-Improving Agent for Autonomous Research
arXiv
2026-10 0 GitHub · ★ 12
Design and Cross-Domain Evaluation of an Agent Execution Harness
arXiv
2026-10 0 —
Symbolic Constraint Agents: Mining Formal Tool-Call Constraints to Prevent Agent Errors
arXiv
2026-10 0 —
Bud ContextCompact 2.0: Context Compaction for Agent Success and Accuracy with Small Language Models and Constrained Context Windows
arXiv
2026-10 0 —
Bridging Concepts: Multi-Agent Reasoning over Scientific Concept Graphs for High-Impact Research Prediction
arXiv
2026-10 0 —
Compile Once, Run Cheap: Frozen, Portable Skills for Embodied Agents, and What Recursive Self-Improvement Adds
arXiv
2026-10 0 GitHub · ★ 1
Trackable Skill Library Lifecycle Management for Agentic Reinforcement Learning
arXiv
2026-10 0 —
CoEvo-RSI: When Harnesses Evolve, Which Models Should Follow?
arXiv
2026-10 0 —
Who Convinced Whom? Tracing How LLMs Change Their Minds in Multi-Agent Systems
arXiv
2026-10 0 —
ReTRACE: Feedback-Guided LLM Agent in a Chemistry Harness for Retrosynthesis Planning
arXiv
2026-10 0 —
Selm: Self-Evolving Library Management for Multi-Skill Agent Optimization
arXiv
2026-10 0 —
Learning to Compose: Recursive Self-Improvement of Shared Executable Stacks for Zero-Shot Long-Horizon Robot Manipulation
arXiv
2026-10 0 —
MELD: Recursive Self-Improvement via Hierarchical Coordination for Multi-Agent Scientific Discovery
arXiv
2026-10 0 —
Hippo: Training-Free Agent Self-Evolution via Hippocampal Replay
arXiv
2026-10 0 —
Organon : From Evolutionary Search to Recursive Self-Improving Agents for Scientific Discovery
arXiv
2026-10 0 GitHub · ★ 0
Self-Evolving Coding Agents via Harness-Policy Optimization
arXiv
2026-10 0 GitHub · ★ 56
DrugHarness: An Evolvable Agent Harness for Computational Drug Discovery
arXiv
2026-10 0 —
From Trajectories to Differentiated Skills: Cognitive Differentiation for Self-Improving Agents
arXiv
2026-10 0 —
Darwin-Claw: Environment-Adaptive Experience Consolidation for Recursively Self-Evolving Agents
arXiv
2026-10 0 —
Optimist Deep Research: An Iterative, State-Centric Agent for Autonomous Literature Research
arXiv
2026-10 0 —
WebCoder: Scaling General Frontend Development with Artifact-Grounded Agentic Reinforcement Learning
arXiv
2026-10 0 —
Reward Engine: Reward-Centric Self-Evolution for Open-Ended Tool Agents
arXiv
2026-10 0 —
MuninAI: A Self-Hosted Agentic Framework for Independent Research Groups
arXiv
2026-10 0 GitHub · ★ 0
CRAFT: Corrective and Robust Multi-Agent Framework for Text-to-Parametric CAD
arXiv
2026-10 — GitHub · ★ 1
Federation over Harness
arXiv
2026-10 0 —
Agentic Interpretation: Harness-Governed Evidence Construction for Software Agents
arXiv
2026-10 0 —
R$^2$Orch: Recursive Self-Improvement for Agent Orchestration via Self-Play within a Skill-Internalization Loop
arXiv
2026-10 0 GitHub · ★ 13
NoveltyScope: A Multi-Agent Research Assistant for Evidence-Grounded Novelty Assessment of Scientific Papers
arXiv
2026-10 0 —
Skip the Compressor: Coding Agents Fix More Issues When They Pick Whole Files
arXiv
2026-10 0 —
A Self-Improving Agent that Grows its Own DSL: Oracle-Free Operator Induction for Exact Question Answering
arXiv
2026-10 0 —
CausalEvo: Causal Skill Self-Evolution for Health LLM Agents
arXiv
2026-10 0 GitHub · ★ 0
Verifier-Harness Co-Evolution for Training-Free Self-Improvement on Open-Ended Tasks
arXiv
2026-10 0 GitHub · ★ 1
SEAR: Self-Evolving Agentic Robotics
arXiv
2026-10 0 —
Coupled Harness--Model Evolution for Scientific Equation Discovery
arXiv
2026-10 0 —
Memorix: Managing Memory Selections for AI Agents
arXiv
2026-10 — —
Drafting Agents, Not Just Tokens: Speculative Recursive Self-Improvement for Agentic Systems
arXiv
2026-10 0 GitHub · ★ 6
Lessons from Luck: Do LLM-Written Lessons Carry Chance into an Agent's Next Decision?
arXiv
2026-10 0 —
Exposure Is Not Commitment: Double-Stratified Evaluation of Latent Monitors for Tool-Using Agents
arXiv
2026-10 0 GitHub · ★ 0
Harmony Harness: Multi-Objective Self-Evolution of Agent Harnesses
arXiv
2026-10 0 —
Triage-PiEvo: Evidence Admission for Principle-Evolving Scientific Agents
arXiv
2026-10 0 —
Evolving to Match Capabilities: Improving Harness Self-Evolution via Skill Adaptation
arXiv
2026-10 0 Project
Proactive Agentic Orchestration
arXiv
2026-10 0 GitHub · ★ 2
Harness^2: Recursive Agent Harnessing for an Open World
arXiv
2026-10 1 GitHub · ★ 22,232
RSI-Anything: Unlocking Recursive Self-Improvement with World Models
arXiv
2026-10 0 GitHub · ★ 1,106
Memento 3: Model-Based Recursive Self-Improvement through Reflective Rulebooks
arXiv
2026-10 0 —
Harness Evolution Hits a Ceiling: When Weight Training Should Begin
arXiv
2026-10 0 —
Recursive Self-Improvement through Multi-Agent Self-Supervision
arXiv
2026-10 0 —
ReSI: Recursive Safety Improvement toward Resistant and Resilient AI
arXiv
2026-10 0 —
SLICE-Mem: Salience-Gated Lightweight Information Curation for Efficient LLM Agent Memory
arXiv
2026-10 0 —
UMAS: System-Level Uncertainty Quantification for Multi-Agent LLM Systems
arXiv
2026-10 0 GitHub · ★ 0
Recursive Semantic Divergence for LLM Agent Consistency
arXiv
2026-10 0 GitHub · ★ 0
RADAgent: Automating RADseq Pipelines with Private Open-Source LLMs
arXiv
2026-10 0 GitHub · ★ 0
Stateless Language Agents: Scaling Long-Horizon Automated Research
arXiv
2026-10 0 —
ImproveAnyTask: An Autonomous Post-Training Harness for Iterative Model Self-Improvement
arXiv
2026-10 0 —
AgentDiscover: Autonomous Discovery with Minimal Search Scaffolding
arXiv
2026-10 0 GitHub · ★ 8
Complex Agents, Shallow Tests: Demystifying and Enhancing Test Adequacy of Agent Harness in the Wild
arXiv
2026-10 0 —
MESH-Harness: Self-Improving Agent Harnesses via Bandit-Guided Compositional Evolution
arXiv
2026-10 0 —
Recursive Harness Self-Improvement for Frontier Reasoning Data Synthesis
arXiv
2026-10 0 —
Learning What to Investigate Next: Meta-Reasoning for Long-Horizon Research Agents
arXiv
2026-10 0 —
Safety Must Survive Self-Improvement: Why Failures Persist and How Agents Recover
arXiv
2026-10 0 —
Auditing Web Agent Evaluation on WebArena-Lite: Human Review of Outcomes and Trajectories
arXiv
2026-10 0 —
RSIGame: Autonomous Agentic Game Development with Recursive Self-improvement
arXiv
2026-09 0 —
TIAgent: From Natural Language to Grounded Agentic Workflows for Computational Pathology
arXiv
2026-09 0 —
SelfSearch: Reward-Free Search for Self-Improving Agents
arXiv
2026-09 0 —
Self-Evolving Harness on Multiple Tasks with the Agent as Its Own Optimizer
arXiv
2026-09 0 —
Mixture of Self-Improving Branches For Agent Harness Optimization
arXiv
2026-09 0 —
Learning Meta-Skills for Agent Harness Design in Test-Time AI4AI
arXiv
2026-09 0 —
Collaborative Principle Evolution via Evidence Transfer for Scientific Discovery
arXiv
2026-09 0 —
Recursive Harness Distillation across Agents for Robot Manipulation
arXiv
2026-09 0 —
Breaking the Environment Wall: A Unified Framework for Preparing and Evolving Agent-Native Environments
arXiv
2026-09 0 —
LLM Agents Can Easily Tamper With Their Own Traces
arXiv
2026-09 0 —
Recursive self-improvement of AI research agents
arXiv
2026-09 0 —
RRSI: Regularized Recursive Self-Improvement of Agent Harnesses
arXiv
2026-09 0 GitHub · ★ 1,707
Total Cost of Agency: Exact Attribution of Memory Injection Cost in Multi-Agent LLM Workflows
arXiv
2026-09 0 GitHub · ★ 0
Bridging Static and Agentic RAG for Taiwanese Historical Question Answering
arXiv
2026-09 0 —
SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness
arXiv
2026-09 0 GitHub · ★ 3,631
ModularRSI: Modular and Generalizable Recursive Harness Self-Improvement
arXiv
2026-09 0 —
RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments
arXiv
2026-09 0 —
NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness
arXiv
2026-09 0 GitHub · ★ 1,694
Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement
arXiv
2026-09 0 GitHub · ★ 190
HarnessEvolve: Learning from Reference Trajectories for Reliable Agent Self-Evolution
arXiv
2026-09 0 —
AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation
arXiv
2026-09 0 GitHub · ★ 34
WHALE: A Simple Recipe for Joint Harness-Weight Optimization
arXiv
2026-08 0 GitHub · ★ 63
Context as an Environment: Programmatic Context Management for Long-Horizon Agents
arXiv
2026-08 0 —
Agent Lightning v1.0: Towards Harnessed Agentic RL
arXiv
2026-08 0 —
Self-Evolving Embodied Agents via Skill-Harness Evolution
arXiv
2026-08 0 —
PAST-Bench: Benchmarking the Foundations of Recursive Self-Improvement in Personal Agents
arXiv
2026-08 0 GitHub · ★ 35
HarnessCompass: Guiding Automatic Harness Evolution toward Generalizable and Effective Agent Harnesses
arXiv
2026-08 0 —
PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents
arXiv
2026-08 4 —
Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses
arXiv
2026-08 10 GitHub · ★ 265
Prime Agent: A Self-Improving RLM Harness
arXiv
2026-08 17 GitHub · ★ 22,554
Recursive Self-Improvement in AI: From Bounded Self-Refinement to Autonomous Research Loops
—
2026-07 38 —
Kimi K3: Open Frontier Intelligence
arXiv
2026-07 103 GitHub · ★ 9,041
Recursive harness self-improvement
arXiv
2026-07 31 —
ACM: Agentic Context Management for Long Horizon Tasks
arXiv
2026-07 13 GitHub · ★ 46
CompactionRL: Reinforcement Learning with Context Compaction for Long-Horizon Agents
arXiv
2026-07 15 —
Structured Feedback Improves Repair in an LLM Agent Loop
arXiv
2026-07 3 —
Self-Improvements in Modern Agentic Systems: A Survey
—
2026-07 19 GitHub · ★ 604
MetaSkill-Evolve: Recursive Self-Improvement of LLM Agents via Two-Timescale Meta-Skill Evolution
arXiv
2026-07 23 —
Rethinking the Evaluation of Harness Evolution for Agents
arXiv
2026-07 51 GitHub · ★ 50
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-07 8 GitHub · ★ 870
Agon: An Autonomous Large-Scale Omnidisciplinary Research System Built on Prompt Economy
arXiv
2026-06 0 GitHub · ★ 54
HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry
arXiv
2026-06 49 —
The Past Is Prologue: A Plug-in Controller for Selective Updates in Sequentially Evolving LLM Memory
arXiv
2026-06 1 —
From Question Answering to Task Completion: A Survey on Agent System and Harness Design
arXiv
2026-06 13 —
Agent Harness for Large Language Model Agents: A Survey
Preprints
2026 3 GitHub · ★ 377
Scaffold Effects on GAIA: A Controlled Comparison
arXiv
2026-06 7 —
Context Compression for LLM Agents: A Survey of Methods, Failure Modes, and Evaluation
Preprints
2026 0 —
The Verification Horizon: No Silver Bullet for Coding Agent Rewards
arXiv
2026-06 8 —
Self-Harness: Harnesses That Improve Themselves
arXiv
2026-06 100 GitHub · ★ 137
Stop Comparing LLM Agents Without Disclosing the Harness
Second Workshop on Agents in the Wild: Safety, Security, and Beyond
2026 8 —
Are We Ready For An Agent-Native Memory System?
arXiv
2026-06 17 GitHub · ★ 150
Evolve as a Team: Collaborative Self-Evolution for LLM-based Multi-Agent Systems
arXiv
2026-05 0 GitHub · ★ 64
Learning from Repair Experience: Self-Evolving Agents for Automated Vulnerability Repair
ICSE 2027
2026-05 0 GitHub · ★ 0
MOSS: Self-Evolution through Source-Level Rewriting in Autonomous Agent Systems
arXiv
2026-05 12 GitHub · ★ 29
Ask Early, Ask Late, Ask Right: When Does Clarification Timing Matter for Long-Horizon Agents?
arXiv
2026-05 5 —
From Raw Experience to Skill Consumption: A Systematic Study of Model-Generated Agent Skills
arXiv
2026-05 20 —
Code as Agent Harness
arXiv
2026-05 47 GitHub · ★ 768
SkillOS: Learning Skill Curation for Self-Evolving Agents
arXiv
2026-05 53 —
Adapting the Interface, Not the Model: Runtime Harness Adaptation for Deterministic LLM Agents
arXiv
2026-05 29 GitHub · ★ 227
LoopTrap: Termination Poisoning Attacks on LLM Agents
arXiv
2026-05 1 —
Learning Agent-Compatible Context Management for Long-Horizon Tasks
arXiv
2026-05 15 —
SpecBench: Measuring Reward Hacking in Long-Horizon Coding Agents
arXiv
2026-05 29 GitHub · ★ 17
Toward autonomous long-horizon engineering for ML research
arXiv
2026-04 14 GitHub · ★ 146
Squeez: Task-Conditioned Tool-Output Pruning for Coding Agents
arXiv preprint arXiv:2604.04979
2026-04 2 GitHub · ★ 24
Dive into Claude Code: The Design Space of Today's and Future AI Agent Systems
arXiv
2026-04 48 GitHub · ★ 2,210
Escher-Loop: Mutual Evolution by Closed-Loop Self-Referential Optimization
arXiv
2026-04 9 GitHub · ★ 8
Reinforced Agent: Inference-Time Feedback for Tool-Calling Agents
Proceedings of the Fifth Workshop on Generation, Evaluation and Metrics (GEM)
2026-04 7 —
From Agent Loops to Structured Graphs:A Scheduler-Theoretic Framework for LLM Agent Execution
arXiv
2026-04 3 —
ContextBudget: Budget-Aware Context Management for Long-Horizon Search Agents
arXiv preprint arXiv:2604.01664
2026-04 14 GitHub · ★ 10
ContextWeaver: Selective and Dependency-Structured Memory Construction for LLM Agents
arXiv preprint arXiv:2604.23069
2026-04 4 —
Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
arXiv preprint arXiv:2604.08224
2026-04 73 —
Harness Engineering for Language Agents: The Harness Layer as Control, Agency, and Runtime
Preprints
2026-03 0 —
Meta-Harness: End-to-End Optimization of Model Harnesses
arXiv
2026-03 305 GitHub · ★ 1,248
Natural-Language Agent Harnesses
arXiv
2026-03 58 —
Bilevel Autoresearch: Meta-Autoresearching Itself
arXiv
2026-03 8 GitHub · ★ 209
Schema First Tool APIs for LLM Agents: A Controlled Study of Tool Misuse, Recovery, and Budgeted Performance
arXiv
2026-03 8 GitHub · ★ 0
DARWIN: Dynamic Agentically Rewriting Self-Improving Network
arXiv
2026-02 1 GitHub · ★ 0
ReCreate: Reasoning and Creating Domain Agents Driven by Experience
ACL 2026
2026-01 0 GitHub · ★ 169
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
arXiv preprint arXiv:2601.16746
2026-01 56 GitHub · ★ 319
Beyond Static Summarization: Proactive Memory Extraction for LLM Agents
arXiv preprint arXiv:2601.04463
2026-01 20 —
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12 297 —
Step-DeepResearch Technical Report
arXiv preprint arXiv:2512.20491
2025-12 13 GitHub · ★ 575
Towards a Science of Scaling Agent Systems
arXiv
2025-12 153 GitHub · ★ 63
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-12 31 GitHub · ★ 44
PARC: An Autonomous Self-Reflective Coding Agent for Robust Execution of Long-Horizon Tasks
arXiv
2025-12 3 —
Solving a Million-Step LLM Task with Zero Errors
arXiv preprint arXiv:2511.09030
2025-11 26 GitHub · ★ 47
LongCodeZip: Compress Long Context for Code Language Models
2025 40th IEEE/ACM International Conference on Automated Software Engineering (ASE)
2025-10 51 GitHub · ★ 170
ACON: Optimizing Context Compression for Long-horizon LLM Agents
arXiv preprint arXiv:2510.00615
2025-10 145 GitHub · ★ 130
Scaling Long-Horizon LLM Agent via Context-Folding
arXiv preprint arXiv:2510.11967
2025-10 149 GitHub · ★ 201
AgentFold: Long-Horizon Web Agents with Proactive Context Management
arXiv preprint arXiv:2510.24699
2025-10 96 GitHub · ★ 20,097
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10 453 GitHub · ★ 1,423
WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research
arXiv preprint arXiv:2509.13312
2025-09 50 GitHub · ★ 20,097
ReSum: Unlocking Long-Horizon Search Intelligence via Context Summarization
arXiv preprint arXiv:2509.13313
2025-09 141 GitHub · ★ 20,097
Reducing Cost of LLM Agents with Trajectory Reduction
Proceedings of the ACM on Software Engineering
2025-09 60 —
Where LLM Agents Fail and How They can Learn From Failures
arXiv
2025-09 146 GitHub · ★ 108
Memp: Exploring Agent Procedural Memory
Findings of the Association for Computational Linguistics: ACL 2026
2025-08 95 GitHub · ★ 41
The Complexity Trap: Simple Observation Masking Is as Efficient as LLM Summarization for Agent Context Management
arXiv preprint arXiv:2508.21433
2025-08 56 —
Magentic-UI: Towards Human-in-the-loop Agentic Systems
arXiv
2025-07 60 GitHub · ★ 10,110
ReVeal: Self-Evolving Code Agents via Reliable Self-Verification
The Fourteenth International Conference on Learning Representations
2025-06 14 —
SWE-Dev: Building Software Engineering Agents with Training and Inference Scaling
Findings of the Association for Computational Linguistics: ACL 2025
2025-06 34 GitHub · ★ 69
MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents
arXiv preprint arXiv:2506.15841
2025-06 241 GitHub · ★ 353
Runaway is Ashamed, But Helpful: On the Early-Exit Behavior of Large Language Model-based Agents in Embodied Environments
Findings of the Association for Computational Linguistics: EMNLP 2025
2025-05 14 GitHub · ★ 2
Is there a half-life for the success rates of AI agents?
arXiv preprint arXiv:2505.05115
2025-05 7 —
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05 394 GitHub · ★ 2,479
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04 793 GitHub · ★ 68,321
Process Reward Models That Think
Transactions on Machine Learning Research
2025-04 120 GitHub · ★ 93
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03 756 GitHub · ★ 433
Learning to Contextualize Web Pages for Enhanced Decision Making by LLM Agents
The Thirteenth International Conference on Learning Representations
2025-03 24 GitHub · ★ 7
Process Reward Models for LLM Agents: Practical Framework and Directions
arXiv
2025-02 98 GitHub · ★ 64
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-02 1222 GitHub · ★ 1,010
Practical Considerations for Agentic LLM Systems
arXiv
2024-12 18 —
Godel Agent: A self-referential agent framework for recursive self-improvement
arXiv
2024-10 25 GitHub · ★ 239
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10 269 GitHub · ★ 845
Agent Workflow Memory
Forty-second International Conference on Machine Learning
2024-09 399 GitHub · ★ 481
Automated design of agentic systems
ICLR 2025
2024-08 444 GitHub · ★ 1,659
LLM Critics Help Catch LLM Bugs
arXiv preprint arXiv:2407.00215
2024-07 176 —
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07 550 GitHub · ★ 2,135
When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs
Transactions of the Association for Computational Linguistics
2024-06 389 —
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05 410 GitHub · ★ 4,096
JARVIS-1: Open-World Multi-Task Agents With Memory-Augmented Multimodal Language Models
IEEE Transactions on Pattern Analysis & Machine Intelligence
2023-11 231 GitHub · ★ 416
Large Language Models Cannot Self-Correct Reasoning Yet
International Conference on Learning Representations
2023-10 1339 —
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-10 1624 GitHub · ★ 25,326
Self-Taught Optimizer (STOP): Recursively self-improving code generation
Conference on Language Modeling
2023-10 193 GitHub · ★ 57
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10 714 GitHub · ★ 866
Cognitive Architectures for Language Agents
Transactions on Machine Learning Research
2023-09 556 —
ExpeL: LLM Agents Are Experiential Learners
AAAI 2024
2023-08 1144 GitHub · ★ 250
CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing
International Conference on Learning Representations
2023-05 1036 GitHub · ★ 746
AdaPlanner: Adaptive Planning from Feedback with Language Models
Advances in Neural Information Processing Systems
2023-05 264 GitHub · ★ 129
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-05 2647 GitHub · ★ 7,310
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-04 6015 GitHub · ★ 22,332
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-03 5147 GitHub · ★ 847
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-03 6117 GitHub · ★ 3,394
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-10 12662 GitHub · ★ 4,260

🧠 Model Design

Model-side interventions across plan, execute, feedback, and repair

213 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

Paper Date Citations Code
Auto-Research Agent on MSA Organization to Improve Protein-Protein Complex Structure Prediction
arXiv
2026-11 — —
CARE: Grounded Recursive Self-Improvement for Production Customer-Service Agents
arXiv
2026-11 — —
RLiD: Reinforcement Learning in the Decision Plane for Language Agents and LLMs
arXiv
2026-11 — —
SGR-OPSD: Learning from Subgoal Plans with Graph-Regularized Credit Assignment for Agentic Reinforcement Learning
arXiv
2026-11 — —
WebHarbor: Docking Real Websites for Evolving GUI Agent Environments
arXiv
2026-11 — GitHub · ★ 40
FedReady: Bounded Agents for Federation Formation
arXiv
2026-11 — —
Axion 1.0: Open Agent Foundation Models, Simplified
arXiv
2026-11 — —
CUA-Master: Scaling Computer-use Agents through Open-World Recursive Improvements
arXiv
2026-11 — —
From Local Skills to Long-Horizon Web Tasks: Progressive Skill Exploration for LLM Web Agents
arXiv
2026-11 — —
BLPO: Beyond-Local Policy Optimization for Long-Horizon LLM Agents
arXiv
2026-11 — GitHub · ★ 0
Think with Skills: Pseudocode Planning Before Execution for Advanced Reasoners
arXiv
2026-11 — —
Parallelism-Aligned Pruning and Round-Aware Context Reuse for On-Device Multimodal Agents
arXiv
2026-11 — —
Cumulative and Audited Guardrail Tool Evolution for LLM Agent Safety
arXiv
2026-11 — —
Can LLM Agents Be Forward-Deployed Engineers? Requirement Discovery and Delivery for Enterprise Text-to-SQL
arXiv
2026-11 — —
Hindsight Credit Assignment over Trees for Agentic RL
arXiv
2026-11 — —
Beyond Accuracy: How Quantization Affects Coding Agents
arXiv
2026-11 — —
ACTOR: Action-Centered Temporal Organization for Literary Role-Playing Agents
arXiv
2026-11 — GitHub · ★ 5
Meet Students Where They Are: Student-Prefix Teacher Adaptation for On-Policy Distillation
arXiv
2026-11 — —
Replay for LLM Continual Learning with Multi-Teacher On-Policy Distillation
arXiv
2026-11 — —
SWE-Trail: History-Guided Trajectory Collection for Coding Agent Training
arXiv
2026-11 — —
A Self-Exploring and Self-Evolving Paradigm for Adaptive Edge AI Development
arXiv
2026-11 — —
LegoEnv: Self-Evolving Agentic Environments via Modular Recombination
arXiv
2026-11 — —
Latent Harness: Compiling Agent Behaviors into Post-Block Activation Shifts
arXiv
2026-11 — —
NEIGHBOR: Aligning Service Behaviour and Evidence Use in an LLM Agent for Community Resident Services
arXiv
2026-11 — —
Better Answers, Weaker Evidence Control: Evidence Bypass in On-Policy Distillation
arXiv
2026-11 — GitHub · ★ 0
CREDO: Evidence-Conditioned Credit Assignment for Temporal Reasoning Agents
arXiv
2026-11 — GitHub · ★ 0
Can Large Language Model Agents Learn by Watching Tutorial Videos?
arXiv
2026-11 — —
Multi-Agent Collusion and the J-Space
arXiv
2026-11 — —
Order-Only On-Policy Distillation
arXiv
2026-11 — —
When Should an Agent Refresh? Adaptive Index Reuse for Efficient Long-Horizon Reasoning
arXiv
2026-11 — —
Decision-Centric Research: A Calibrated Decision Model and Benchmark for Scientific Agents
arXiv
2026-10 — —
Dependable Agents Need Hard and Fuzzy Rules
arXiv
2026-10 — —
CompSkill: Compiling Execution Experience for Skill Retrieval
arXiv
2026-10 — GitHub · ★ 0
EvoMCP: Co-evolving MCP agents and training data
arXiv
2026-10 — GitHub · ★ 0
Self-Improvement with Auxiliary Rewards: Learning from Verified Traces and Evaluating Transfer
arXiv
2026-10 — —
From Lookups to Lessons: Turning Retrieved Knowledge into Parametric Memory
arXiv
2026-10 — GitHub · ★ 0
TSBPO: Tree-Structured Branching for Policy Optimization in Interactive Language Agents
arXiv
2026-10 — —
Operon-S1: a fast decision controller for long-horizon biomedical agents
arXiv
2026-10 — —
Rome Wasn't Built in One Turn: Replay-Grounded Reward Signals for Long-Horizon Freeciv Agents
arXiv
2026-10 — GitHub · ★ 0
KEEPER: Learning Control-Sufficient Textual Memory for Long-Horizon LLM Agents
arXiv
2026-10 — —
Erase the Injected Region: Multimodal Prompt-Injection Defense with On-Policy Self-Distillation
arXiv
2026-10 — —
In-Model Context Compression with Agentic Soft Tokens for Long-Horizon LLM Agents
arXiv
2026-10 — GitHub · ★ 4
MEMENTO: Learning Context Management for Long Context Processing Agents
arXiv
2026-10 — —
DecisionRank: On-Policy Distillation for Decision-Model Rerankers
arXiv
2026-10 — —
TraceSpec: Understanding and Improving Speculative Decoding for LLM Agents
arXiv
2026-10 — —
MoLRSI: A Recursive Self-Improving AI agent for Molecular Discovery
arXiv
2026-10 0 —
From Intent to Improvement: Agentic Dataset Search for Better Model Training
arXiv
2026-10 0 GitHub · ★ 2
Online Dense Reinforcement Learning with Planning-Grounding Agent for UI Navigation on Live IOS Apps
arXiv
2026-10 0 —
Where to Learn and How Far to Roll Out: Efficient Adaptive Training for GUI Agents
arXiv
2026-10 0 —
Mage-VL-Cowork: A Full Training Recipe to Learn Hybrid Computer Use From Evolved Harnesses
arXiv
2026-10 — Project
Kerkoporta: Injecting Structured-Output Backdoors in Reasoning Coding Agents
arXiv
2026-10 — —
AutoHebb: Self-Modifying Neural Networks that Zero-Shot Infer and Continually Learn
arXiv
2026-10 — —
Retrieval as Traversal: Value-Indexed Memory for Stateful Long-Context Agents
arXiv
2026-10 0 —
EpiAgent: Epistemic Self-Play for LLM Agents
arXiv
2026-10 0 —
Before the Next Rollout: Diagnosing Skill Utility Shifts from Policy Updates
arXiv
2026-10 0 —
MemSteer: Turning User Histories into Supervision for Agent Memory Optimization
arXiv
2026-10 0 —
When to Assist and What to Suggest: Joint Gating and Memory-Grounded Hint Generation in One Compact Decoder
arXiv
2026-10 0 —
Gym-Anything for Robotics: Scaling physical simulations with digital agents
arXiv
2026-10 0 Project
TaskFrame: Connecting Task-Level Planning with Frame-Level Control for Game Agents
arXiv
2026-10 0 —
Learning Calibrated Confidence for Multi-Agent Collaboration
arXiv
2026-10 0 —
Heterogeneous Co-Evolution Learning for Tool-Efficient Search Agents with Zero Labels
arXiv
2026-10 0 —
Every Token Needs Its Own Teacher: Multi-teacher Adaptive On-policy Self-distillation
arXiv
2026-10 0 GitHub · ★ 1
Surprise Alone Learns Lies: Evidence-Gated Continual Learning for LLMs from Streaming Claims
arXiv
2026-10 0 GitHub · ★ 0
Aligning Autoresearch: Co-Improvement between Agents and Humans
arXiv
2026-10 0 —
A-RSI: Adaptive Task Refresh for Zero-Data Multimodal Self-Improvement
arXiv
2026-10 0 —
SCOPE: Selective Critical-Step On-Policy Self-Distillation for Agentic Reinforcement Learning
arXiv
2026-10 0 —
MAS-Loop: Beyond One-Shot Orchestration towards Self-Evolving Multi-Agent Systems
arXiv
2026-10 0 —
Weaken to Strengthen: Weakening-Induced On-Policy Self-Distillation for Large Reasoning Models
arXiv
2026-10 0 GitHub · ★ 1
Predict the Reward, Not the World: World Reward Models for ML Agents
arXiv
2026-10 0 —
Distilling the Shape of Uncertainty: What On-Policy Distillation Learns and How to Predict It
arXiv
2026-10 0 GitHub · ★ 0
On-Policy Self-Distillation with Teacher Evolution
arXiv
2026-10 0 —
WeVisCut: The Whole Editing Room in One Agent From Narration to Long-Form Video
arXiv
2026-10 0 —
Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AI
arXiv
2026-10 0 —
CoSTA: Co-Evolving Self-Play Timeline Agents for Complex Temporal Knowledge Graph Question Answering
arXiv
2026-10 0 —
Two Birds with One Stone: Skill-Augmented Generation via Unified Retrieval and Utilization
arXiv
2026-10 0 —
ATI-OPD: Adaptive Teacher Intervention for Stable Long-Sequence On-Policy Distillation
arXiv
2026-10 0 —
How Much Do Teacher Bridges Matter in Interleaved On-Policy Distillation?
arXiv
2026-10 0 —
GARDEN: Generalist Autonomous Reward Design Through Evidence Navigation for Cooperative Multi-Agent Reinforcement Learning
arXiv
2026-10 0 GitHub · ★ 0
Clearing the FoG: Training KG Agents to Retrieve the Evidence Behind Their Answers
arXiv
2026-10 0 —
WorkFactory: Turning Professional Intents into Executable Work for Scalable Agent Training
arXiv
2026-10 0 GitHub · ★ 20
Action-Value Calibration via Continuation Sharing for Long-Horizon Agentic Reinforcement Learning
arXiv
2026-10 0 GitHub · ★ 0
Agentic Backdoors via Pretraining Poisoning
arXiv
2026-10 0 GitHub · ★ 8
EnvSched: Environment-Aware Scheduling for Rollout-Efficient Agent Reinforcement Learning
arXiv
2026-10 0 —
Your Policy Is Secretly a Harness: The Decision Geometry of Agent Interfaces
arXiv
2026-10 0 GitHub · ★ 1
SkillMem: Compact External Skill Memory for Latent Multi-Agent Reasoning
arXiv
2026-10 0 —
WebAnything: From the Wild Web to Scalable Agent Environments
arXiv
2026-10 0 GitHub · ★ 6
Agent-Conditioned Routing: Diverse Reasoning Paths Within One Frozen Model
arXiv
2026-10 0 —
Vision-Language Agents Can Learn in Their Own Latent Worlds
arXiv
2026-10 0 GitHub · ★ 0
GUI-JEPA: Candidate-Conditioned JEPA Latents as a Fast Action Policy for Mobile GUI Agents
arXiv
2026-10 0 GitHub · ★ 1
RouteDRAG: Learning to Route and Control Agentic Execution for Multimodal Document RAG
arXiv
2026-10 0 GitHub · ★ 2
Gym-Anything-RT: Scaling Real-Time Environments for Vision-Language Agents
arXiv
2026-10 0 —
Self-Keyed In-Parameter Memorization for External Memory-Free Dialogue Recall in Frozen Language Models
arXiv
2026-10 0 —
Proposing Better Rollouts for On-Policy Distillation
arXiv
2026-10 0 —
Metacognitive Decoding: Efficient Inference for Diffusion Language Agents
arXiv
2026-10 0 —
DocSkill: Skill-Integrated Agentic Reasoning for Multilingual Multi-Hop Document Question Answering
arXiv
2026-10 0 —
CAMR: Compatibility-Aware Memory Replay for Continual Learning in Large Language Models
arXiv
2026-10 0 —
Agentic Data Sampling Framework for Multilingual ASR via Linguistic-Aware Error-Driven Optimization
arXiv
2026-10 0 —
The Trinity: Capability-Driven Recursive Self-Improvement for Multimodal Agents
arXiv
2026-10 0 —
Evolve on Graph: Self-Evolving Knowledge Graph Reasoning without Question Annotations
arXiv
2026-10 0 GitHub · ★ 1
PhysEvolve: Verifier-grounded Self-evolution for Physical Reasoning with Executable Worlds
arXiv
2026-10 0 —
ClinVerse: A Realistic Multi-Agent Diagnostic Environment for Training and Evaluating Medical Agents
arXiv
2026-10 0 —
Harness-Model Collaboration for Long-Horizon Continual Learning
arXiv
2026-10 0 —
Pretraining Knows What, Simulation Teaches How: Compositional Generalization in a Sim-Trained Robot Agent
arXiv
2026-10 0 —
MiRL: Error-Targeted Reinforcement Learning for Correcting Terminal Agent Misbehaviors
arXiv
2026-10 0 GitHub · ★ 3
EvoRouter: Cost-Efficient Multi-Agent Routing via Insight-Guided On-Policy Distillation
arXiv
2026-10 0 GitHub · ★ 5
Belief-Conditioned Multi-Agent Actor Critic for Decentralized LLM Collaboration
arXiv
2026-10 0 —
Multiscale Policy Optimization for Long-Horizon LLM Agents
arXiv
2026-10 0 —
SKALOS: Learning to Distinguish Similar Skills with Capability Graphs
arXiv
2026-10 0 —
RepoTrace: Improving Requirement Tracing in Multi-Round Agent Interactions
arXiv
2026-10 — —
Joint Latent Reasoning and Observation for Agentic Video Understanding
arXiv
2026-10 0 —
AIPC: Evidence-Guided Agent Workflows for PyTorch Project Deployment
arXiv
2026-10 0 —
OmniBrain-0: A Unified Agentic Model for Embodied Intelligence
arXiv
2026-10 0 Project
Self-Evolution Reasoner: Continuous Optimization via Policy-Intrinsic Exploration and Exploitation
arXiv
2026-10 — GitHub · ★ 0
CaliMem: Search-Efficient Data Agent via Calibrated Memory
arXiv
2026-10 0 —
Variational Cognitive Memory Abstraction for Long-Horizon Vision-Language-Action Models
arXiv
2026-10 0 —
ParetoRSI-Gym: Can AI Agents Improve Language Models Across Multiple Domains?
arXiv
2026-10 0 —
AndroidFlux: Evaluating and Reward Modeling Failure Recovery Capabilities in Mobile Use Multimodal Agents
arXiv
2026-10 0 —
Steering the Teacher: Improving On-Policy Self-Distillation for Thinking Models
arXiv
2026-10 0 —
Build, Don't Play: Self-Improving LLM Research Agents Develop a Hearthstone Battlegrounds AI That Rivals Top Players
arXiv
2026-10 0 GitHub · ★ 228
More: Mode-Optimized Reasoning with Self-Adaptive Effort for Self-Evolving Agents
arXiv
2026-10 0 —
ProtAgent: Post-Training Compact Protein Tool Agents with Interaction-Level Credit Assignment
arXiv
2026-10 0 —
RSI Arena: Towards Recursive Self-Improvement with Human Feedback
arXiv
2026-10 0 Project
MTA-Zero: Self-Improving Multimodal Deep Search via Online QA-Solver Co-training
arXiv
2026-10 0 —
OS-Wizard: Scaling Computer-Using Agents to Specialized Software via Knowledge-Guided Exploration
arXiv
2026-10 0 —
Learning When to Collaborate: Selective Multi-Agent Medical Reasoning via Uncertainty-Aware Routing
arXiv
2026-10 0 —
Trajectory2Gym: Decision-Grounded Compositional Interaction Synthesis for Tool-Use Agents
arXiv
2026-10 0 —
AdaPRA: Process Reward Agents with Adaptive Rubrics for Data Science
arXiv
2026-10 0 —
HERD: Harness-Evolving Recursive Distillation for Continual Learning
arXiv
2026-10 0 GitHub · ★ 4
RoleFlow: Self-Evolving Multi-Role Agentic Collaboration via Structural Adaptation
arXiv
2026-10 0 —
Harness Scaling for Generalizable Agentic Reinforcement Learning
arXiv
2026-10 0 —
Evolving with Open Worlds: Towards Recursive Self-Improvement for Future Forecasting
arXiv
2026-10 0 —
BIRD-RL: Scaling Agentic Reinforcement Learning over Stateful Data-Centric Environments
arXiv
2026-10 0 —
AgentPolicyForge: From Executable Environments to Policy Benchmarks and Adaptive Guards
arXiv
2026-10 0 —
Scaling in Games: Continued Pre-Training For Embodied Agents In Diverse Virtual Worlds
arXiv
2026-10 0 —
Black-Box Red-Teaming of Multi-Agent Systems via Reinforcement Learning
arXiv
2026-10 0 —
FALCA: Falsification-Aware Reinforcement Learning with Hierarchical Credit Assignment for Long-Horizon Deep Search Agents
arXiv
2026-10 0 —
DuplexLedger: Benchmarking Transactional Memory in Full-Duplex Speech Agents
arXiv
2026-10 0 GitHub · ★ 4
Rewards for Budget-Aware Multi-Turn Agents That Adapt to Arbitrary Test-Time Constraints
arXiv
2026-10 0 —
Self-Evolving Agents through Privileged Retrospective Distillation
arXiv
2026-10 0 —
Measure First, Then Allocate: Calibrated Rollout Budgets for MCP Agents in Reinforcement Learning
arXiv
2026-10 0 —
Train An Imaginative Agent
arXiv
2026-10 0 —
HarnessRL: Co-Evolving Policies with a Just-in-Time Training Harness for Open-Ended RL
arXiv
2026-10 0 GitHub · ★ 61
CoworkEnv: Synthesizing Training Environments for Long-Horizon Cowork Agents
arXiv
2026-10 0 —
Indistinguishable Agents: Training Agent Privacy as Twin-World Indistinguishability
arXiv
2026-10 0 —
Trackable Skill Library Lifecycle Management for Agentic Reinforcement Learning
arXiv
2026-10 0 —
CoEvo-RSI: When Harnesses Evolve, Which Models Should Follow?
arXiv
2026-10 0 —
HybridResearcher: Bridging the Structured-Unstructured Boundary for Deep Research Agents
arXiv
2026-10 0 —
MELD: Recursive Self-Improvement via Hierarchical Coordination for Multi-Agent Scientific Discovery
arXiv
2026-10 0 —
Train Locally, Learn Together: Distributed Multi-Agent Training via ADMM
arXiv
2026-10 0 —
Arctic-SWE: Revisiting the Long Horizon Agent Training by Modeling-System Co-Design
arXiv
2026-10 0 —
Self-Evolving Coding Agents via Harness-Policy Optimization
arXiv
2026-10 0 GitHub · ★ 56
Not Every User Says It All: Training Tool-Using Agents Beyond Ideal Simulated Users
arXiv
2026-10 0 —
Self-Improving Video-to-Action Models
arXiv
2026-10 0 —
WebCoder: Scaling General Frontend Development with Artifact-Grounded Agentic Reinforcement Learning
arXiv
2026-10 0 —
Tree-Aware Posterior Distillation for Long-Horizon Agentic Reinforcement Learning
arXiv
2026-10 0 —
MultiAgent-OPD: End-to-End Training of Hierarchical Multi-Agent Systems with On-Policy Distillation
arXiv
2026-10 0 —
Recursive Reward Improvement via Adversarial Meta-Prompt Evolution
arXiv
2026-10 0 —
R$^2$Orch: Recursive Self-Improvement for Agent Orchestration via Self-Play within a Skill-Internalization Loop
arXiv
2026-10 0 GitHub · ★ 13
AlphaBet: Reinforcement Learning for LLM Event Forecasting Agents
arXiv
2026-10 0 —
Navalia: Advancing Cowork Agents through Verifiable Task Synthesis and Long-Horizon Post-Training
arXiv
2026-10 0 —
ProAS: A Progress-Aware Advantage Shaping Framework for Multi-Turn Agentic Reinforcement Learning
arXiv
2026-10 0 GitHub · ★ 17
Coupled Harness--Model Evolution for Scientific Equation Discovery
arXiv
2026-10 0 —
Drafting Agents, Not Just Tokens: Speculative Recursive Self-Improvement for Agentic Systems
arXiv
2026-10 0 GitHub · ★ 6
Proactive Agentic Orchestration
arXiv
2026-10 0 GitHub · ★ 2
RSI-Anything: Unlocking Recursive Self-Improvement with World Models
arXiv
2026-10 0 GitHub · ★ 1,106
Harness Evolution Hits a Ceiling: When Weight Training Should Begin
arXiv
2026-10 0 —
Recursive Self-Improvement through Multi-Agent Self-Supervision
arXiv
2026-10 0 —
How Data Scales in Agentic Reinforcement Learning: Laws and Synthesis Strategies
arXiv
2026-10 0 —
ReSI: Recursive Safety Improvement toward Resistant and Resilient AI
arXiv
2026-10 0 —
SLICE-Mem: Salience-Gated Lightweight Information Curation for Efficient LLM Agent Memory
arXiv
2026-10 0 —
When Agents Collude: Weak-to-Strong On-Policy Distillation for Mitigating Strategic Deception in Multi-Agent Systems
arXiv
2026-10 0 Project
ImproveAnyTask: An Autonomous Post-Training Harness for Iterative Model Self-Improvement
arXiv
2026-10 0 —
Recursive Harness Self-Improvement for Frontier Reasoning Data Synthesis
arXiv
2026-10 0 —
Harness-Aware Distillation for Small Language Model Agents
arXiv
2026-10 0 —
AutoCompact: Learning When to Compact Context in Long-Horizon Coding Agents
arXiv
2026-10 0 —
Learning What to Investigate Next: Meta-Reasoning for Long-Horizon Research Agents
arXiv
2026-10 0 —
Harness Annealing: Learning to Act with Less External Control
arXiv
2026-10 0 —
Cross-Benchmark Transfer from RL on Agentic Coding Tasks
arXiv
2026-10 0 —
Agent Error Dataset: Scaling 50,000 Error--Diagnosis Pairs for Failure Analysis and Error-Aware Post-Training
arXiv
2026-09 0 —
RSIGame: Autonomous Agentic Game Development with Recursive Self-improvement
arXiv
2026-09 0 —
Self-Play Pretraining with Zero Data
arXiv
2026-09 0 —
Breaking the Environment Wall: A Unified Framework for Preparing and Evolving Agent-Native Environments
arXiv
2026-09 0 —
Harness-Zero: Harness Distillation via Agent-as-Harness
arXiv
2026-09 0 —
NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness
arXiv
2026-09 0 GitHub · ★ 1,694
WHALE: A Simple Recipe for Joint Harness-Weight Optimization
arXiv
2026-08 0 GitHub · ★ 63
Agent Lightning v1.0: Towards Harnessed Agentic RL
arXiv
2026-08 0 —
Single-Rollout Asynchronous Optimization for Agentic Reinforcement Learning
arXiv preprint arXiv:2607.07508
2026-07 40 —
Kimi K3: Open Frontier Intelligence
arXiv
2026-07 103 GitHub · ★ 9,041
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-07 8 GitHub · ★ 870
Autodata: An Agentic Data Scientist to Create High Quality Synthetic Data
arXiv
2026-06 16 —
TREX: Automating LLM Fine-tuning via Agent-Driven Tree-based Exploration
arXiv preprint arXiv:2604.14116
2026-04 9 —
CAPO: Critic-Guided Action-Aligned Policy Optimization for Advancing LLM Agent Capabilities
arXiv preprint arXiv:2604.18401
2026-04 10 GitHub · ★ 1,714
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-03 60 GitHub · ★ 611
Hindsight Credit Assignment for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.08754
2026-03 66 —
ASI-Evolve: AI Accelerates AI
arXiv
2026-03 5 GitHub · ★ 872
Web Agent Agentic Reinforcement Learning Decision Model Under Multi-Cost and Failure Risk
arXiv
2026-01 0 —
Towards Execution-Grounded Automated AI Research
arXiv
2026-01 20 GitHub · ★ 88
IterResearch: Rethinking Long-Horizon Agents with Interaction Scaling
arXiv preprint arXiv:2511.07327
2025-11 18 GitHub · ★ 20,097
Stabilizing Off-Policy Training for Long-Horizon LLM Agent via Turn-Level Importance Sampling and Clipping-Triggered Normalization
arXiv preprint arXiv:2511.20718
2025-11 8 GitHub · ★ 0
SALT: Step-level Advantage Assignment for Long-horizon Agents via Trajectory Graph
Findings of the Association for Computational Linguistics: EACL 2026
2025-10 30 —
AgentGym-RL: Training LLM Agents for Long-Horizon Decision Making through Multi-Turn Reinforcement Learning
arXiv preprint arXiv:2509.08755
2025-09 74 GitHub · ★ 886
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06 1051 —
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05 548 GitHub · ★ 2,422
Plan-and-Act: Improving Planning of Agents for Long-Horizon Tasks
International Conference on Machine Learning
2025-03 232 GitHub · ★ 47
Reinforcement Learning for Long-Horizon Interactive LLM Agents
arXiv preprint arXiv:2502.01600
2025-02 117 —
Self-rewarding language models
arXiv
2024-01 774 —
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10 714 GitHub · ★ 866
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-05 1767 GitHub · ★ 13,061
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-05 5152 GitHub · ★ 6,087
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-02 6192 —
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-10 12662 GitHub · ★ 4,260
STaR: Bootstrapping reasoning with reasoning
NeurIPS 2022
2022-03 1176 —
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Advances in Neural Information Processing Systems
2022-01 22953 GitHub · ★ 42

📚 How We Curate

Search, screening, extraction, coding, and verification workflow

  1. Discover: survey searches, backward/forward citation chaining, and community suggestions.
  2. Verify: exact title and identifier checks against primary scholarly sources.
  3. Classify: Benchmarks, Harness Design, and Model Design, allowing justified overlap.
  4. Audit when evidence permits: stage ownership plus independent G/R/H/T coordinates.
  5. Refresh weekly: discover and deduplicate new papers, add them to the relevant collections, refresh citations and GitHub stars, and rebuild all collection lists and rankings alongside the selected research news. The growing catalog extends the original survey; its historical paper counts and fixed evidence-audit sample remain separately identified.

🔗 Related Lists

📄 Citation

If this map or its evidence audit helps your work, please cite the companion survey:

Copy BibTeX
@misc{wu2026eveai4ai,
  title   = {{AI4AI} Survey: From Long-Horizon Agents to Recursive Self-Improvement---Definitions, Reliable Horizons, and Open Problems},
  author  = {Wu, Kai and Lyu, Hao and Luo, Zhen and Wang, Chaofan and
             Ye, Siyu and Lin, Jinghao and Ji, Xiaozhong and Jiang, Boyuan and
             Wang, Shengzhi and Wang, Zihan and Ye, Yiwen and Wang, Hao and
             Wang, Zimu and Liu, Wenzhe and Wang, Ruobing and Cai, Kai and
             Xiong, Mingliang and Fang, Wen and Liu, Mingqing and
             Zhang, Yifan and Yang, Lei and Hu, Xiaobin and Liu, Qingwen},
  howpublished = {Preprints.org},
  year    = {2026},
  doi     = {10.20944/preprints202608.2108.v1},
  url     = {https://doi.org/10.20944/preprints202608.2108.v1}
}

🤝 Contributing

Have something to add? Missing a paper, official code link, or stronger primary-source evidence? Open a pull request or use the paper-suggestion form. Read the contribution guide →

Ähnliche Projekte entdecken